Retail & marketplaces
Competitive price and assortment monitoring across rival retailers.
- Daily refresh across your named competitor set
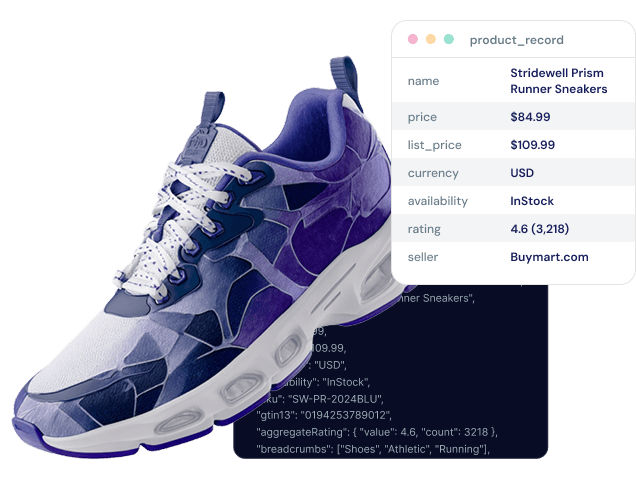
Production-grade product data — composable, not packaged.
Build it yourself on Zyte API, or have it delivered to spec by Zyte Data.
Same foundation, your choice of who runs the pipeline.


Ecommerce product data is the structured record of an item as it is listed for sale online — its name, price, availability, identifiers, imagery, ratings and seller. It is collected from public product pages across retail sites and normalised into a consistent schema. Because the same product is listed differently on every site, the value is in the normalisation, not the raw page.
The same data type, put to work differently. Ordered by how directly it applies.
Competitive price and assortment monitoring across rival retailers.
MAP compliance and digital shelf monitoring across resellers.
Market price data feeding repricing and dynamic pricing systems.
Pricing and assortment signals as an alternative data source.
Store-level price and availability tracking across delivery apps.
Market-wide pricing studies without standing up web data collection in-house.
The problem is rarely a single page. It is keeping thousands of them flowing, correctly, while the sites underneath keep changing.
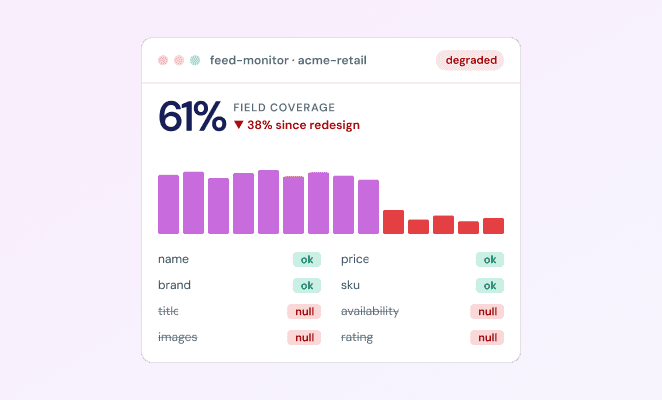
Zyte validates every feed run against your agreed schema.
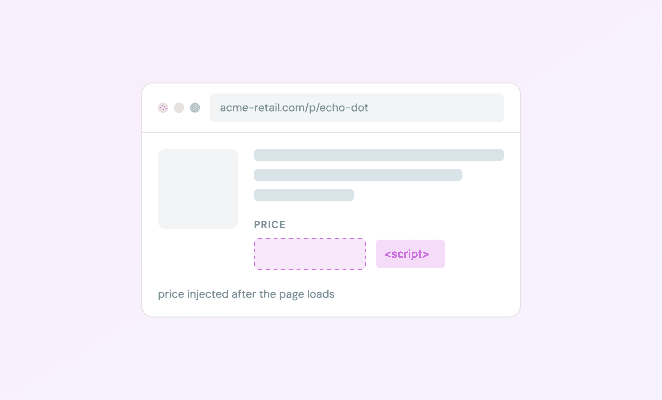
Zyte renders pages the way a real browser does, so client-side prices and stock are captured as reliably as static fields — and the right regional value, not a placeholder.
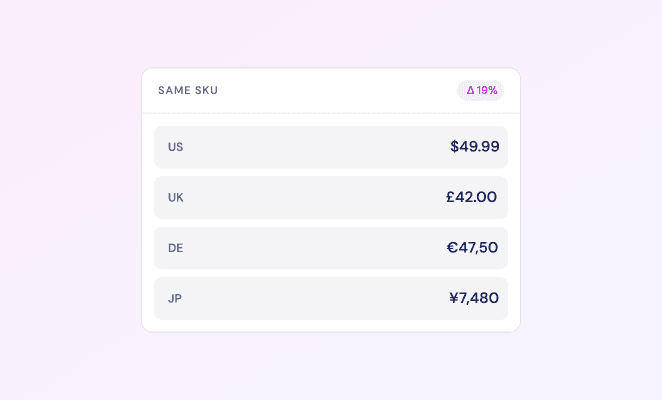
Zyte collects each price from the region and context you specify, and tags every record with the market it belongs to — so a US price is never silently compared against a UK one.
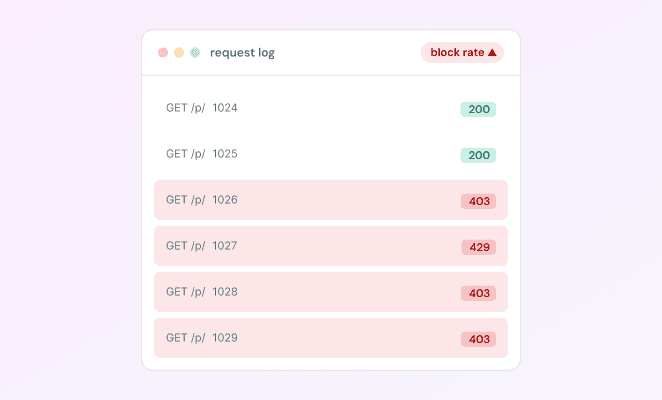
When a request is blocked, Zyte automatically re-routes and retries with a different approach, and persistent blocks escalate to the team running your feed.
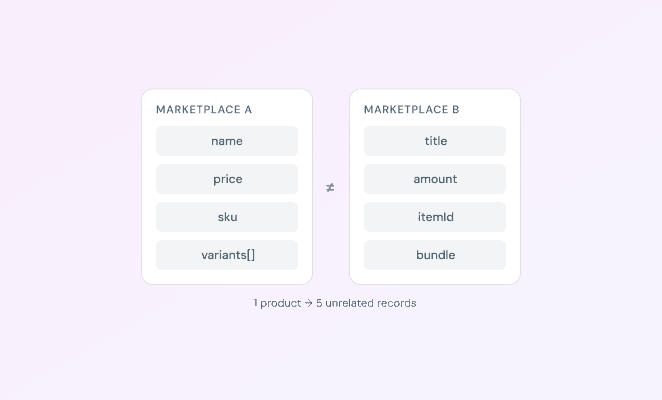
Zyte resolves each source into one consistent schema and one product identity, so a product is a product no matter how many sites it came from.
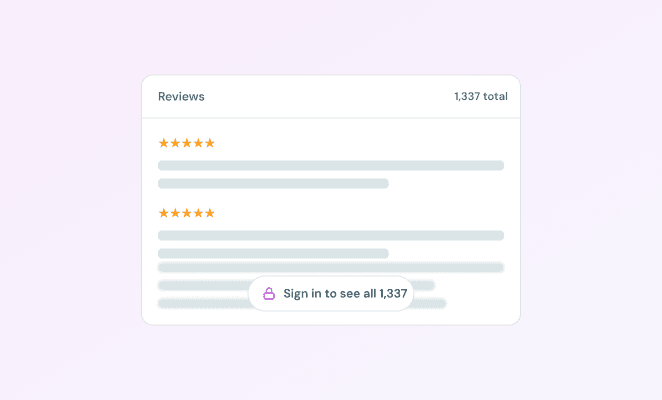
Zyte collects the full set — paginating reviews, expanding Q&A and specifications — so the feed reflects what the page can show, not just what it shows first.

Price against week-old data and roughly a third of your prices are already wrong.

A silent coverage drop hides one in six SKUs — dashboards still look clean.

A model retrained on a gappy feed degrades for weeks before anyone traces it.

Collecting personal data or ignoring site terms risks GDPR penalties up to €20M.
The request you send and the data that comes back. Pick the standard schema or a custom one mapped to your model, and read the response as a table or JSON.
POST https://api.zyte.com/v1/extract

{
  "url": "https://shop.example.com/p/compact-smart-speaker",
  "product": true
}Reliable Competitor Data Partner with Stellar Support
I have been working with Zyte's team for the last few months, and their team is fantastic. I appreciate their development speed and quality, and they run a very robust platform, producing very satisfactory results. I love the ease of the initial setup with Zyte, as they took care of all the development, and we only needed to communicate what data we needed and set up the necessary processes on our end.
Price and availability are typically delivered daily or several times a day; full catalogue attributes are usually re-crawled weekly. Real-time and on-event delivery is available where a use case needs it. We scope frequency per site to how often that site actually changes.
Every run is validated against your schema. When a site redesign changes or removes a field, validation fails closed and the feed is held rather than shipping broken data. Extraction is repaired and re-validated, usually within the same delivery window.
Blocked requests are automatically re-routed and retried, and persistent blocks escalate to the team running your feed. Because we operate many feeds across the same retailers, defence changes on major sites are usually handled centrally before they affect your feed.
JSON, JSON Lines, CSV and Parquet, delivered to Amazon S3, Google Cloud Storage, Azure Blob, a webhook, or pulled from an API — on a real-time, hourly, daily, weekly or custom schedule.
Product feeds do not collect personal data. Every project is reviewed against our ethical web data principles before kickoff, and Zyte is a founding member of the Ethical Web Data Collection Initiative.
Scoping happens in week 1, sample data in week 2, and a monitored production feed in week 3. Larger multi-region projects can take longer to reach full coverage; we confirm the timeline during scoping.
Projects are scoped on volume, complexity and frequency, then run on a predictable monthly fee after kickoff. Zyte Data is priced on successful delivery, not per request. A data specialist can give you a scoped figure after a short call.
Yes. You can request sample data for a specific URL or site below, and you receive sample data in your target schema in week 2 of any engagement before the feed goes live.