Death by DOM
Identifying and testing XPath or CSS selectors is slow and repetitive.
End the pain of parsing. Let AI understand the page and extract the data for you.
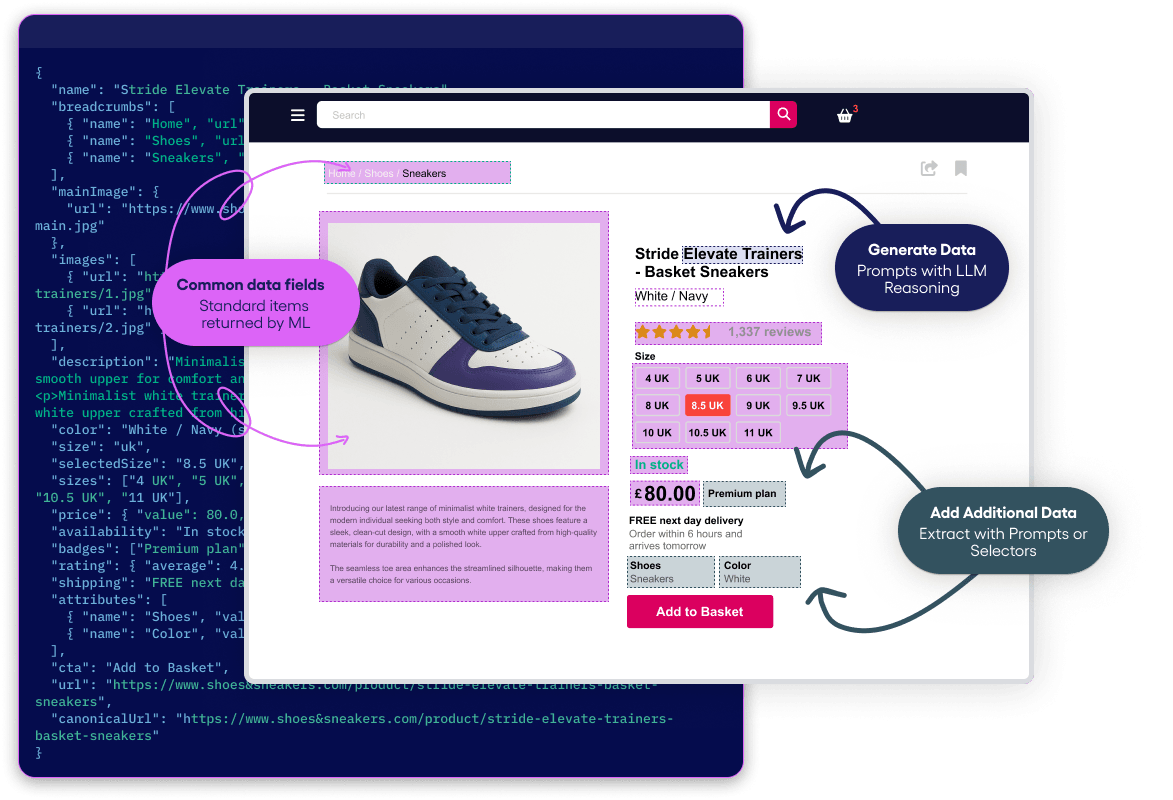
Identifying and testing XPath or CSS selectors is slow and repetitive.
Fragile selectors break when site markup changes.
Scraping dozens of sites means never-ending maintenance.
Just get the data. One parameter is all you need. "pageContent": true is your key to instantly extract the main content of any page. No selectors in sight, no HTML to clean up – just clean, slim-line content, ready for LLMs or any use case.
1{
2  "httpResponseBody": true,
3  "pageContent": true
4}
5
6def parse(self, response):
7    http_response_body: bytes = response.body
8    with open("http_response_body.html", "wb") as fp:
9        fp.write(http_response_body)
10    page_content = response.raw_api_response["pageContent"]
11 yield page_content2. Specialist
Zyte API uses machine learning models to identify and return standard data schema from a range of specific data types such as Product, Article, Job Posting, Search Engine.
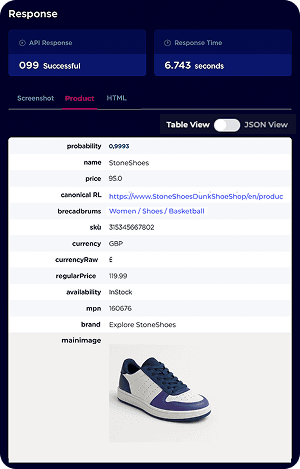
1{
2  "name": "StoneShoesbasket",
3  "product": "Stoneshoes",
4  "price": "149",
5  "currency": "USD",
6  "currencyRaw": "$",
7  "regularPrice": "199.00",
8  "availability": "InStock",
9  "sku": "A123DK9823",
10  "mpn": "code-123",
11  "gtin": [],
12  "brand": {},
13  "breadcrumbs": [],
14  "mainImage": {},
15  "images": [],
16  "description": "product description",
17  "descriptionHtml": "<article>HTML description for Product ...",
18  "aggregateRating": {},
19  "color": "Red",
20  "size": "XL",
21  "weight": {},
22  "material": "Metal, Plastic",
23}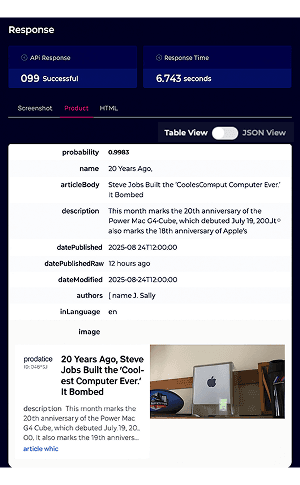
1{"article": {
2  "headline": "20 Years Ago, Steve Jobs Built the ‘Coolest Computer Ever.’ It Bombed",
3  "articleBody": "This month marks the 20th anniversary of the Power Mac G4 Cube ...",
4  "articleBodyHtml": "<article><p>This month marks the 20th anniversary of the Power Mac G4 Cube, which debuted July 19, ...",
5  "description": "This month marks the 20th anniversary of the Power Mac G4 Cube, which debuted July 19, 2000. It also marks the 19th anniversary of Apple’s",
6  "datePublished": "2025-08-24T12:00:00",
7  "datePublishedRaw": "12 hours ago",
8  "dateModified": "2025-08-24T12:00:00",
9  "dateModifiedRaw": "last modified 12 hours ago",
10  "authors": [ { "name": "Martin J. Sally" } ],
11  "inLanguage": "en",
12  "url": "/mnt/data/59a41520-bc-.png"
13}}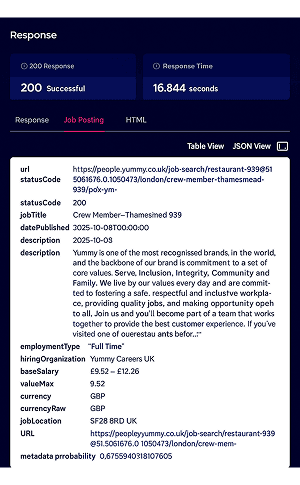
1{
2	"url": "https://people.yummy.co.uk/job-search/restaurant-939@51.5061676,0.1050473/london/crew-member-thamesmead-939/pdx-ym-3ef1bf0e-0015-4d0f-8201-000246a1a831-77342",
3	"statusCode": 200,
4	"jobPosting": {
5		"jobTitle": "Crew Member - Thamesmead 939",
6		"datePublished": "2025-10-08T00:00:00",
7		"datePublishedRaw": "2025-10-08",
8		"description":
9			"Yummy is one of the most recognised brands in the world, and the backbone of our brand is commitment to a set of…",
10		"descriptionHtml":
11			"<article><p>Yummy is one of the most recognised brands in the ll.</p><p>Join us and you’ll become part of a team that works together to provide the best customer experience. If you’ve visited one of …</p></article>",
12		"employmentType": "Full Time",
13		"hiringOrganization": { "name": "Yummy Careers UK" },
14		"baseSalary": { "raw": "£9.52 - £12.26", "valueMax": "9.52", "currency": "GBP", "currencyRaw": "£" },
15		"jobLocation": { "raw": "SE28 8RD UK" },
16		"url": "https://people.yummy.co.uk/job-search/restaurant-939@51.5061676,0.1050473/london/crew-member-thamesmead-939/pdx-ym-3ef1bf0e-0015-4d0f-8201-000246a1a831-77342",
17	},
18	"metadata": { "probability": 0.6755940318107605, "dateDownloaded": "2025-10-09T09:39:58Z" },
19	"httpResponseBody": null,
20}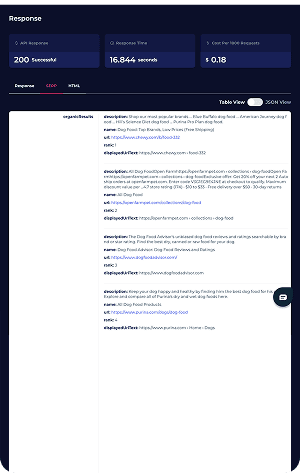
1{
2	"organicResults": [
3		{
4			"description": "Shop our most popular brands ... Blue Buffalo dog food ... American Journey dog food ... Hill’s Science Diet dog food ... Purina Pro Plan dog food.",
5			"name": "Dog Food: Top Brands, Low Prices (Free Shipping)",
6			"url": "https://www.chewy.com/b/food-332",
7			"rank": 1,
8			"displayedUrlText": "https://www.chewy.com › food-332",
9		},
10		{
11			"description": "All Dog FoodOpen Farmhttps://openfarmpet.com › collections › dog-foodOpen Farmhttps://openfarmpet.com › collections › dog-foodExclusive offer: Get 20% off your next 2 Autoship orders at openfarmpet.com. Enter code V3G1EG9E4JNE at checkout to qualify. Maximum discount value per ...4.7 store rating (17K) · $10 to $33 · Free delivery over $50 · 30-day returns",
12			"name": "All Dog Food",
13			"url": "https://openfarmpet.com/collections/dog-food",
14			"rank": 2,
15			"displayedUrlText": "https://openfarmpet.com › collections › dog-food",
16		},
17	],
18}Our most powerful capability, custom attributes extraction, puts a scraping-tuned Large Language Model behind every request.
1{
2  "pockets": {
3    "type": "integer",
4    "description": "What is the number of pockets in this garment?"
5  }
6}AI Extraction drops into your existing Zyte API workflows.

Use AI Extraction directly inside your Scrapy spiders with no extra parsing logic — just one parameter in your request and the data arrives structured.

Specialized AI models for ecommerce products, articles, jobs, and search engine results ensure accuracy and efficiency.

Get common fields by default, then customize the schema to fit your needs. Add or remove fields with either code or natural language prompts.

Forget fixing brittle selectors when sites change — our AI adapts automatically to evolving page structures.
It just works
Zyte was able to offer the most simple and effective rotating proxy solution for us. It just works.
Add AI Extraction to any request with a single parameter
1import requests
2
3api_response = requests.post(
4    "https://api.zyte.com/v1/extract",
5    auth=("YOUR_ZYTE_API_KEY", ""),
6    json={
7        "url": "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
8        "product": True,
9    },
10)
11product = api_response.json()["product"]1from base64 import b64decode
2
3import requests
4
5api_response = requests.post(
6 "https://api.zyte.com/v1/extract",
7 auth=("YOUR_ZYTE_API_KEY", ""),
8 json={
9 "url": "https://toscrape.com",
10 "httpResponseBody": True,
11 },
12)
13body: bytes = b64decode(api_response.json()["httpResponseBody"])Just get the data. One parameter is all you need. <code>"pageContent": true</code> is your key to instantly extract the main content of any page. No selectors in sight, no HTML to clean up – just clean, slim-line content, ready for LLMs or any use case.
1{
2 "httpResponseBody": true,
3 "pageContent": true
4}
5
6def parse(self, response):
7 http_response_body: bytes = response.body
8 with open("http_response_body.html", "wb") as fp:
9 fp.write(http_response_body)
10 page_content = response.raw_api_response["pageContent"]
11 yield page_contentOur most powerful capability, custom attributes extraction, puts a scraping-tuned Large Language Model behind every request.
1{
2 "pockets": {
3 "type": "integer",
4 "description": "What is the number of pockets in this garment?"
5 }
6}Explore transparent pricing designed to grow with your needs.
Add AI Extraction to any request with a single parameter
1import requests
2
3api_response = requests.post(
4 "https://api.zyte.com/v1/extract",
5 auth=("YOUR_ZYTE_API_KEY", ""),
6 json={
7 "url": "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
8 "product": True,
9 },
10)
11product = api_response.json()["product"]Describe any field in natural language and the LLM returns it.
1from base64 import b64decode
2
3import requests
4
5api_response = requests.post(
6    "https://api.zyte.com/v1/extract",
7    auth=("YOUR_ZYTE_API_KEY", ""),
8    json={
9        "url": "https://toscrape.com",
10        "httpResponseBody": True,
11    },
12)
13body: bytes = b64decode(api_response.json()["httpResponseBody"])