Media & publishers
Aggregate full-text articles and metadata from thousands of sources to power discovery, curation, and syndication products.
- Deduplicated across 10,000+ sources
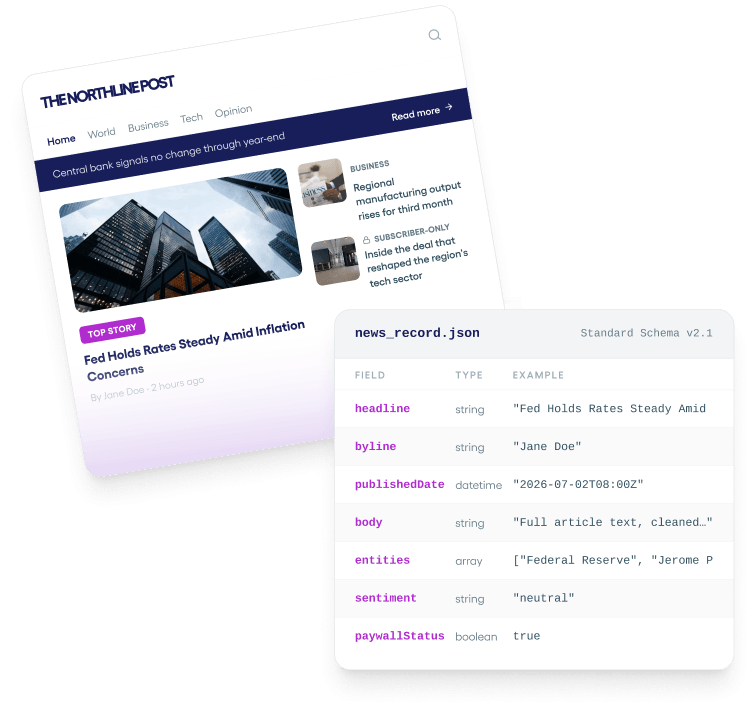
Production-grade article data: composable, not packaged. Build it yourself on Zyte API, or have it delivered by Zyte Data. Same foundation, your choice of who runs the pipeline.


News and article data is the structured record of a published piece: its headline, byline, publish date, full body text, images, and topical/entity metadata. It's collected from publisher sites and news aggregators, then cleaned of boilerplate (ads, related-article rails, comment sections, subscription prompts) and normalized into a consistent schema. Because publishers render the same story differently, and often paywall or dynamically inject parts of it, the value is in reliable, clean extraction at the article level, not the raw page.
The same data type, put to work differently. Ordered by how directly it applies.
Aggregate full-text articles and metadata from thousands of sources to power discovery, curation, and syndication products.
Track mentions, sentiment, and share-of-voice across news outlets as they publish, not a day later.
Feed earnings coverage, sector news, and executive-mention signals into research and trading workflows.
Monitor competitor coverage, product launches, and executive commentary across trade and mainstream press.
Build clean, deduplicated article corpora for NLP training, summarization, and topic models.
Monitor adverse media and regulatory coverage for KYC/AML and reputational risk screening.
The problem is rarely a single article. It's correctly separating story from clutter across thousands of publishers whose templates change without notice.
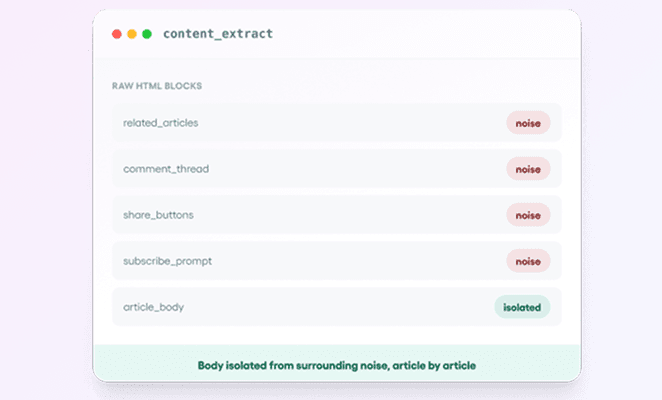
Related-article rails, comment threads, share buttons, and subscription prompts sit in the same HTML block as the article body. Zyte's extraction model is trained to isolate body text from surrounding noise, article by article, not with brittle per-site rules.
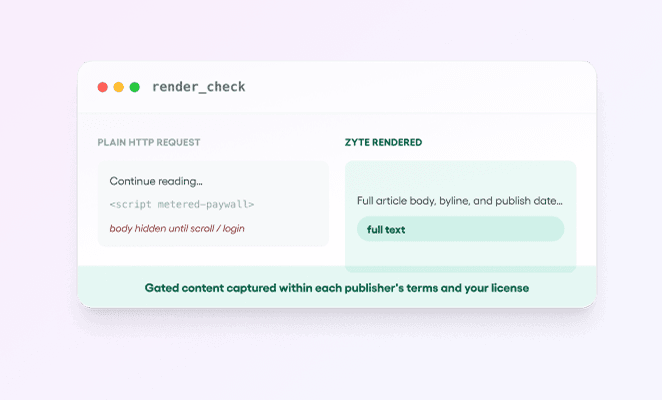
Many publishers render the full body only after a scroll event, a login check, or a metered-paywall script fires. Zyte renders pages the way a browser does, so gated and dynamically injected content is captured — within the bounds of each publisher's terms and your license.
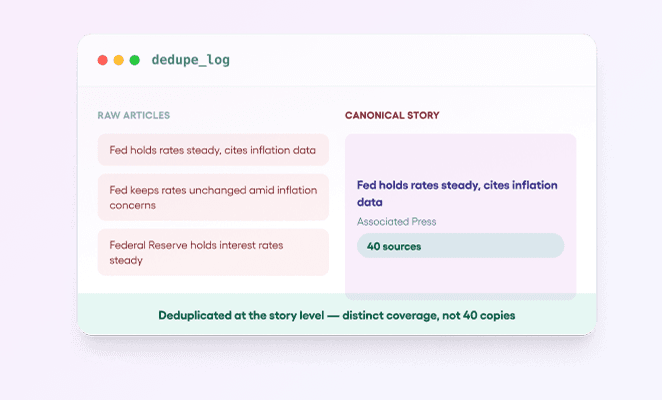
Wire stories and syndicated content appear near-identically across outlets within minutes of each other. Zyte deduplicates at the story level so your feed reflects distinct coverage, not forty copies of one AP piece.
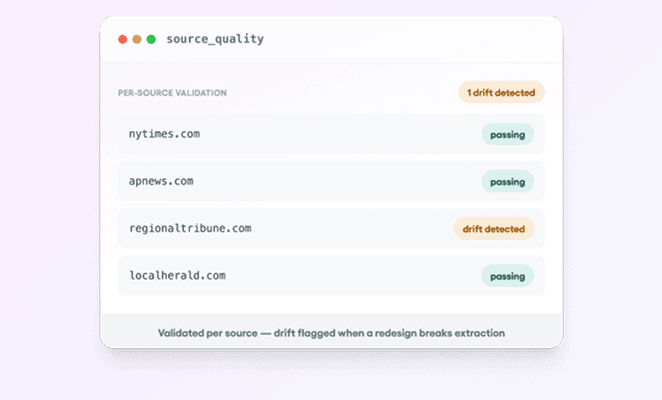
Thousands of source templates means thousands of ways to mis-extract a byline or a date. Zyte validates extraction quality per source, not just per field, and flags drift when a redesign breaks a previously reliable source.
Bad article data doesn't announce itself. It shows up later, in a sentiment score, a research note, or a trained model that was already wrong.

Mentions detected hours late are mentions acted on too late; a monitoring feed built on stale crawls misses the news cycle it exists to catch.

Uncounted syndication can make a single wire story look like broad organic coverage, skewing share-of-voice and sentiment metrics.

An NLP model trained on boilerplate-contaminated text degrades quietly; ad copy and related-link text leak into what the model treats as "the article."

Collecting and republishing content without regard to publisher terms, copyright, or personal-data rules carries real legal risk, including GDPR exposure up to €20M.
The request you send and the data that comes back. Pick the standard schema or a custom one mapped to your model, and read the response as a table or JSON.
POST https://api.zyte.com/v1/extract
{
  "url": "https://example-news.com/story/2026-market-outlook",
  "article": true
}Reliable Competitor Data Partner with Stellar Support
I have been working with Zyte's team for the last few months, and their team is fantastic. I appreciate their development speed and quality, and they run a very robust platform, producing very satisfactory results. I love the ease of the initial setup with Zyte, as they took care of all the development, and we only needed to communicate what data we needed and set up the necessary processes on our end.
Talk to a data specialist about coverage and schema, or request sample data for the outlets you care about.
New articles are typically detected and delivered within minutes to hours of publication, depending on source polling frequency. Real-time delivery is available where the use case needs it.
Coverage is scoped per source and per license — Zyte captures what a compliant, authorized method allows for each publisher, and this is agreed upfront rather than assumed.
Articles are deduplicated at the story level using content-similarity matching, so near-identical syndicated copies don't inflate your feed or your metrics.
Standard fields include headline, byline, publish/modified dates, full body text and HTML, images, language, paywall status, and extracted entities/categories. Custom schemas are available on request; delivery via JSON, API, or batch file.
Collection is scoped to each publisher's terms and applicable law, with sensitive personal data excluded by default unless specifically required and authorized.
Most feeds go from scoping call to first delivery within one to two weeks, depending on source count and schema complexity.
Yes — request sample data for specific outlets during your first call with our data specialists.
Yes. Talk to a data specialist to request sample data from the sources you care about before agreeing to a contract.