Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.

Build your own MCP server: LLMs meets web data with Zyte API
Learn how to build your own Model Context Protocol (MCP) server to connect LLMs with real-time web data using Zyte API, FastMCP, and the Docker MCP toolkit.

More data, more trouble: How a perfect corpus corrupted my AI dream
A failed AI experiment reveals why adding more data doesn’t always improve LLM outputs. Learn when web scraping, RAG, and curated datasets actually make AI better.
Stop using Python requests for web scraping: Use these modern modules instead
While the 'Requests' library remains the default choice for many Python developers due to its reliability and extensive documentation, the Python HTTP landscape has evolved considerably. Modern alternatives now offer significant advantages, including built-in asynchronous support, HTTP/2 compatibility, enhanced performance, and up-to-date TLS handling.

Claude skills, MCP or Web Scraping Copilot: Which should you choose?
Compare Claude skills, MCP servers, and Web Scraping Copilot to understand when to use each for AI-powered web scraping, data extraction, and production pipelines with Zyte API.

Supercharging web scraping with Claude skills
Learn how Claude skills can automate HTML fetching, AI parsing, selector generation, and structured data extraction to build faster, smarter web scraping workflows.
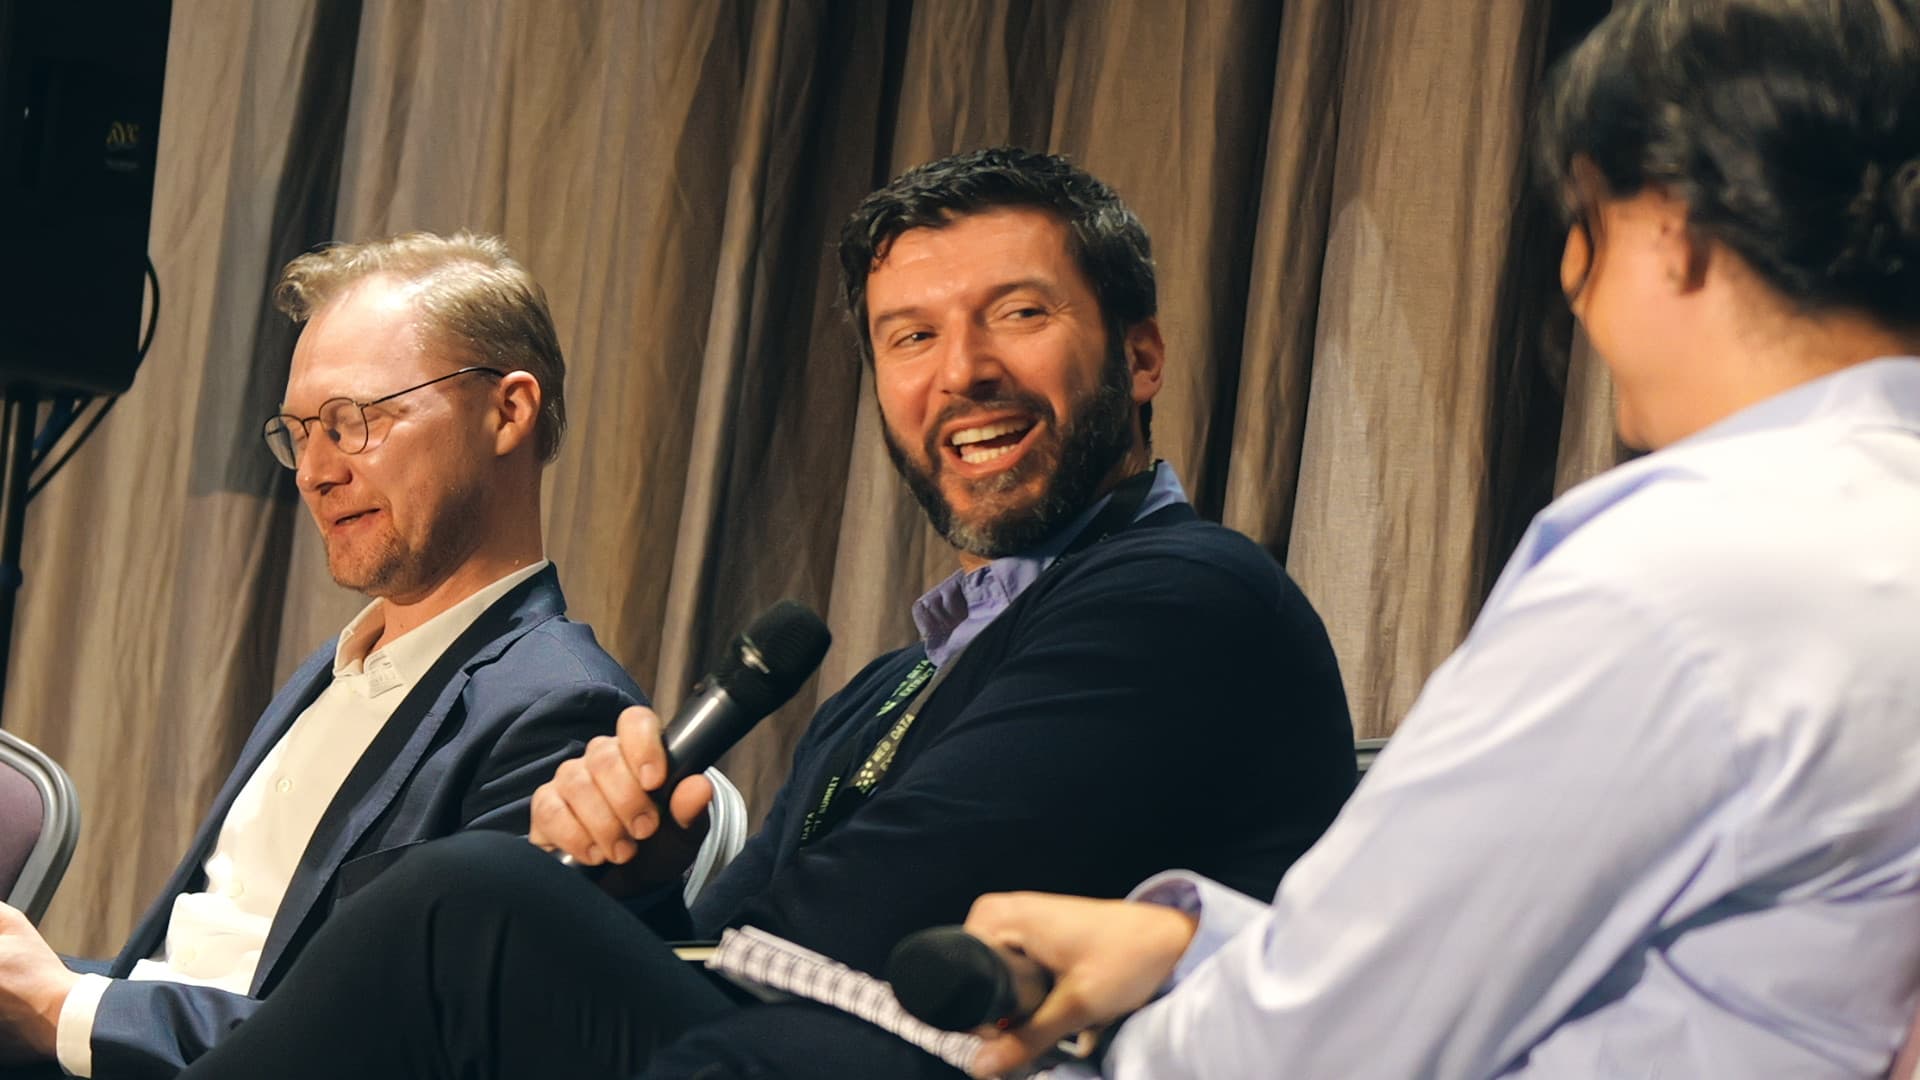
Is your AI breaking the law? Legal experts’ advice for web scrapers
Legal experts discuss how AI, web scraping, copyright law, and the EU AI Act intersect—covering fair use, data provenance, and compliance risks for businesses.
Screenshot webpages with this Claude Skill and Zyte API
0% Hallucination? RAG + Web Scraping (Step-by-Step)

Brewing a bot: RAG and web data fuel the perfect coffee recommendation
Learn how to build a real-time AI chatbot using RAG, web scraping, Zyte API, LangChain, and OpenAI. Scrape JavaScript-heavy websites, store data in a vector database, and generate accurate answers from fresh web data.

Beyond text: Unlocking value on the multimedia web
The web is about more than the written word. Why companies are racing to harness the power of video, audio and pictures.
A data scientist's guide to stress-free product scraping
As a data scientist, your job is to find patterns, build models, and generate insights. To do that, you first need to reliably acquire web data. Competitor pricing, product specifications, consumer reviews - you name it, data scientists need it.
Why Python Requests gets "403 Forbidden"
If you’ve had your HTTP request blocked regardless of using correct headers, cookies, and good IPs, there’s a chance you are running into one of the simplest forms of blocking, and one of the most confusing for beginners.