Scraping strategy
Articles from the Zyte blog about Scraping strategy.
The world's hardest sites protect their prices
Only a sliver of the web demands the heaviest machinery to read. It is dominated by shops, property listings and booking engines, where every published price is somebody's market intelligence.
The easiest sites to scrape are the ones that want to be found
Want an easy scrape? Skip the shops and try the military. Defence, government and science sites rank among the most open on the web.
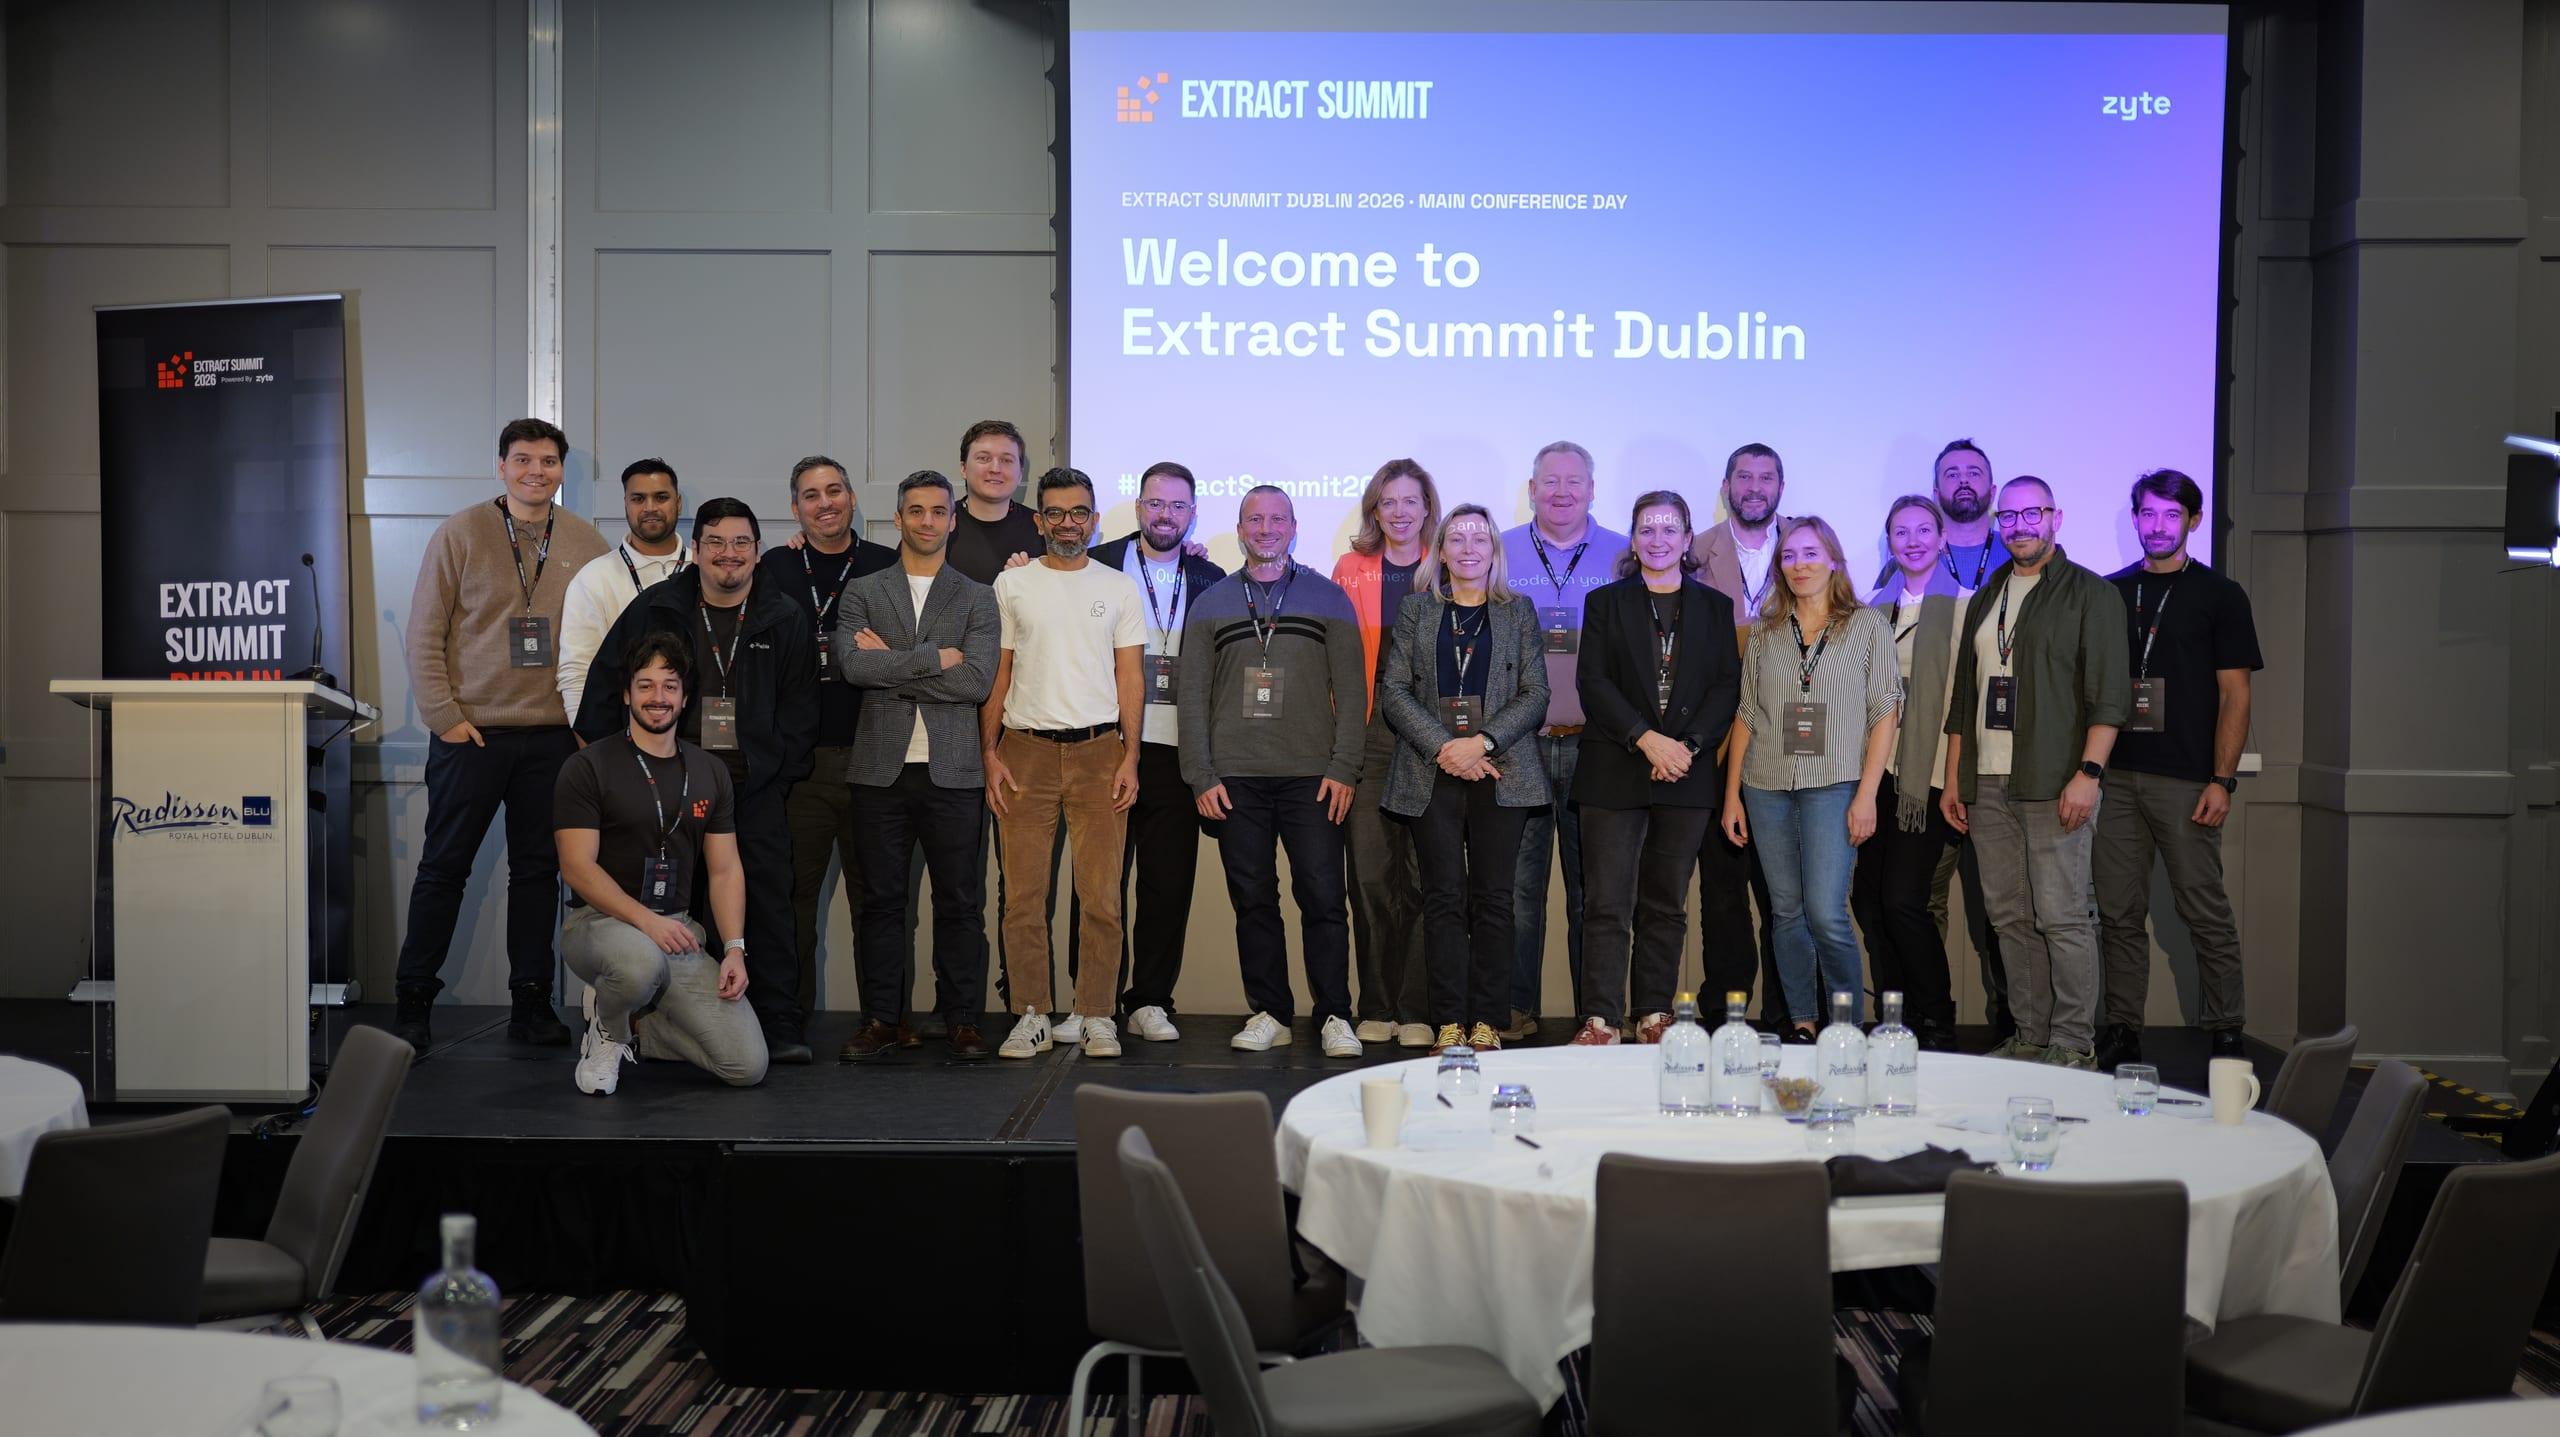
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
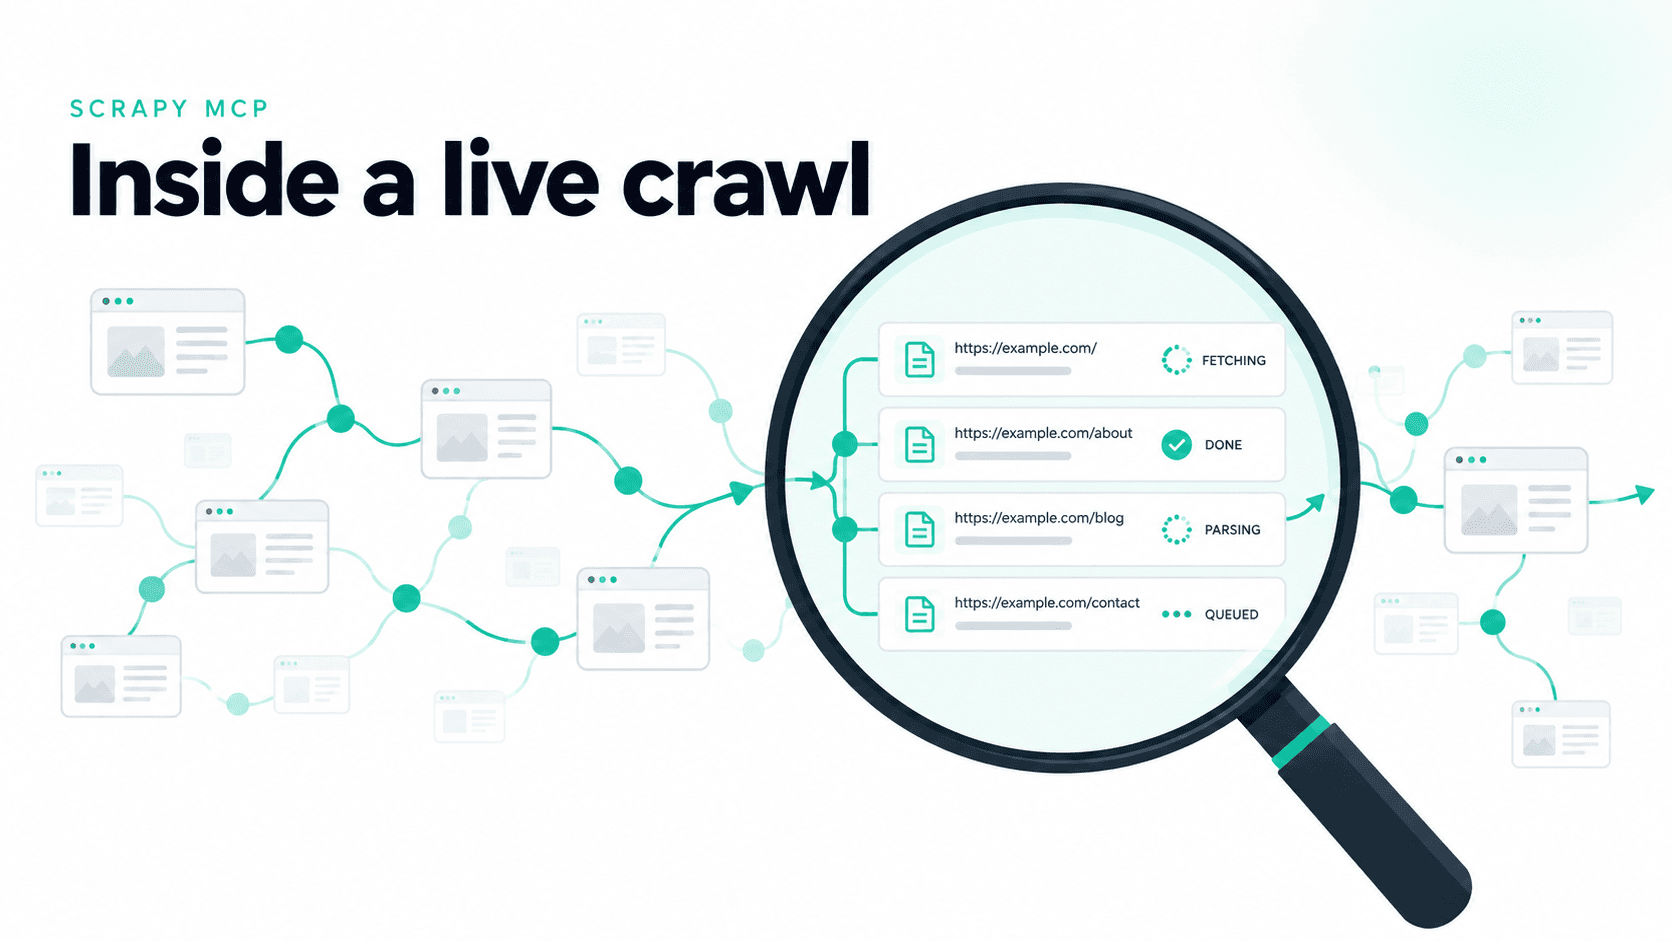
Inside Scrapy's RemoteControl extension
Scrapy 2.19's RemoteControl extension runs a small authenticated HTTP server inside every crawl. How it starts, how it's secured, what the code you send can reach, and what you can do with it on a live crawl, plus the traps and what changes under scrapy-zyte-api.
The web is being priced, not blocked
Zyte's State of Web Access research finds new barriers making web scraping more difficult. We interview the researcher who says that doesn't mean the opportunity is over.
Rendering JavaScript pages without giving up Scrapy
How to scrape JavaScript pages with Scrapy, checking the response and API first, then adding scrapy-playwright only for the requests that need a browser.
A guide to Scrapy item types
Scrapy supports several item types, from plain dicts to Item objects, dataclasses and attrs classes. What each one gives you and which to use in your spiders.
Podcast Ep08 - Scrapy, Python and mushroom soup
Episode 8 of the Zyte Scrapy podcast, on why Scrapy's core leaves browsers, data shaping and anti-bot handling out, and how you add them when you need them.
Treat your AI skills like software, starting with evals
Most AI skills are never tested — and it shows. Here's how Zyte evaluates scraping skills like real software, catching failures demos miss.
The great wall of data: The complexities of web scraping in the Asian market
While the technological arms race of web data access is universal, the battleground in Asia has its own unique rules of engagement.
Brand visibility in the digital era: How web data help brands see the full picture
Discover how web data helps brands improve visibility, track competitors, monitor availability, and analyze reviews to win on the digital shelf.
How online retailers use web data to compete on price, promotion, and availability
Discover how retailers leverage web data to optimize pricing, track competitor stock, detect trends, and improve sales performance.
More articles on Scraping strategy
- How web data turns e-commerce listings into retail intelligence
- The seven habits of highly effective data teams
- Five key takeaways from Extract Summit 2025
- The data quality playbook: how to measure and score the quality of your web data
- The new economics of web data: Smaller scraping just got cheaper
- How to Plan Your Web Scraping Project Like a Product Manager
- How Zyte’s extraction experts guarantee data quality
- Cheaper web data is changing strategy—are you keeping up?
- Build or Buy? Solving the web scraping dilemma
- Why are Sessions Crucial in Web Data Extraction?
- The trade-offs in crawling infrastructure in the modern anti-bot landscape
- Transitioning to Remote Working as a Company: Lessons Learned
- Handling COVID-19 as a Fully Remote Company: Zyte's Approach
- Best Recruitment Tips: How To Scout Top Talent
- Embracing The Future Of Work: How To Communicate Remotely
- A Not-So-Short Story on Getting Decent Internet Access
- Chats with Rinar Solutions: Insights into Remote Working
- Tips for Creating a Cohesive Company Culture Remotely
- Aduana: Link Analysis to Crawl the Web at Scale
- StartupChats: Embracing Remote Working for Success
- Traveling Tips for Remote Workers: Balancing Work and Adventure
- A Career in Remote Working: Embracing Flexibility and Freedom
- Zyte: A Remote Working Success Story