Scrapy
Articles from the Zyte blog in Scrapy.
What is a self-healing web scraper?
A self-healing web scraper detects when a site change breaks extraction, repairs the code within limits you set, proves the fix with tests, and escalates when it can't. What it fixes, what it doesn't, how the loop works and what a repair costs.
Self-healing scrapers: four things to put in place before an AI agent fixes your spiders
What decides whether a self-healing scraper's repair is any good: detection during the crawl, a specific failure report, extraction code the agent can target, and tests that can fail.
How to build your first Scrapy extension
My Scrapy project now plays a triumphant fanfare when a crawl finishes clean and a sad trombone when it doesn't, which is also how I finally learned what Scrapy's extension points are actually for.
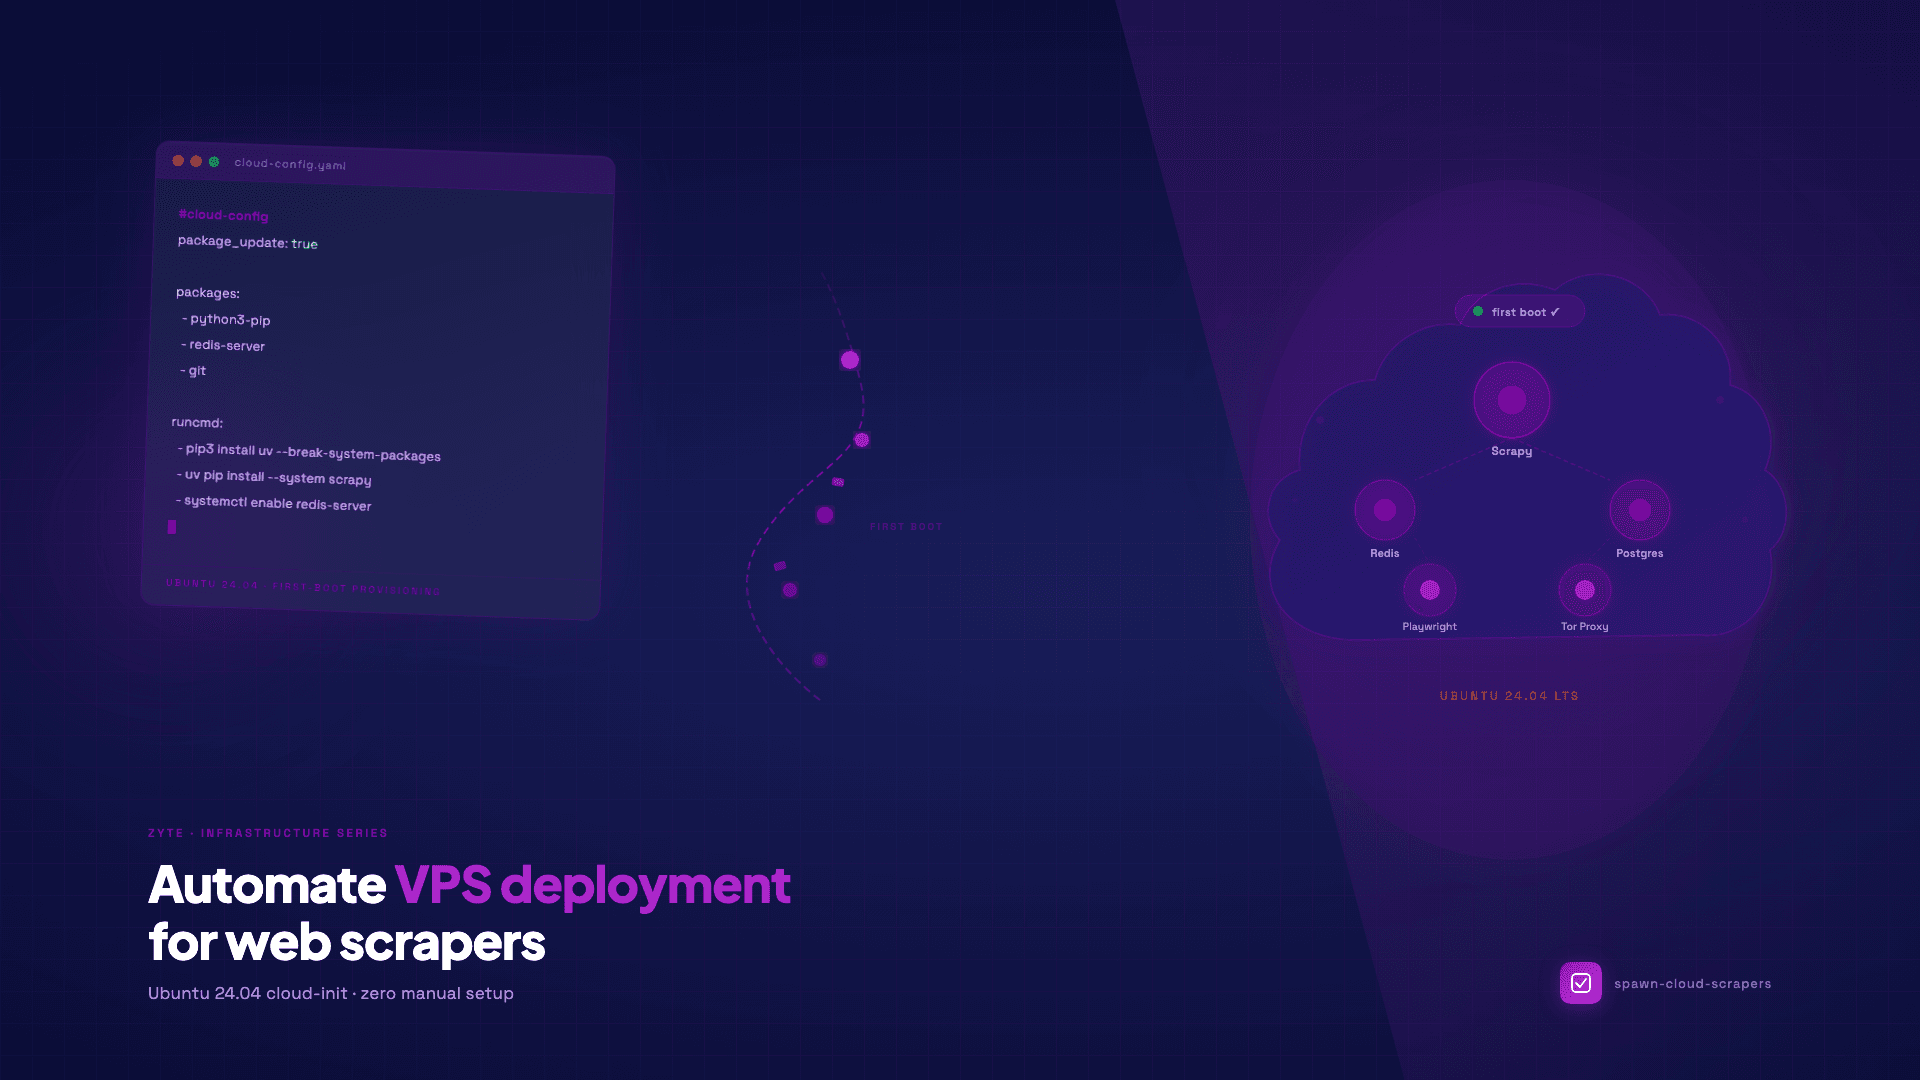
Automate deployment of your web scraper on VPS with Ubuntu 24.04 cloud-init
Your VPS is ready, but now you need to work through the same sequence you have run a dozen times before: apt update, apt install python3-pip, pip install scrapy, playwright install chromium, the Chromium dependency list that never installs cleanly on the first try, Redis, possibly Postgres, whatever else this particular project needs.
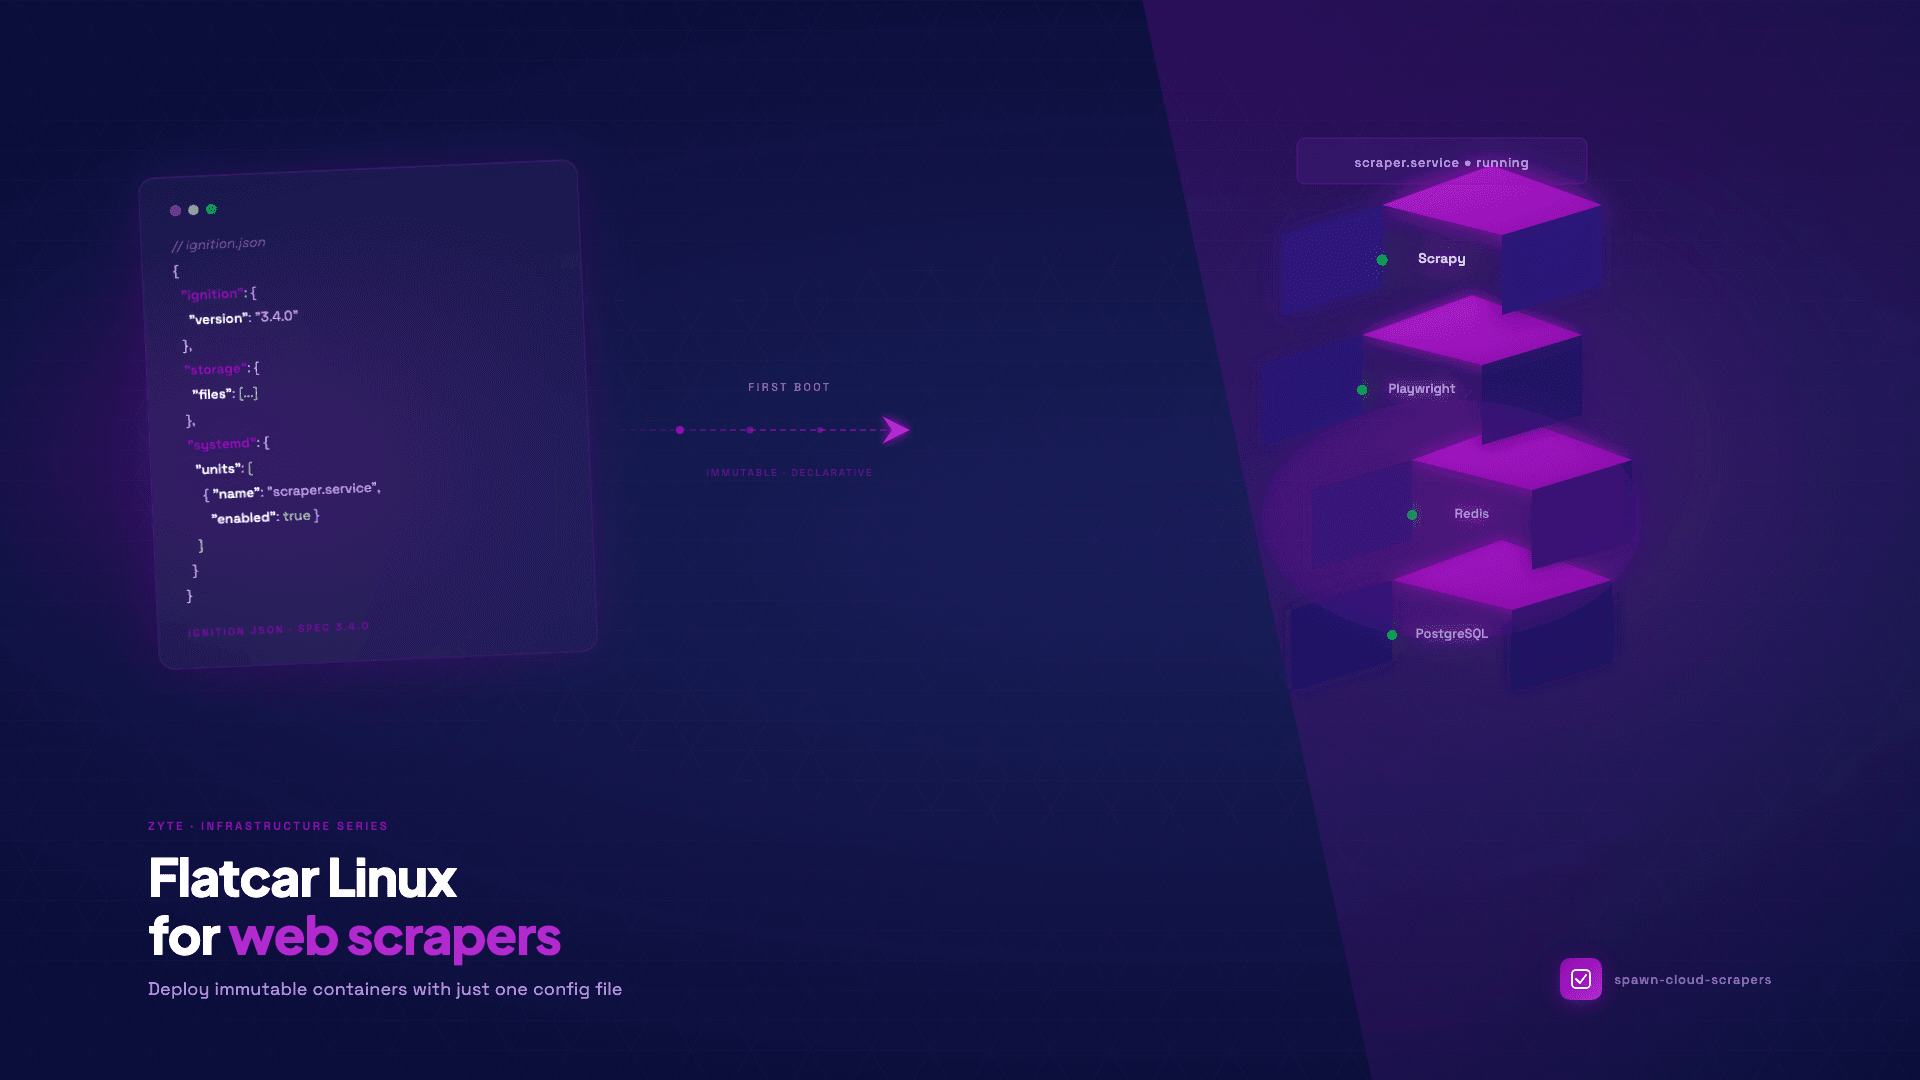
Flatcar Linux for web scrapers: deploy immutable containers with just one config file
The next time you spin up a VPS to give it a persistent home, you spend the better part of an afternoon rebuilding from memory. Here's a tool to help using Flatcar Linux

The Scrapy whisperer: Adrian Chaves on Web Scraping Copilot
An interview with Scrapy maintainer Adrian Chaves on Zyte’s Web Scraping Copilot, AI-generated parsing code, and building reliable scraping workflows.

Introducing Web Scraping Copilot 1.0: AI-accelerated web scraping inside VS Code
Discover Web Scraping Copilot 1.0, Zyte’s VS Code extension that uses AI to generate, test, and deploy production-ready Scrapy spiders faster while maintaining full developer control.
Scraping Swiss Army Knife: My personal fix for web setup fatigue using Docker, Scrapy and Zyte
Tired of repeating web scraping setup? Learn how a multi-arch Docker container with Scrapy, Zyte, Requests, and Pandas speeds up exploration and debugging.

Scrapy in 2026: New release brings modern async crawling standards
Scrapy 2.14.0 modernizes the framework with native async/await, smarter scheduling, and cleaner spider configuration. Here’s what the new release means for production crawlers in 2026.
The future of Scrapy: Smarter, faster and ready for AI-powered scraping
What does the future hold for the tool some describe as “the gift that revolutionised web scraping”?

Ten years since Scrapy 1.0: The stats and stories behind your favorite framework
See what 10 years of Scrapy 1.0 has built — in milestones and metrics.
The rise of Scrapy: How an open-source scraping framework conquered the web
The story of Scrapy reflects the broader evolution of the web itself and the ongoing quest to harness its ever-expanding ocean of information.