Data quality
Articles from the Zyte blog about Data quality.
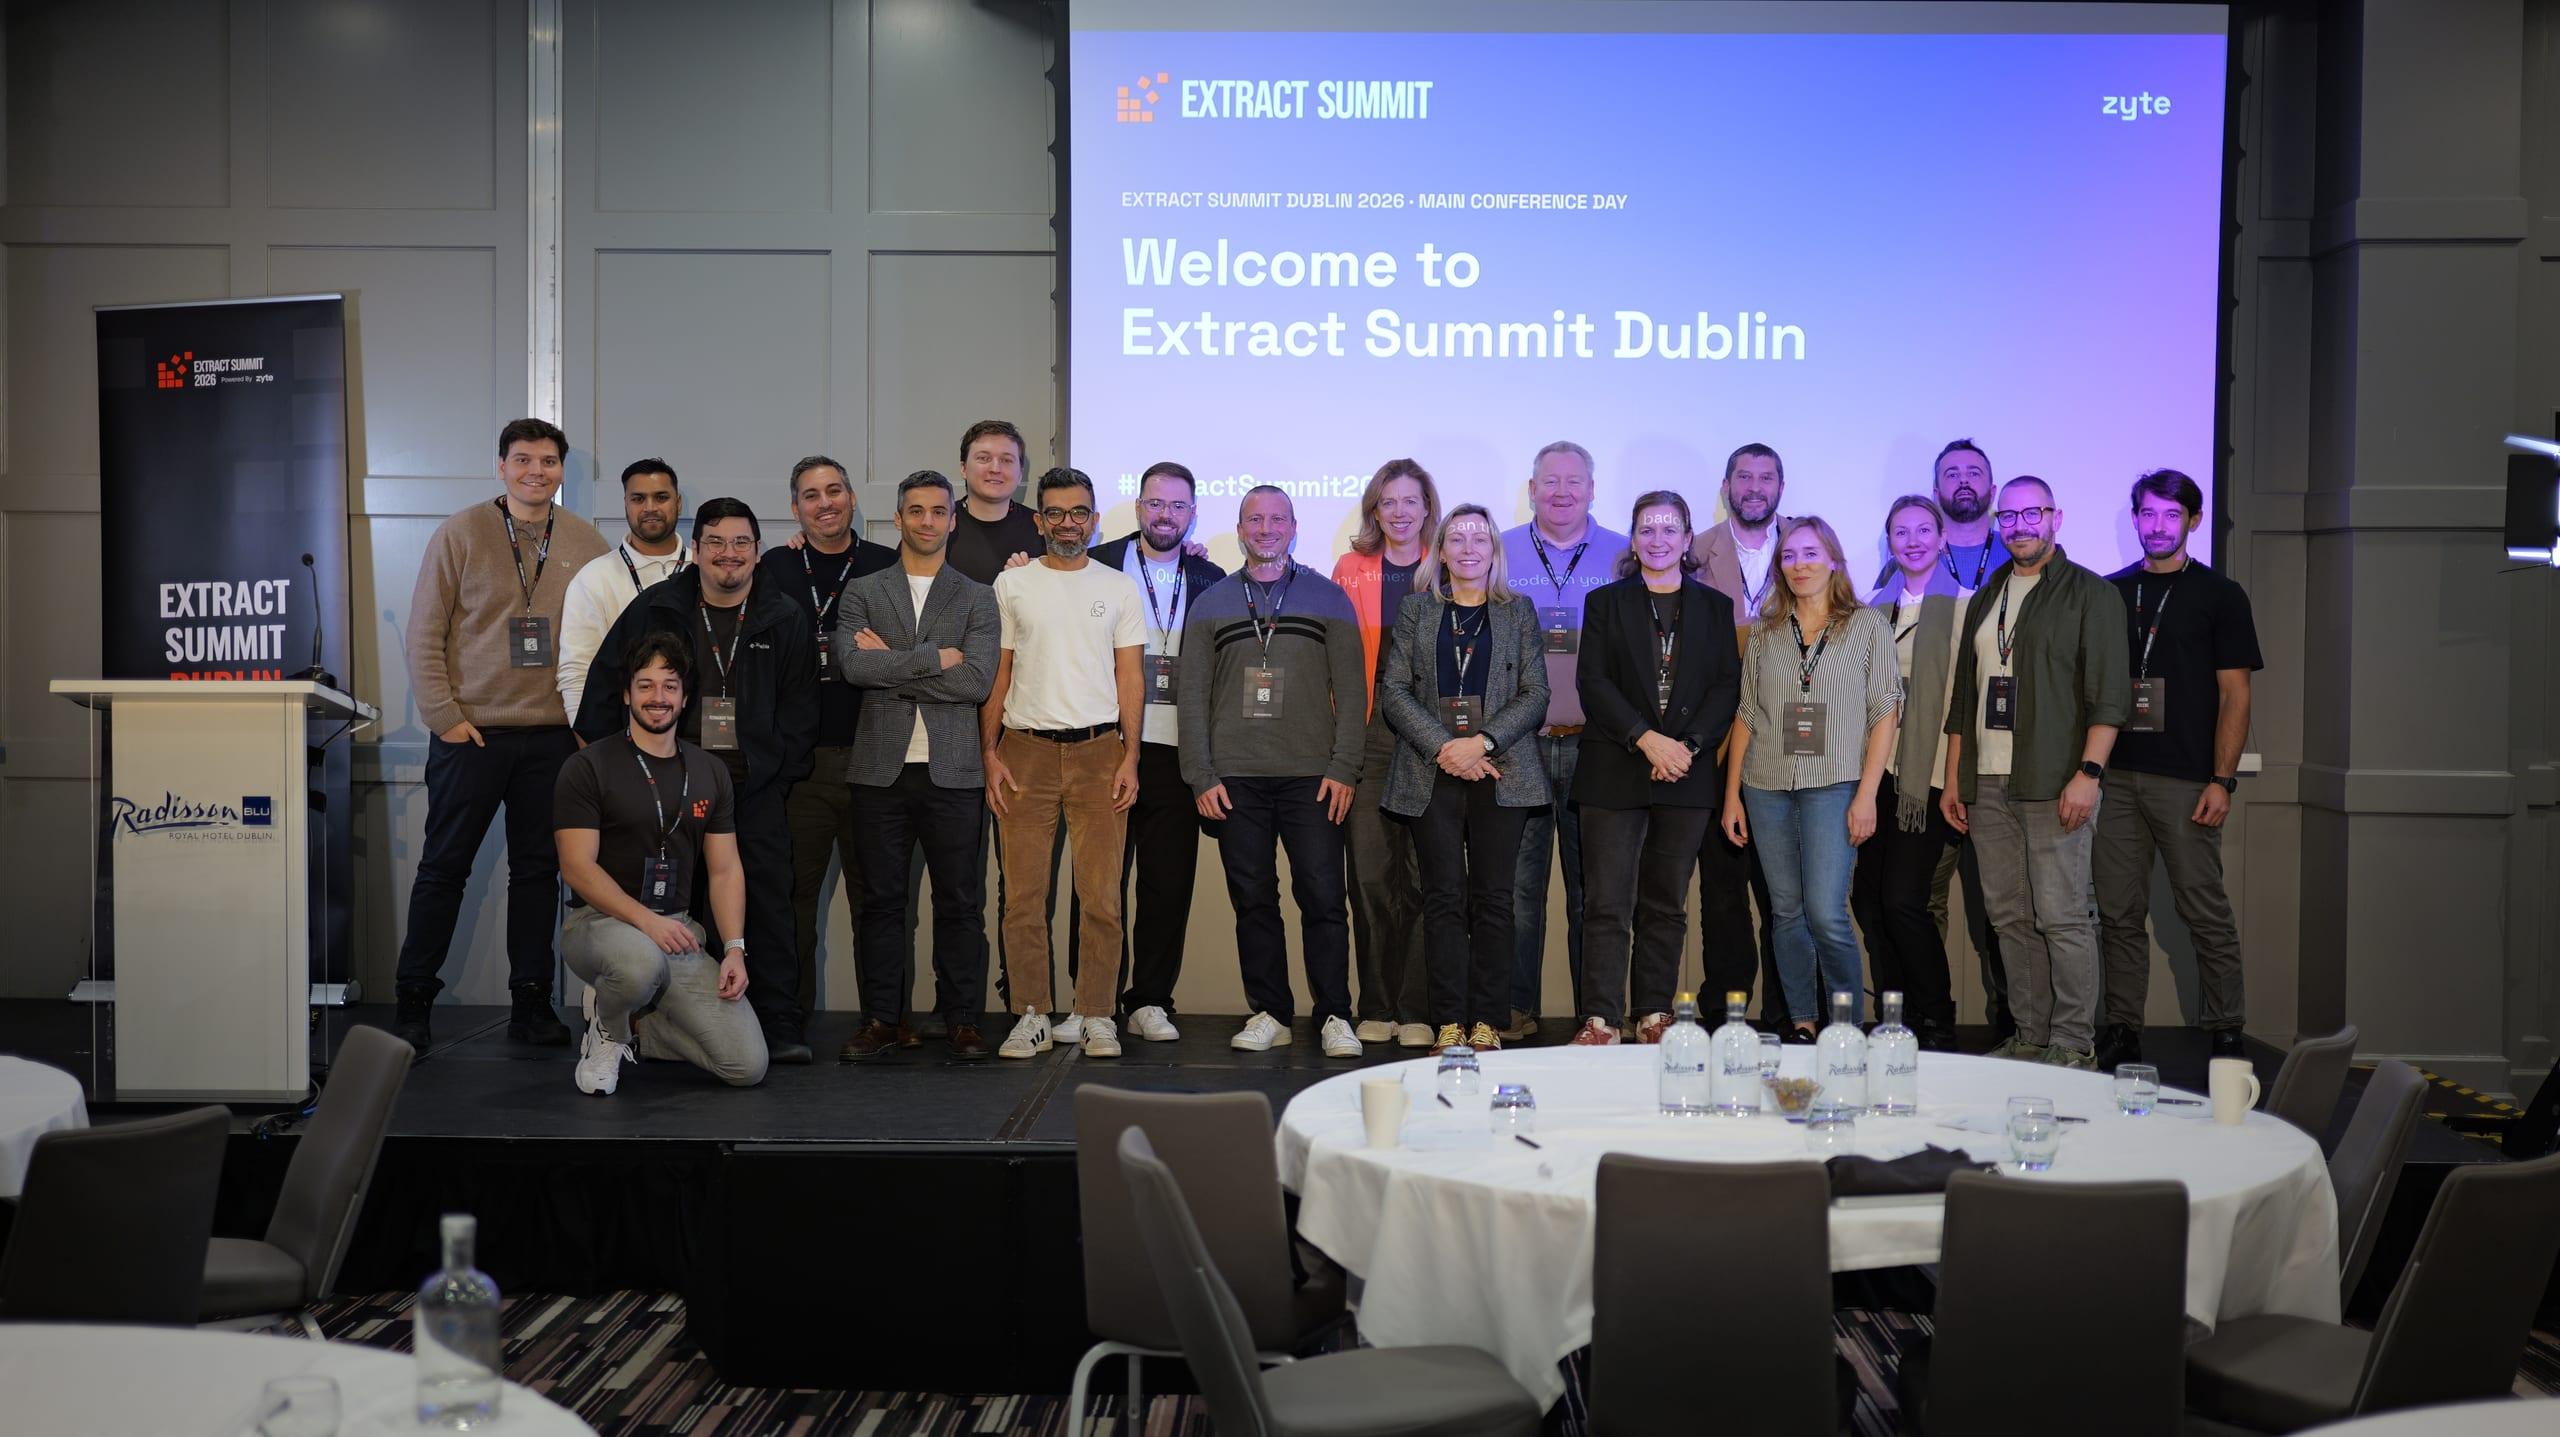
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
What is a self-healing web scraper?
A self-healing web scraper detects when a site change breaks extraction, repairs the code within limits you set, proves the fix with tests, and escalates when it can't. What it fixes, what it doesn't, how the loop works and what a repair costs.
Self-healing scrapers: four things to put in place before an AI agent fixes your spiders
What decides whether a self-healing scraper's repair is any good: detection during the crawl, a specific failure report, extraction code the agent can target, and tests that can fail.
Stopping a crawl when the data stops looking real with Jev
A Scrapy pipeline that asks a fast, calibrated AI model whether each scraped field still looks real, and stops the crawl when too many don't. What it caught, what it misses, and whether building it was worth it.

The harness matters more than the model - Podcast EP07
"The model is the engine — but the harness is everything else." In Episode 7, we dig into why the infrastructure layer around your AI model matters more than the model itself, rank the best models available right now, and ask whether the open-weighted revolution is about to make frontier subscriptions obsolete.
AI won’t fix your data quality (until you answer these three questions)
In our interview, a QA expert warns - before you delegate web scraping quality assurance to AI, make sure you can describe what ‘good’ looks like for yourself.
Teaching AI to scrape like a pro: how we measure LLMs’ data quality
AI-enabled code editors can now conjure scraping code on command. But is it any good? Here’s how Zyte re-engineered LLMs with Web Scraping Copilot to drive best-in-class output.
Claude Sonnet 4.6 is the new best model for writing scrapers
Claude Sonnet 4.6 is now the top model in Zyte’s Web Scraping Copilot benchmark, narrowly beating Gemini 3 Pro on extraction quality, with a small increase in code complexity.

Gemini 3.0 Pro is the new best model for writing scrapers
Gemini 3.0 Pro outperforms GPT-5, Claude, and other leading LLMs in Zyte’s Web Scraping Copilot benchmarks, delivering the highest code accuracy and lowest complexity. See full results, pros, cons, and recommendations for production workflows.
The data quality playbook: how to measure and score the quality of your web data
How to define, check and score the quality of the web data you collect: five dimensions, a schema, monitors, and a weighted score you can compute.
How Zyte’s extraction experts guarantee data quality
Ensuring web data quality at scale means moving beyond fragile scripts and spot checks to robust validation that keeps business decisions accurate and reliable.

How Session Management Minimizes Bans and Enhances Data Quality in Web Scraping
Learn how managing user sessions in web scraping can help overcome website bans, handle IP rate limits, streamline cookie management, and avoid detection.