Scraping practice
Articles from the Zyte blog about Scraping practice.
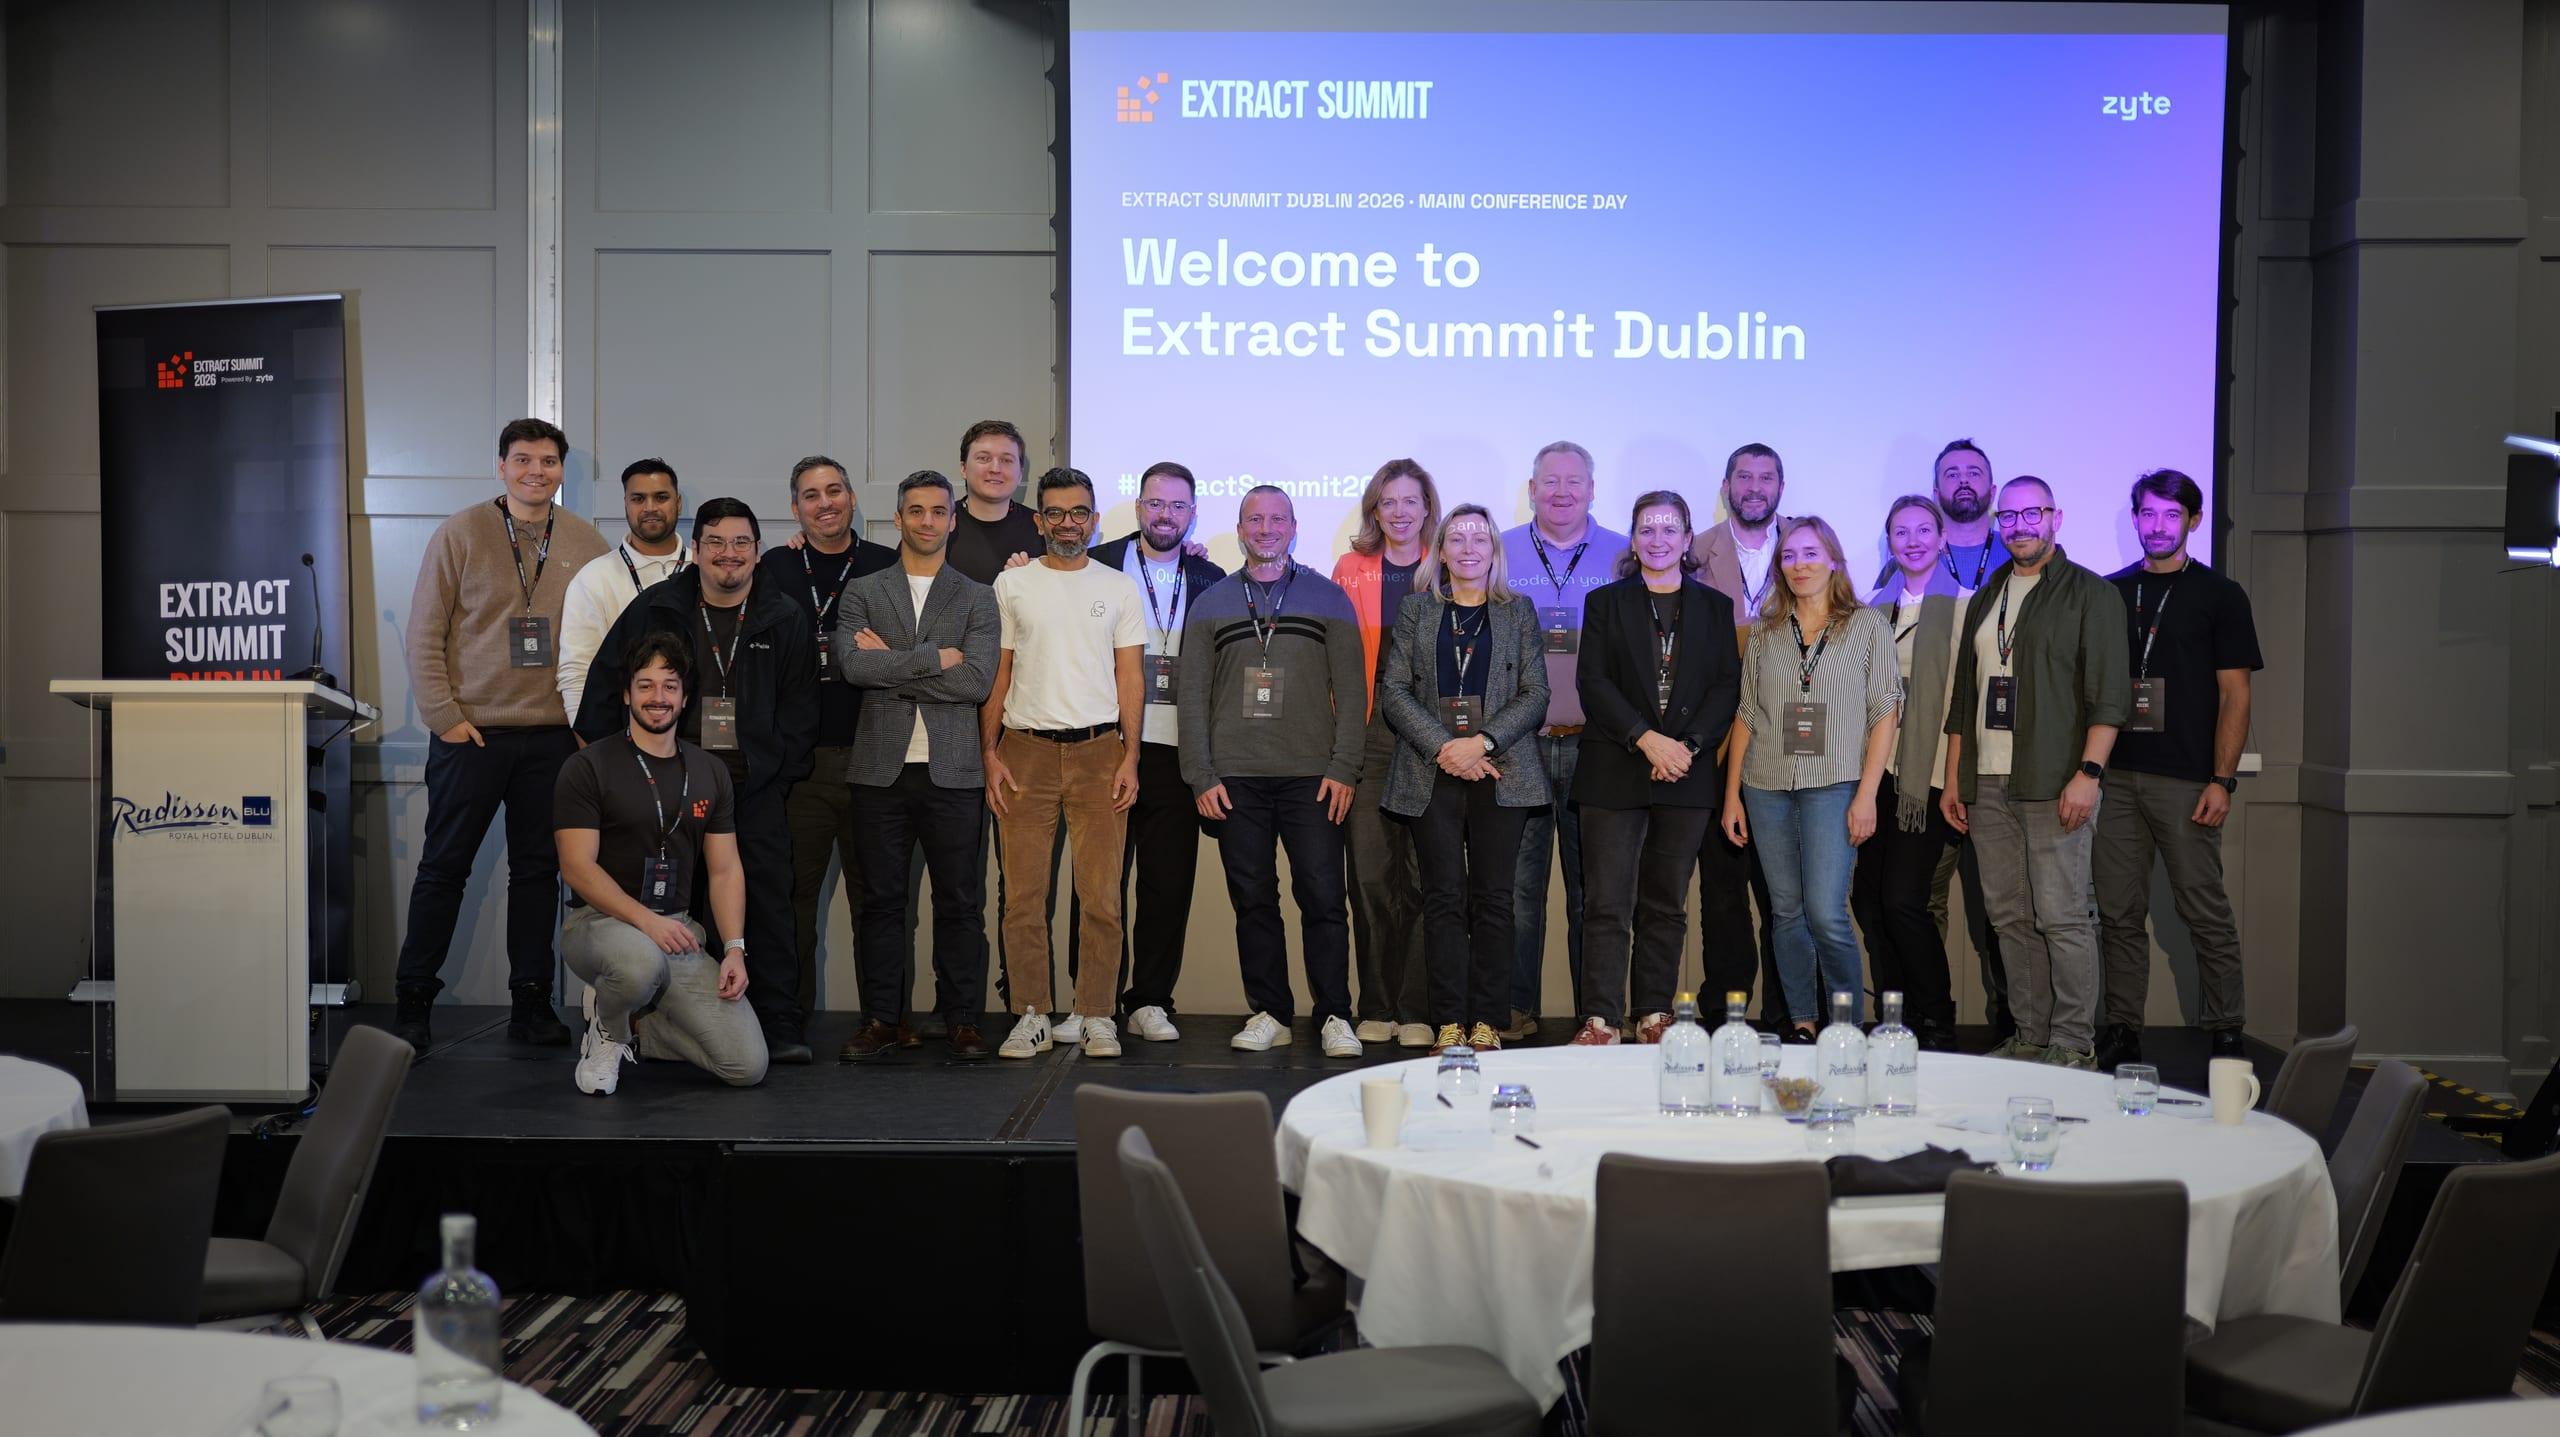
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
What is a self-healing web scraper?
A self-healing web scraper detects when a site change breaks extraction, repairs the code within limits you set, proves the fix with tests, and escalates when it can't. What it fixes, what it doesn't, how the loop works and what a repair costs.
Self-healing scrapers: four things to put in place before an AI agent fixes your spiders
What decides whether a self-healing scraper's repair is any good: detection during the crawl, a specific failure report, extraction code the agent can target, and tests that can fail.
12 things I use Zyte MCP for, ranked, with prompts and rules you can copy
What can you use Zyte MCP for? 12 uses, 11 tested, ranked, each with a copy-paste prompt, a CLAUDE.md rule, and a skill idea.
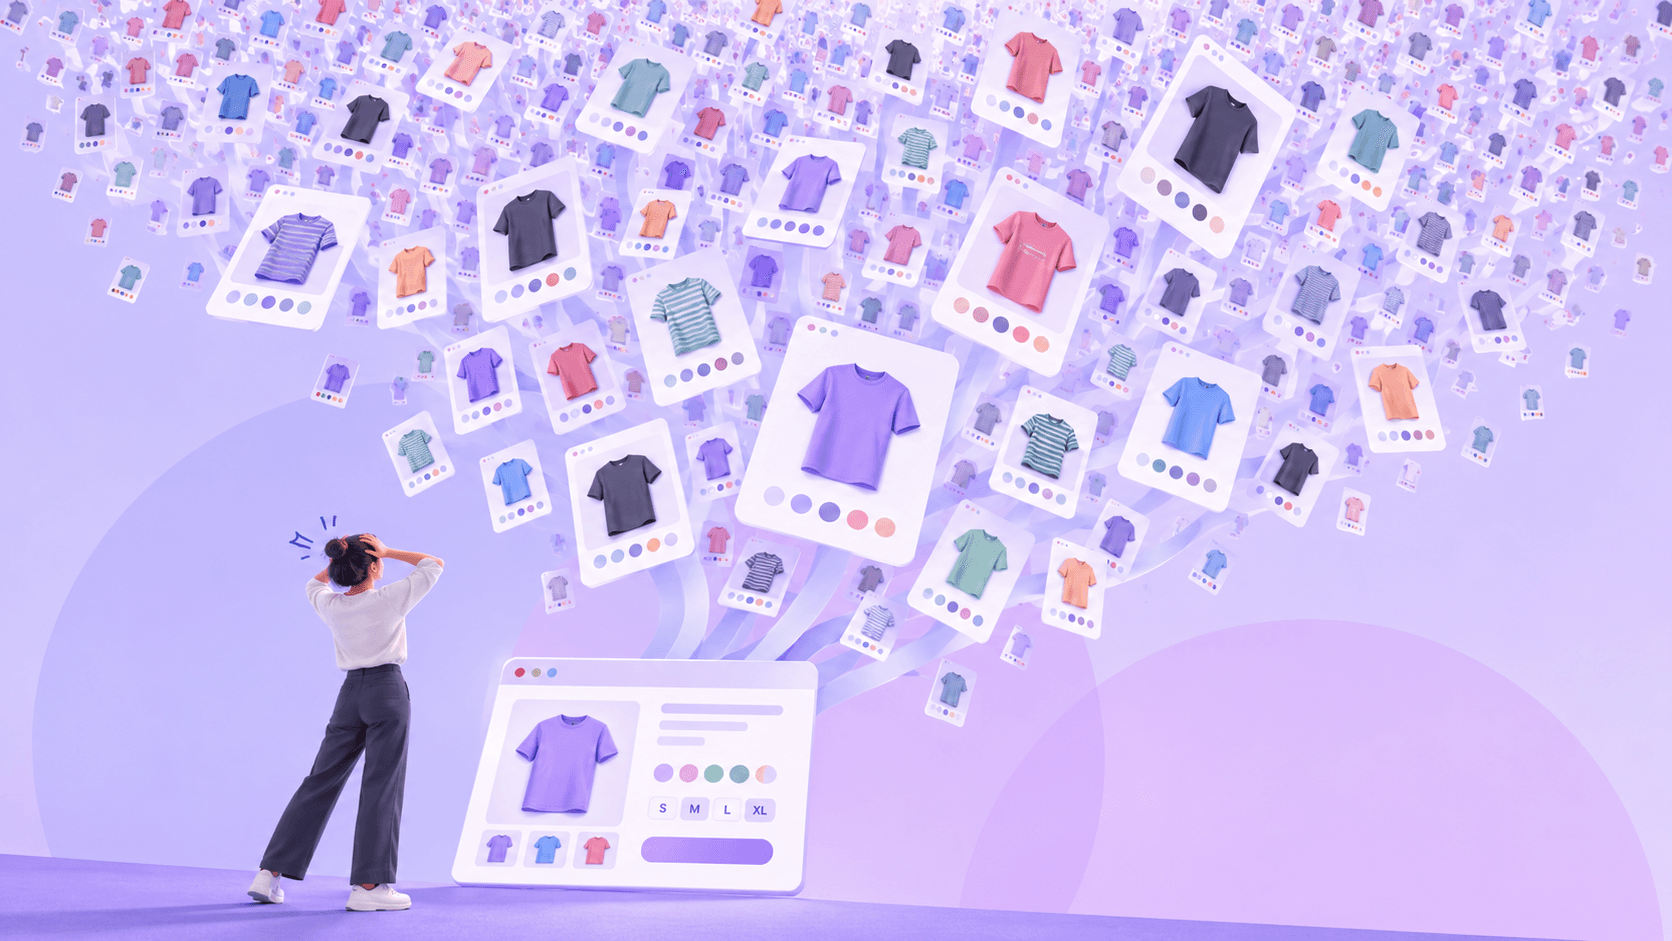
The trouble with variants: Solving the web's infinite ecommerce explosion
Product variants can turn a straightforward ecommerce scraping project into millions of combinations. Learn how to classify, scope and control them.
How I use Zyte MCP to plan web scrapers
Zyte MCP lets my AI agent investigate a site before I write the scraper, so I can decide where the data should come from, compare an API with the rendered page for missing fields, and end up with a crawl plan I can act on.

JSON Parsing with Python [Practical Guide]
Parse JSON in Python with json.loads and json.load, read what each error means, and get JSON out of APIs and web pages with JMESPath and ChompJS.
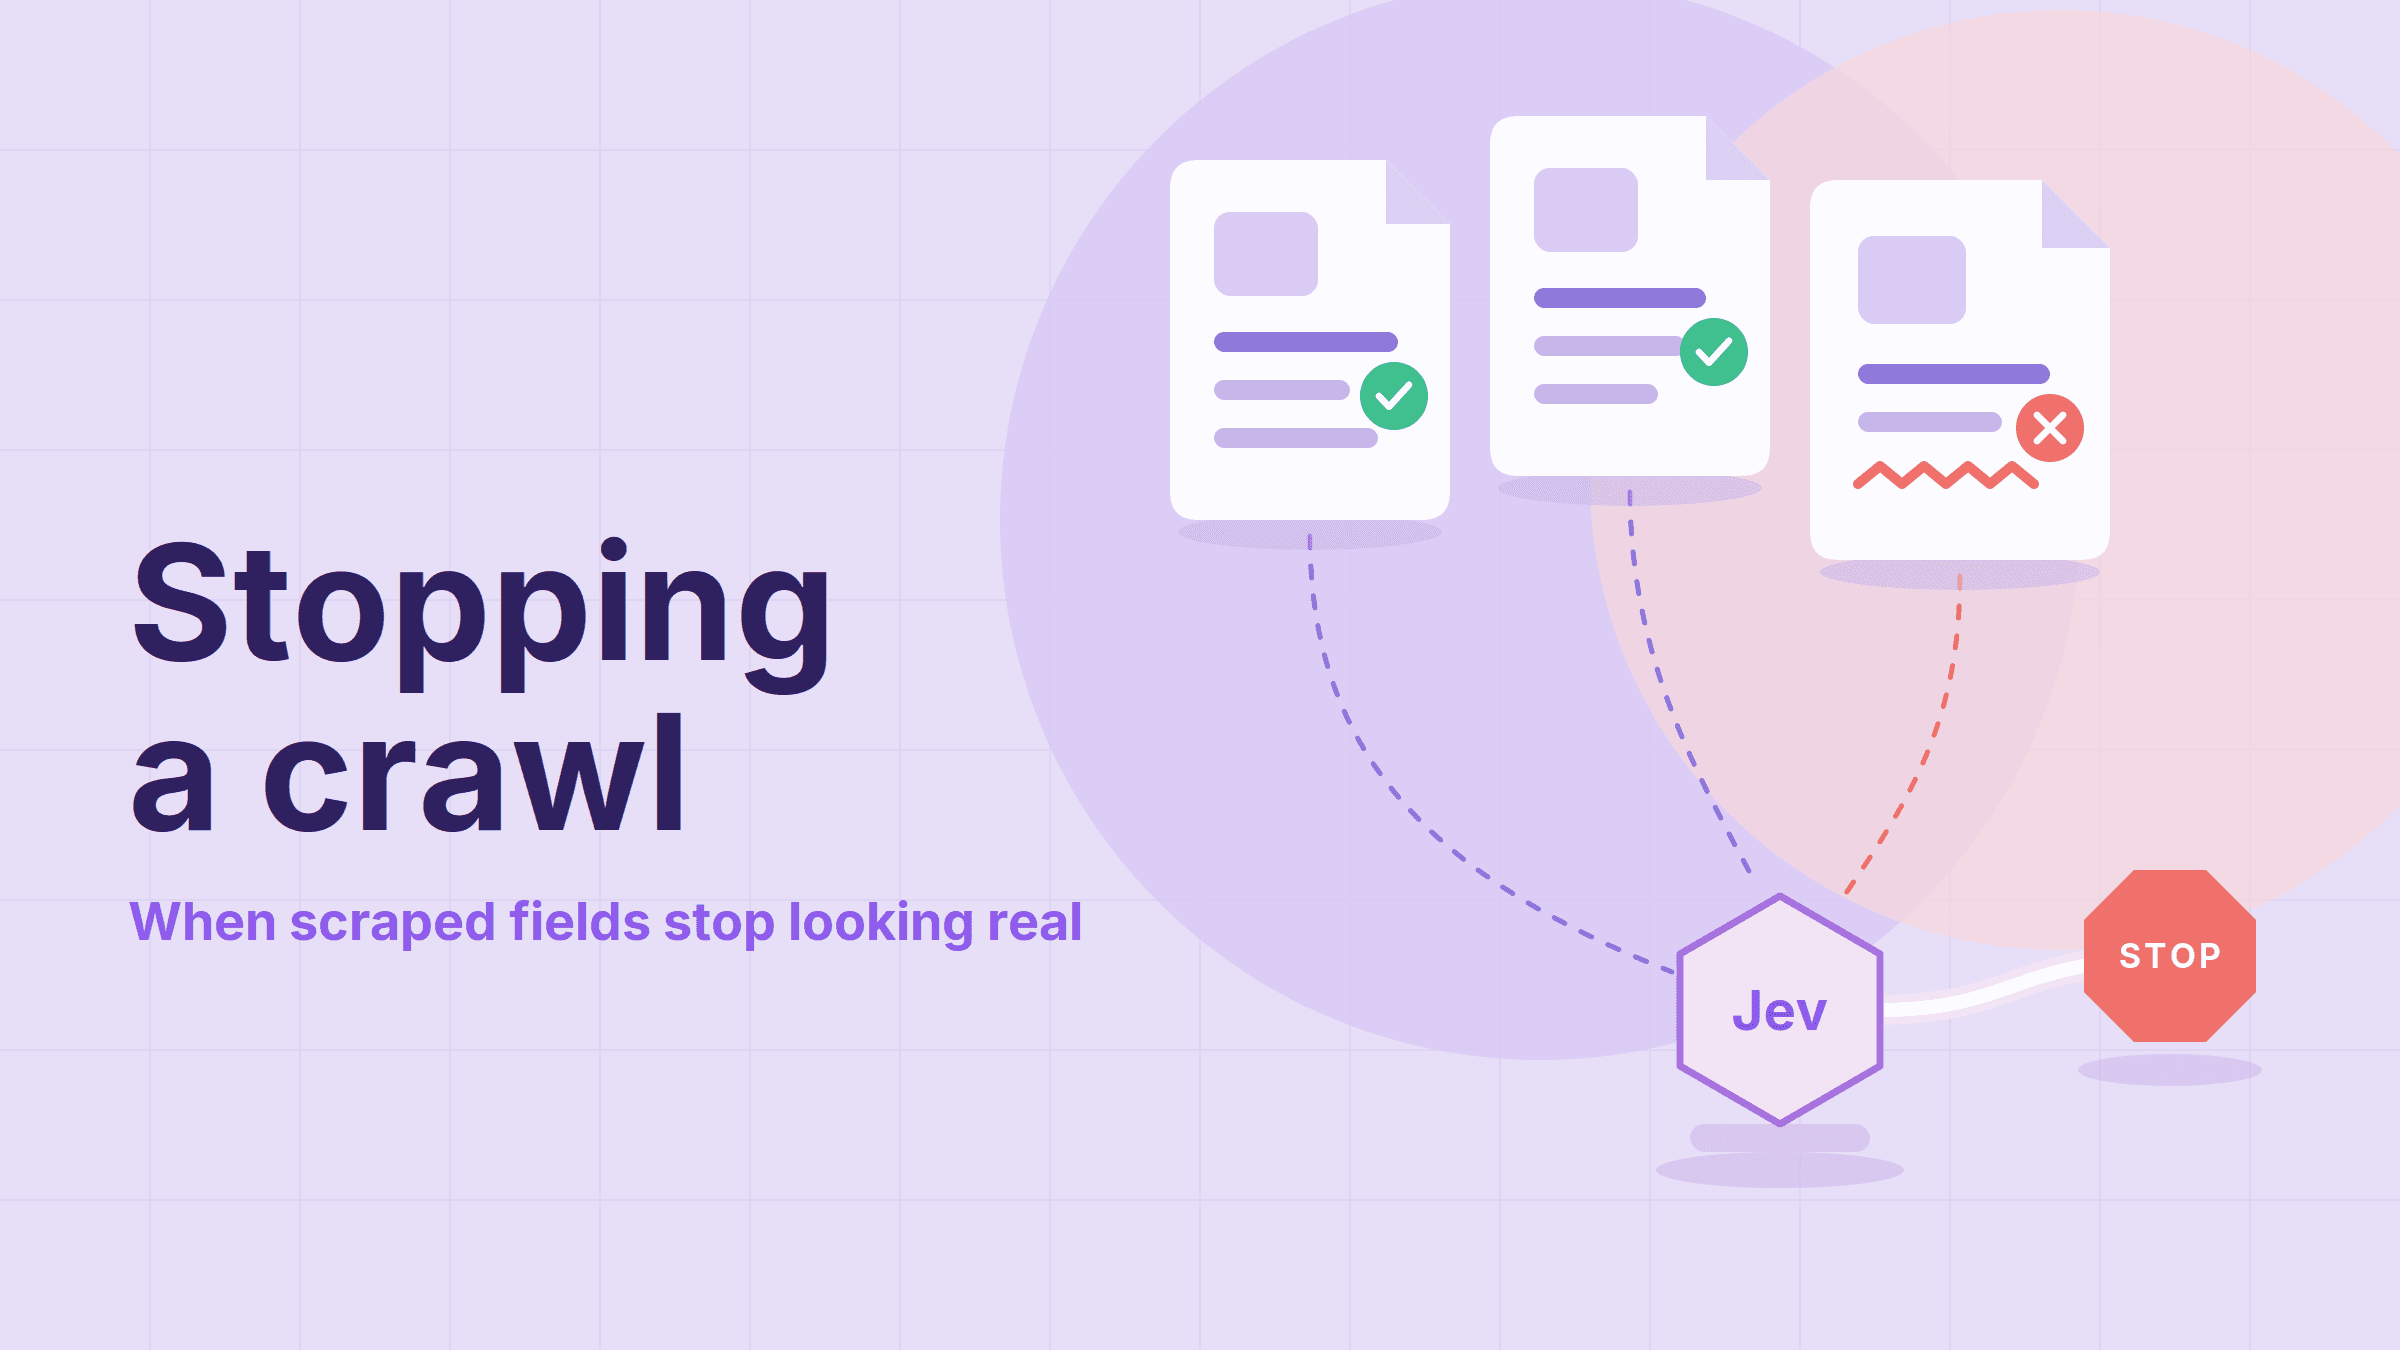
Stopping a crawl when the data stops looking real with Jev
A Scrapy pipeline that asks a fast, calibrated AI model whether each scraped field still looks real, and stops the crawl when too many don't. What it caught, what it misses, and whether building it was worth it.
Podcast Ep08 - Scrapy, Python and mushroom soup
Episode 8 of the Zyte Scrapy podcast, on why Scrapy's core leaves browsers, data shaping and anti-bot handling out, and how you add them when you need them.
The missing middle ground in scrapy-playwright just got filled
You can now choose which Python browser library you want to use with scrapy-playwright. I go through why this is a huge deal for the right scraping demographic.
AI generated these Scrapy projects - why I won't ship them
What happens if you let AI create a Scrapy project from just a simple prompt? Here's what I got and what I had to fix.
AI won’t fix your data quality (until you answer these three questions)
In our interview, a QA expert warns - before you delegate web scraping quality assurance to AI, make sure you can describe what ‘good’ looks like for yourself.
More articles on Scraping practice
- The recipe for a request: Scaling data extraction through investigation
- Teaching AI to scrape like a pro: how we measure LLMs’ data quality
- Hybrid scraping: The architecture for the modern web
- How I trade gold using e-ink, live data and an old Raspberry Pi
- Scrapy in 2026: New release brings modern async crawling standards
- How to build a daily industry news digest
- Browser bother: Three painkillers for headless scraping headaches
- Overcoming web scraping challenges of Puppeteer and Playwright
- Selenium, Puppeteer, Playwright: Which tool is right for web scraping at scale?
- Choosing Between Puppeteer vs. Selenium for Web Scraping
- Web Scraping in Python: Ultimate Guide
- Python lxml tutorial | Guide to Web Scraping with python lxml library
- Extract JSONs Like A Pro With Chompjs And JMESPath
- XPath Tips From The Web Scraping Trenches