A self-healing web scraper is one that notices when a website change has broken its extraction and repairs the extraction code within limits you set. It proves the repair with tests and hands the problem to a person when it can't. The repair is usually done by an AI agent. Whether it works has surprisingly little to do with the agent.
That last part is the thing I keep relearning. I've built several of these over the past few months, and in every case the model was the easy part. What decided whether the scraper healed itself was whether the project could tell the agent what broke, where the fix goes, and how it would know it was finished.
This post is the overview: what self-healing covers, what it doesn't, how the loop works, what a repair costs, and how to keep the agent on a lead. The build order is in four things to put in place before an agent fixes your spiders, and the two demos with timings and costs are in self-healing spiders.
Why scrapers need healing at all
One of the hidden costs of web scraping at scale is maintenance. A site renames a class, moves the price into a different element, or adds a struck-through "was" price above the real one. The crawl finishes, every request returns a 200, the output has the right number of items, and the price column is empty. You find out when someone opens the export.
Any one of those fixes takes a few minutes. Across a fleet of scrapers, though, those minutes become the main thing a team does, and the time isn't in the fix. It's in noticing, pulling up the new page, finding the new element, testing the selector against a few pages, review, deploy, and re-running the jobs. The saving from self-healing scales with how many scrapers you run, not with how hard any one repair is.
What self-healing fixes, and what it doesn't
"Self-healing" gets used for several unrelated recoveries, and most tools only do one of them. It helps to name the failure before deciding who should fix it.
| Failure | What recovers from it |
|---|---|
| Blocked or banned | The access layer: proxies, browser rendering, unblocking |
| Burned session (200 status, degraded or poisoned content) | Session management: discard it, start a clean one |
| Pagination or URL structure changed | Crawl logic and navigation |
| Broken selectors after a layout change | The extraction layer |
| Plausible but wrong data | Validation and monitoring |
When I say self-healing scraper, I mean the fourth row, with the fifth row as the thing that catches it. Extraction is the layer that gets automated first for good reasons. The input is bounded, one page and one field. There's a known previous answer to compare against, so the fix is checkable. A wrong fix breaks one field in one spider and is cheap to roll back. None of that is true of a block. There's no "correct" answer to a 403 that you can diff a fix against, and the recovery belongs to whatever handles access, not to a code change.
Some projects use the term for access failures too, and we've written one of those ourselves. It's a different loop with different checks, so this post keeps the term for extraction.
Self-healing also doesn't cover a site that removed the data. If the field is gone from the HTML, the right response is an alert and a decision, and the best thing an agent can do is recognise that and say so.
How a self-healing scraper works
Every working version I've seen or built has the same shape. Something detects the failure and describes it precisely. The agent repairs the code in a copy of the project, tests decide whether the repair is correct, and a script, not the agent, decides what happens next.
Detect during the crawl
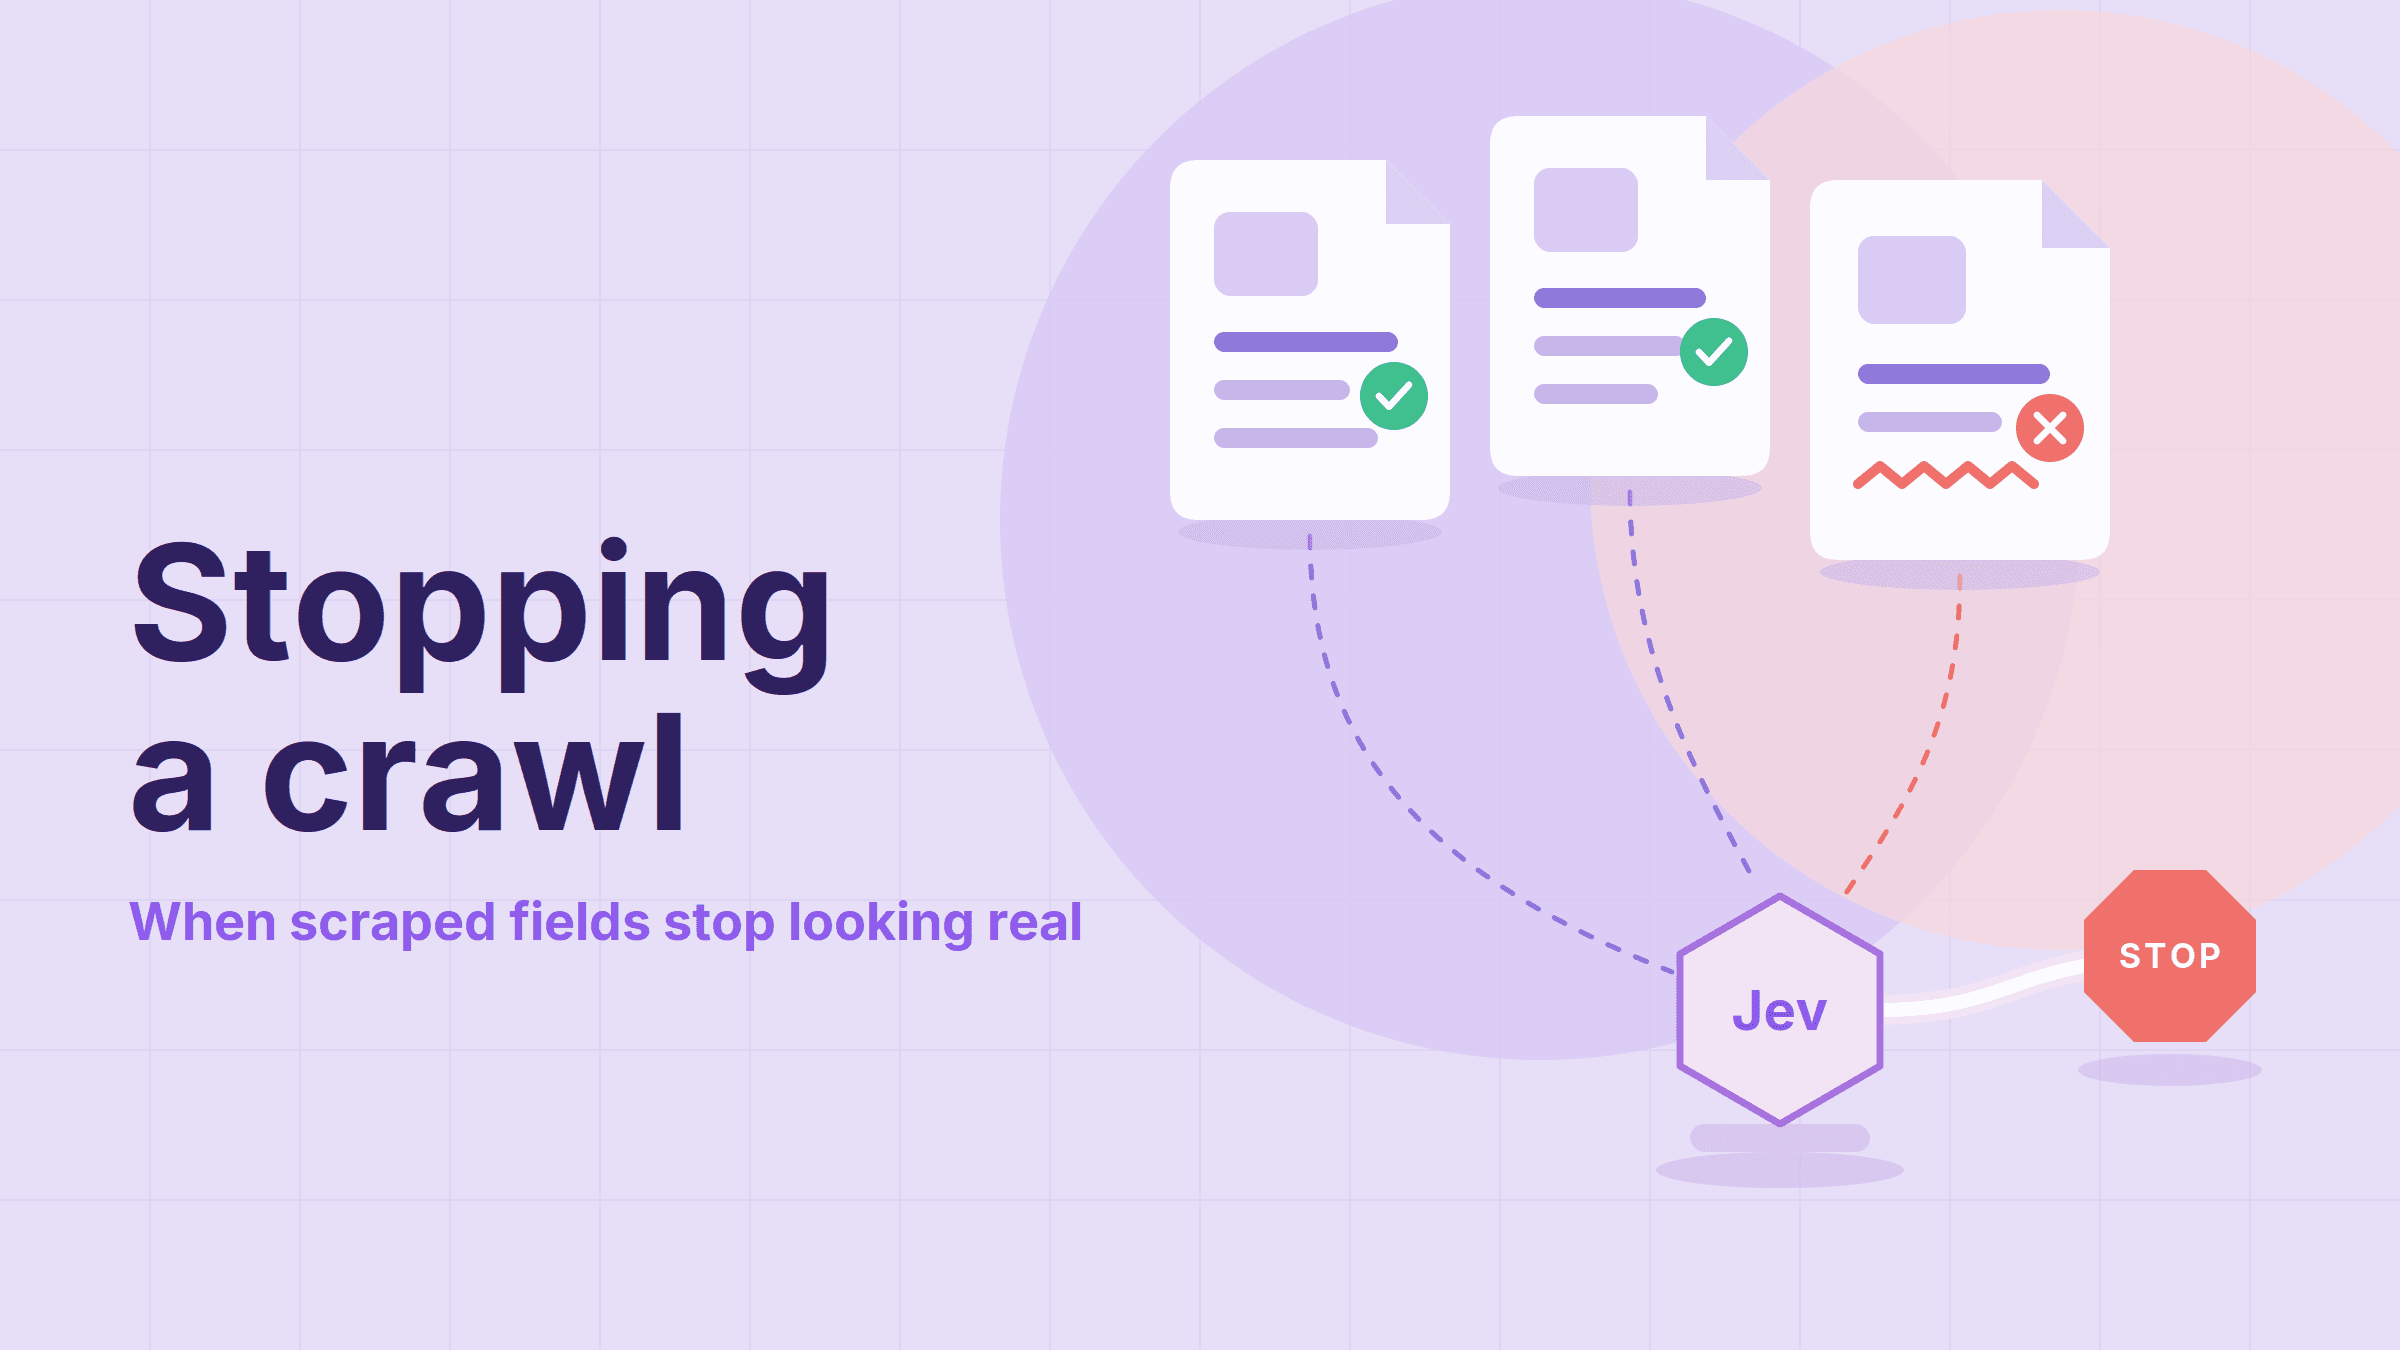
A scraper that finishes with 200s and empty fields hasn't failed by any measure Scrapy keeps by default. Detection has to look at the items. In my Scrapy projects that's Spidermon validating items against a schema and failing the run when a required field stops looking real, ideally while the crawl is still running rather than at the end.
Describe the failure precisely
The monitor's first version of the failure was AssertionError: 2 != 0, which tells an agent nothing. What it receives now is a structured incident, trimmed here:
1{
2  "failures": [{
3    "monitor_id": "base.monitors.CoffeeHealthMonitor.test_valid_items",
4    "reason": "2/2 items failed schema validation; field errors: {'price': 2}"
5  }],
6  "metrics": {"invalid_item_ratio": 1.0, "download_exceptions": 0},
7  "invalid_samples": [{
8    "url": "https://coffee.hylnd7.com/product/lumiere-uno-200-esp001",
9    "item": {"name": "Lumiere Uno 200", "price": null, "currency": "GBP"},
10    "errors": [{"field": "price", "message": "None is not of type 'string'"}]
11  }],
12  "source": {"page_class": "base.pages.coffee_hylnd7_com.CoffeeHylnd7ProductPage"}
13}That gives the agent the spider, the field, and the exact page object responsible. The sample item shows that name and currency still extract, so this is a layout change and not a block, and zero download exceptions confirm it. Most of the effort in self-healing went here, before any agent existed.
Give the agent one place to edit
Extraction lives in page objects, separate from the spider, with one method per field:
1@field
2def price(self) -> str | None:
3    raw = self.css("article.detail .detail-meta .price::text").get()
4    match = re.search(r"\d[\d,]*(?:\.\d+)?", raw or "")
5 return format(Decimal(match.group().replace(",", "")), ".2f") if match else NoneSo the instruction is: price is missing, this method produces it, that's the code you may change. The agent is also told what it may not touch, which matters as much, because an agent that's allowed to edit anything will happily make a test pass by making the field optional.
Fetch the page as it is now
The agent needs the current page, fetched the way the spider fetches it. If the spider goes through Zyte API and the agent uses plain requests, it may get a different page or a block and then it's debugging the wrong thing. In my setup it captures fresh fixtures with scrapy-poet's savefixture command, using the spider's own settings, for up to three of the failing URLs.
Decide what correct means before editing
This is where naive versions go wrong, so: do not take the expected value from the fresh fixture's output. The broken page object produced it, so the expectation says price: null and a test built from it passes with the bug still there. The expected values for the broken field have to come from somewhere else. In my loop the agent reads the fresh HTML, writes down what the price should be and quotes the HTML it got it from. The harness, meaning the script around the agent, freezes those expectations and confirms the new tests fail against the original code. Only then does the repair start. The old fixtures stay in the suite, so the fix also has to keep working on the pages that used to work.
Repair, verify, and let the script decide
The agent edits the one file, runs the suite, reads the failures, and tries again, up to a cap. When the suite is green the harness reruns the tests itself, replays the saved items through Spidermon, optionally runs a small live crawl, and writes a patch and a report. Whether that patch applies automatically or waits for review is your trust decision, not the agent's. I'd start with review and relax it only for the kinds of change that have never surprised you.
The four things that make this loop possible, with the reasoning behind each, are the subject of the build-order post. The full walkthrough of the Scrapy version is on dev.to.
What a repair costs
The numbers below are from test shops we control, with one deliberate break each. They're an illustration of the scale, not a benchmark.
In the coffee-shop project above, the broken price selector took the agent one edit and about 40 seconds including fixture capture and verification. All 70 tests passed, old fixtures and new, and the live probe came back healthy.
In the two demos from our Extract Summit workshop, a bookshop redesign nulled every field. Claude Opus 5.5 healed it on the first attempt in each of seven runs, at $0.07 to $0.16, in 24 to 31 seconds and four to seven agent turns. A single-selector break on a live crawl, healed mid-run through the Scrapy MCP, came in at $0.06 and 10 seconds on Sonnet.
| Model | Cost per heal | Time | Healed first attempt |
|---|---|---|---|
| Claude Haiku | $0.06 to $0.08 | 37 to 50 s | 3 of 3 |
| Claude Sonnet | $0.07 to $0.09 | 15 to 18 s | 3 of 3 |
| Claude Opus | $0.12 to $0.14 | 22 to 31 s | 3 of 3 |
Two things from those runs matter more than the prices. When the agent lost shell access it escalated every time after two failed attempts, because it couldn't run the tests. And one "successful" heal produced prices 25 percent too high by picking up the wrong element, which only a comparison against a known-good sample caught. A green check is not a correct fix.
Keeping a lid on the agent
Every loop that's worked has had hard limits, enforced by the script rather than by the prompt.
- One file. The agent may edit the page object and nothing else. The schema, the monitors, the tests and the crawl controls are locked, and a guard reverts edits to locked files.
- A small tool set. Read, edit, and the few commands it needs. No general shell when the loop can run the tests for it.
- An attempt cap. Two or three tries, then escalate with the evidence attached.
- The script decides. The agent proposes a change. The script runs the checks, applies or rejects, and pauses or resumes the crawl. The agent never touches those controls.
- A known-good comparison. Fixture tests with expected values that didn't come from the broken code, plus a golden sample for the fields that matter most.
Under those limits an agent is a cheap, fast selector mechanic. Without them it's a liability with a commit bit.
Other approaches to the same problem
The code-repair loop above isn't the only design, and it's worth knowing the alternatives.
Fallback chains try CSS selectors first, then regex, then fuzzy text matching, then an LLM reading the raw HTML. They keep data flowing through a break, which is the attraction. The risk is that nothing tells you the break happened, and the LLM tier is where plausible wrong values come from.
LLM-generated scrapers have a model write or regenerate the extraction code and re-run it when it fails. Projects like crawloop and scrapemend describe variations on this, usually with caching so the model is only called when selectors stop matching.
Hosted platforms such as Kadoa build and maintain the scraper for you, with repair proposals that wait for approval.
All of them land on the same two lessons the repair loop does: call the model only when deterministic extraction fails, and treat an unverified fix as the main risk. The difference is where the verification lives and who owns the code afterwards. With the repair loop it's your tests and your repository, which is why I prefer it for scrapers that someone is going to maintain for years.
Reduce maintenance, don't pretend to eliminate it
Self-healing won't fix every scraping problem and it shouldn't try. The failures that get the agent are the small, repetitive ones: a moved element, a renamed class, a field that quietly went null. Blocks, navigation changes and a site that removed the data still need a person, and the agent's job with those is to recognise them and escalate.
If there's one thing to take from this, it's that the work is in the handoff. Monitoring that describes the failure, extraction code with one obvious place to change, a way to fetch the current page, and tests whose expected answers don't come from the broken code. Get those right and the agent is almost interchangeable. Skip them and the model won't make up the difference.
Questions and answers
Is a self-healing scraper the same as an AI scraper?
No. An AI scraper uses a model to extract data on every page. A self-healing scraper runs deterministic extraction and calls a model only to repair the code when monitoring says it broke, so the per-page cost stays at zero and the output stays predictable.
Does a self-healing scraper need an LLM?
Not strictly. The detection, the fixtures and the verification are all plain code. The LLM is the part that proposes a new selector, and it's the part that's easiest to swap. In our runs Haiku, Sonnet and Opus all healed a simple break on the first attempt.
How do you know the fix is correct and not just passing?
The expected values in the tests have to come from the page, not from the broken code. The old fixtures have to keep passing, and for important fields you compare against a known-good sample. A fix that produced prices 25 percent too high passed every test until that comparison caught it.
What happens when the website removes the data?
The agent can't heal that, and it shouldn't try. A good loop reports that the field no longer exists in the HTML and escalates, rather than returning a plausible value from somewhere else on the page.
How much does a repair cost?
On our test shops, between six and sixteen cents and under a minute per heal across Claude Haiku, Sonnet and Opus. Real sites with more complex pages will cost more, but the order of magnitude is cents, not the hour of someone's time.
Can I do this without Scrapy?
Yes. The loop needs monitoring that names the broken field, extraction code with one place to edit, a way to fetch the current page the way the scraper does, and tests with expected values. Scrapy, Spidermon and scrapy-poet give you those out of the box, but any stack can provide them.