What's coming in 2025 for web scraping developers?
It wasn’t too long ago that extracting data from the web required stitching together complex systems, managing proxies, and manually handling bans—often through trial and error. Developers spent countless hours maintaining scrapers and solving problems that had nothing to do with their core goals. And maybe this is still true for you.
Today, however, the landscape looks very different.
The explosion of AI-driven tools, low-code solutions, and user-friendly libraries has opened the doors for more developers to dip their toes into web data extraction.
But here’s the catch: having a scraper doesn’t automatically translate into having data at scale. Building a scraper is one thing—scaling it to handle complex, high-volume operations is another.
Why achieving scale in web scraping is still hard
Scaling web scraping isn’t just about running more scripts or scraping more pages.
Today, websites aggressively defend their data with advanced anti-bot measures like ReCAPTCHA, adaptive security from services like Cloudflare, and behavioral detection systems.
Even subtle user behaviors, such as mouse movements and scrolling patterns, are monitored to weed out automated bots. Without sophisticated, evolving solutions, maintaining consistent data pipelines becomes tricky.
Costs are another major hurdle in scaling efforts.
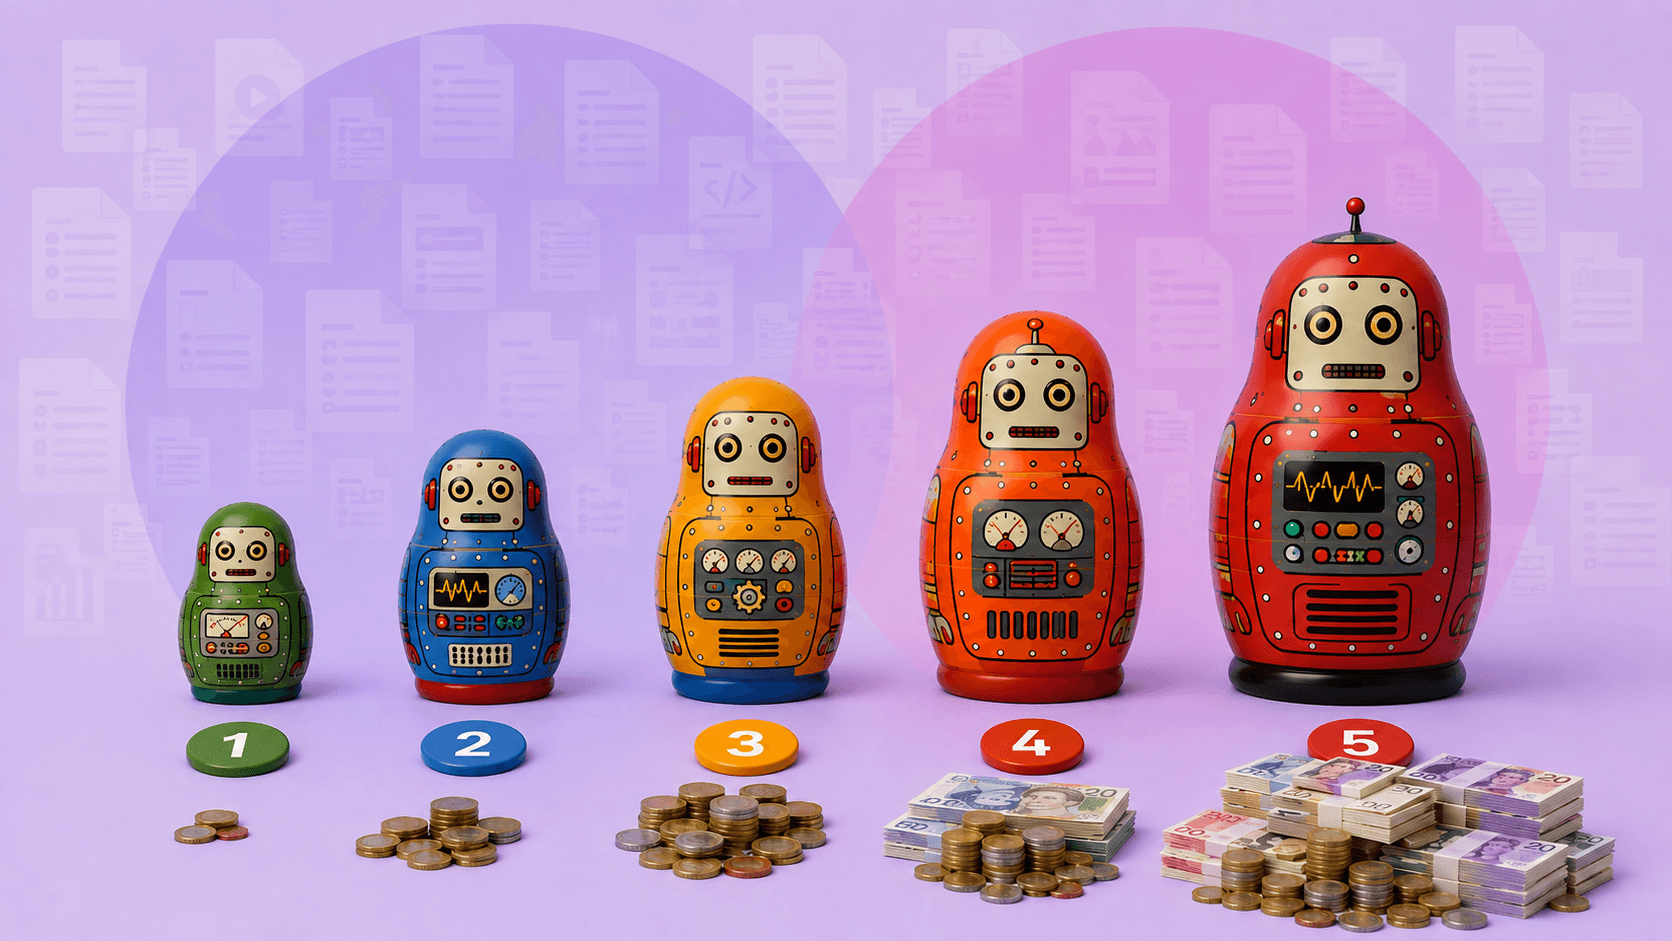
AI-powered scraping solutions may seem efficient on the surface, but they can introduce hidden infrastructure costs.
Zyte’s 2025 Web Scraping Industry Report revealed that using large language models (LLMs) for data extraction can be up to 50 times more expensive than traditional methods if not optimized carefully. Balancing the high performance with cost efficiency becomes a daily battle, especially when managing proxies and adapting to changing site structures.

This raises critical questions for developers: Can you trust AI-powered scrapers to handle the heavy lifting without increasing infrastructure costs? How can you efficiently manage proxies, handle bans, and adapt to website changes without sacrificing sleep? Perhaps most importantly, how much do you really need to understand under the hood, and when is it okay to lean on “automagical” tools to get the job done?
Productivity in the age of AI: finding your edge
The explosion of AI tools in web scraping has introduced a new challenge for developers: H_ow can I stay relevant in an AI-driven world?_
Some developers worry that automation will replace their expertise, but that’s not the point. It’s no longer about writing endless lines of code for every scraper but about knowing how and when to leverage automation.

Automation excels at handling repetitive, time-consuming tasks. However, solving complex challenges—like adapting to evolving anti-bot defenses or ensuring data compliance—still requires human oversight, creativity, and ingenuity.
Then, there’s the balancing act between performance and cost. While AI-powered tools can kickstart scraping, they can quickly become expensive if not used wisely. Continuously evaluating cost efficiency ensures that scraping projects stay scalable and profitable.
Shaping the future of web scraping
The future of web scraping is full of opportunities for developers ready to adapt.
Tools are becoming smarter and more efficient, making it easier to offload tedious tasks and focus on solving the problems that matter. Those who understand how to integrate these tools into scalable workflows will survive and thrive.
It’s not about choosing between automation and expertise—it’s about blending them to build more resilient and adaptable systems.
Developers who stay curious, explore how these technologies work, and use them strategically will lead the next phase of web data extraction. The tools are here; now it’s about how you use them.
Access our full report on 2025 industry trends to discover how to stay ahead in 2025 and beyond.