Anti-ban
Articles from the Zyte blog about Anti-ban.
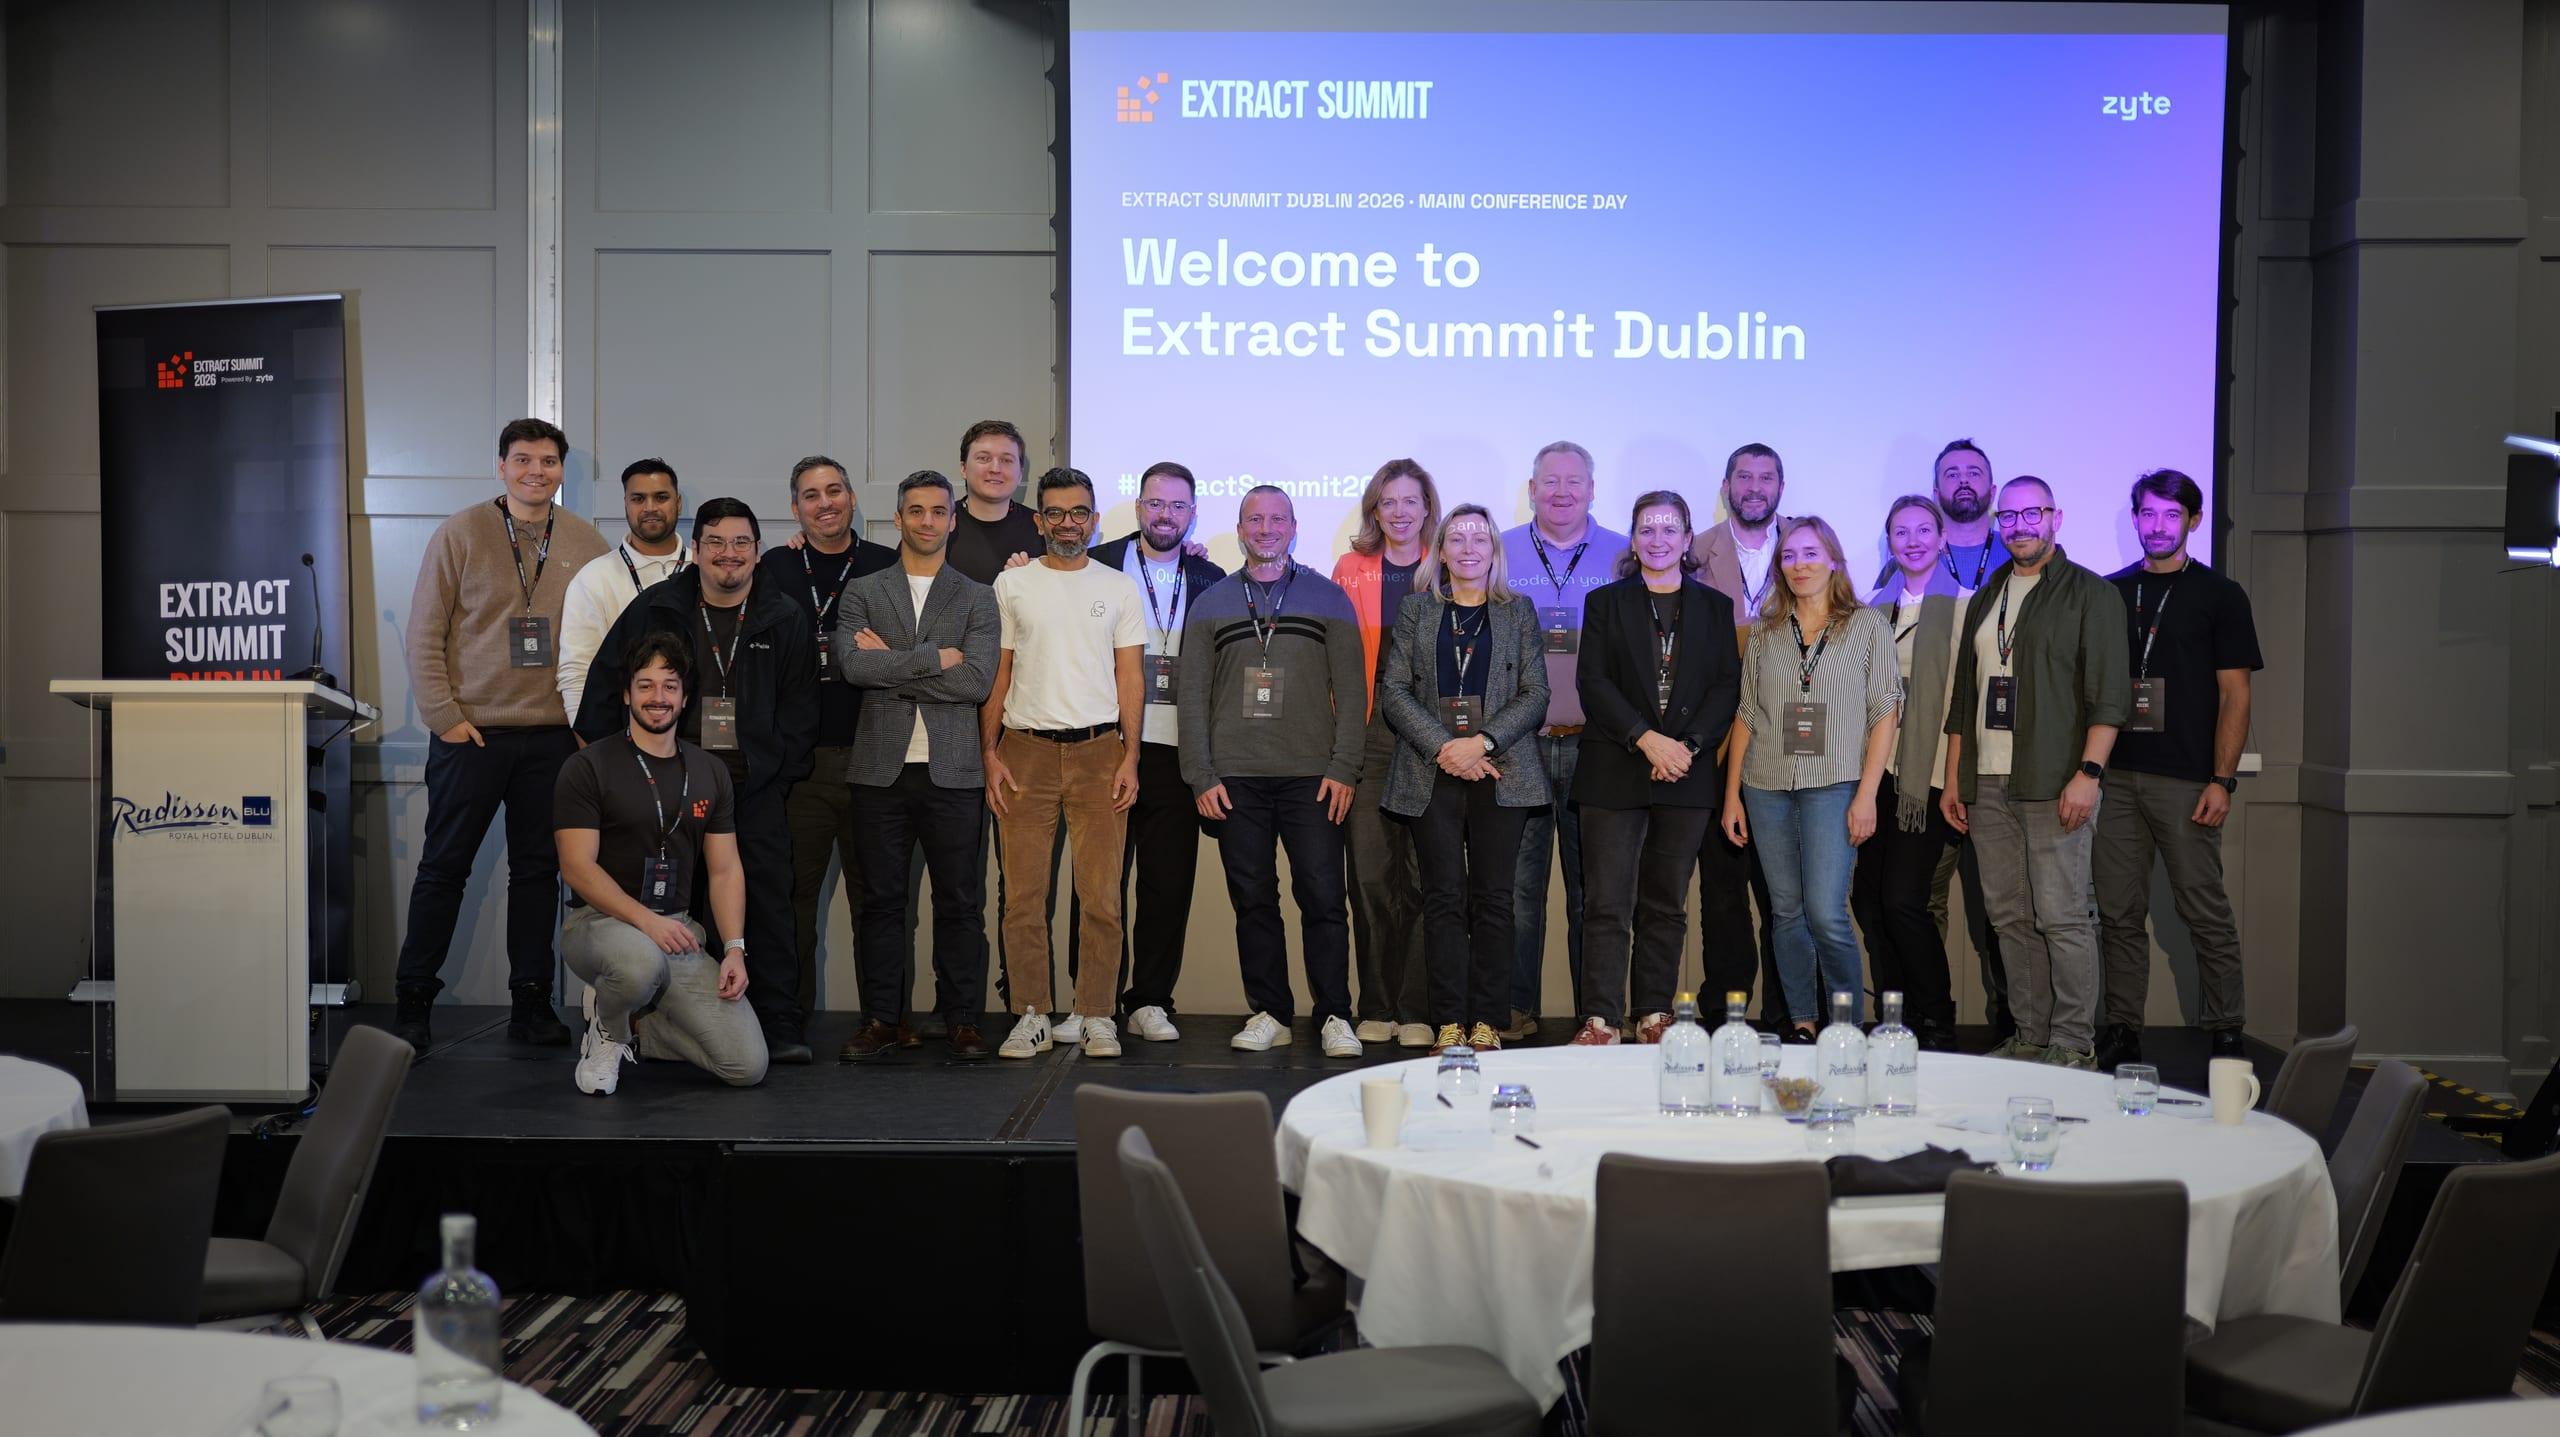
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
Web Scraping for RAG: Build a Reliable Pipeline with Zyte API, Qdrant and LangChain
Build a RAG pipeline that survives bot blocks and JavaScript pages: fetch LLM-ready Markdown with Zyte API, gate bad pages, and test it before deploying.
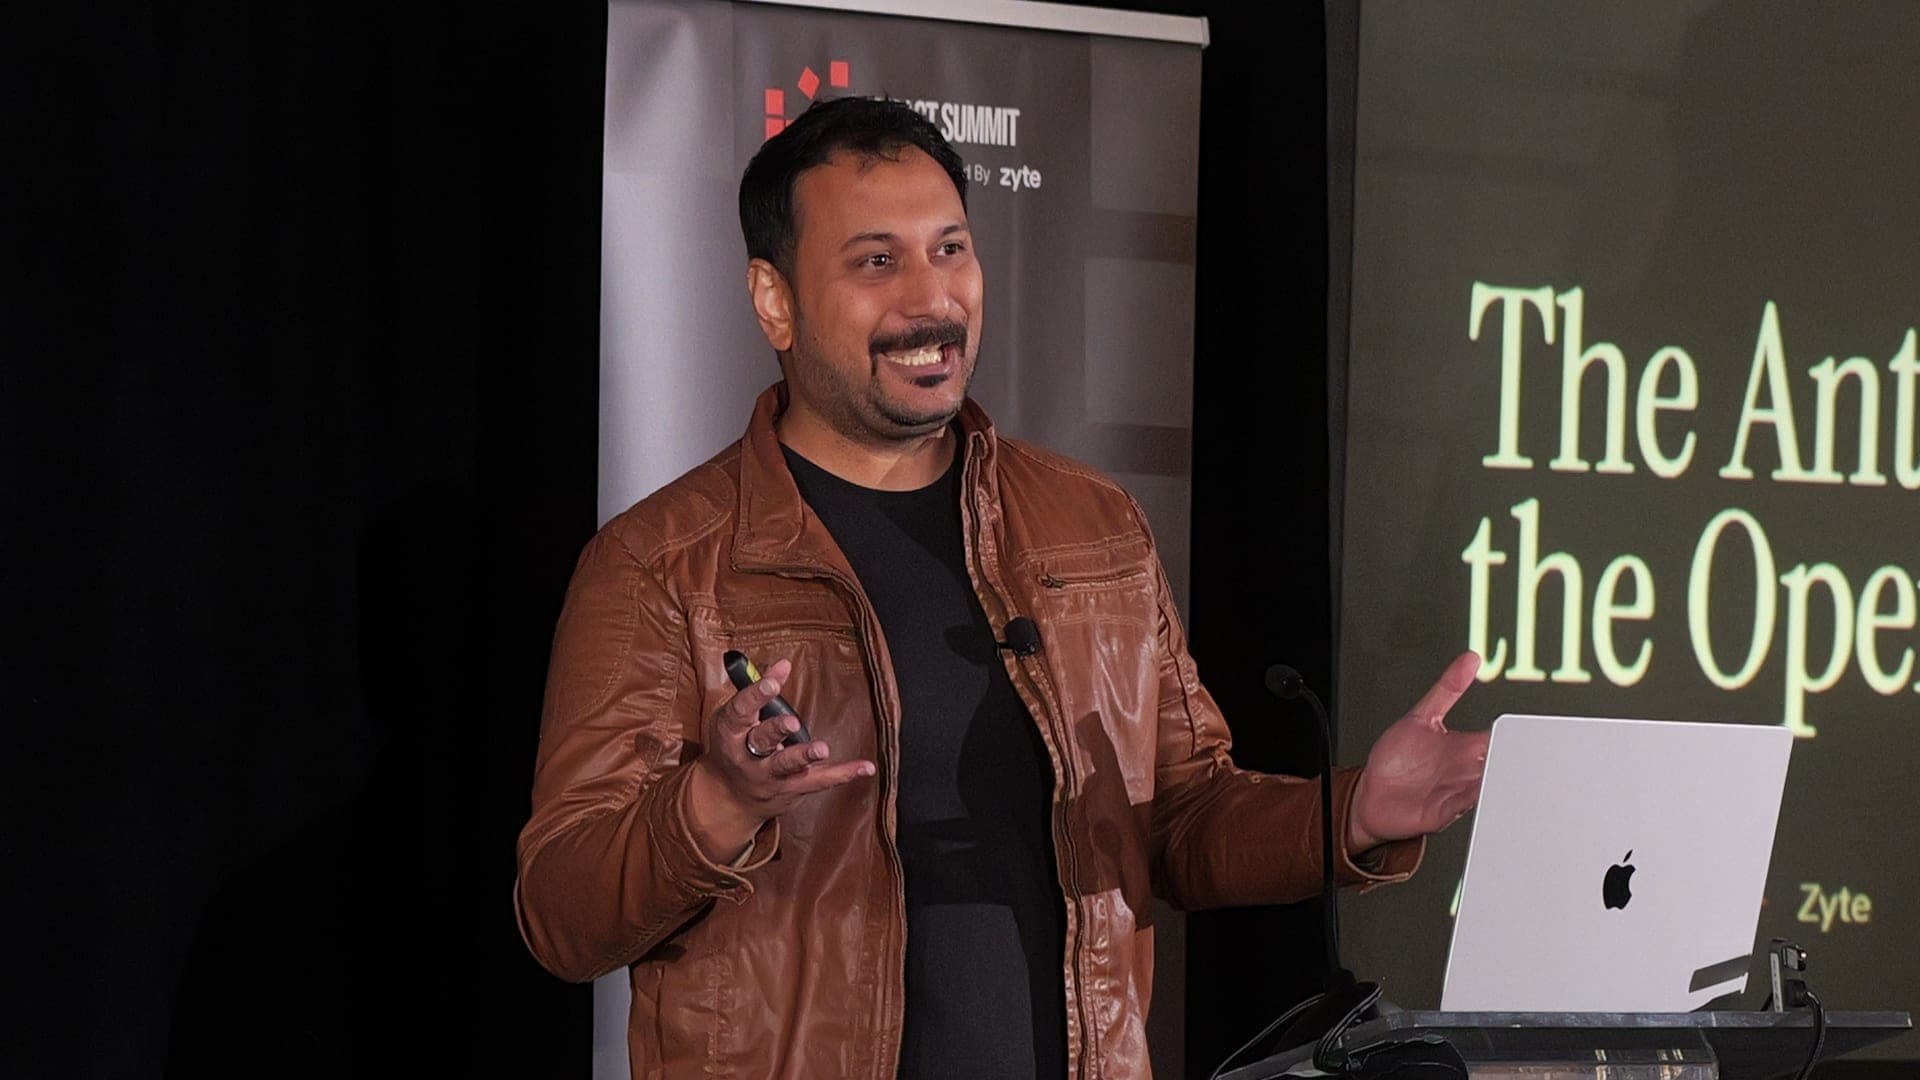
The anti-ban arms race: Agentic traffic and the fight for the open web
As AI agents transform how we interact with the web, anti-bot systems threaten to fence off the digital open range.
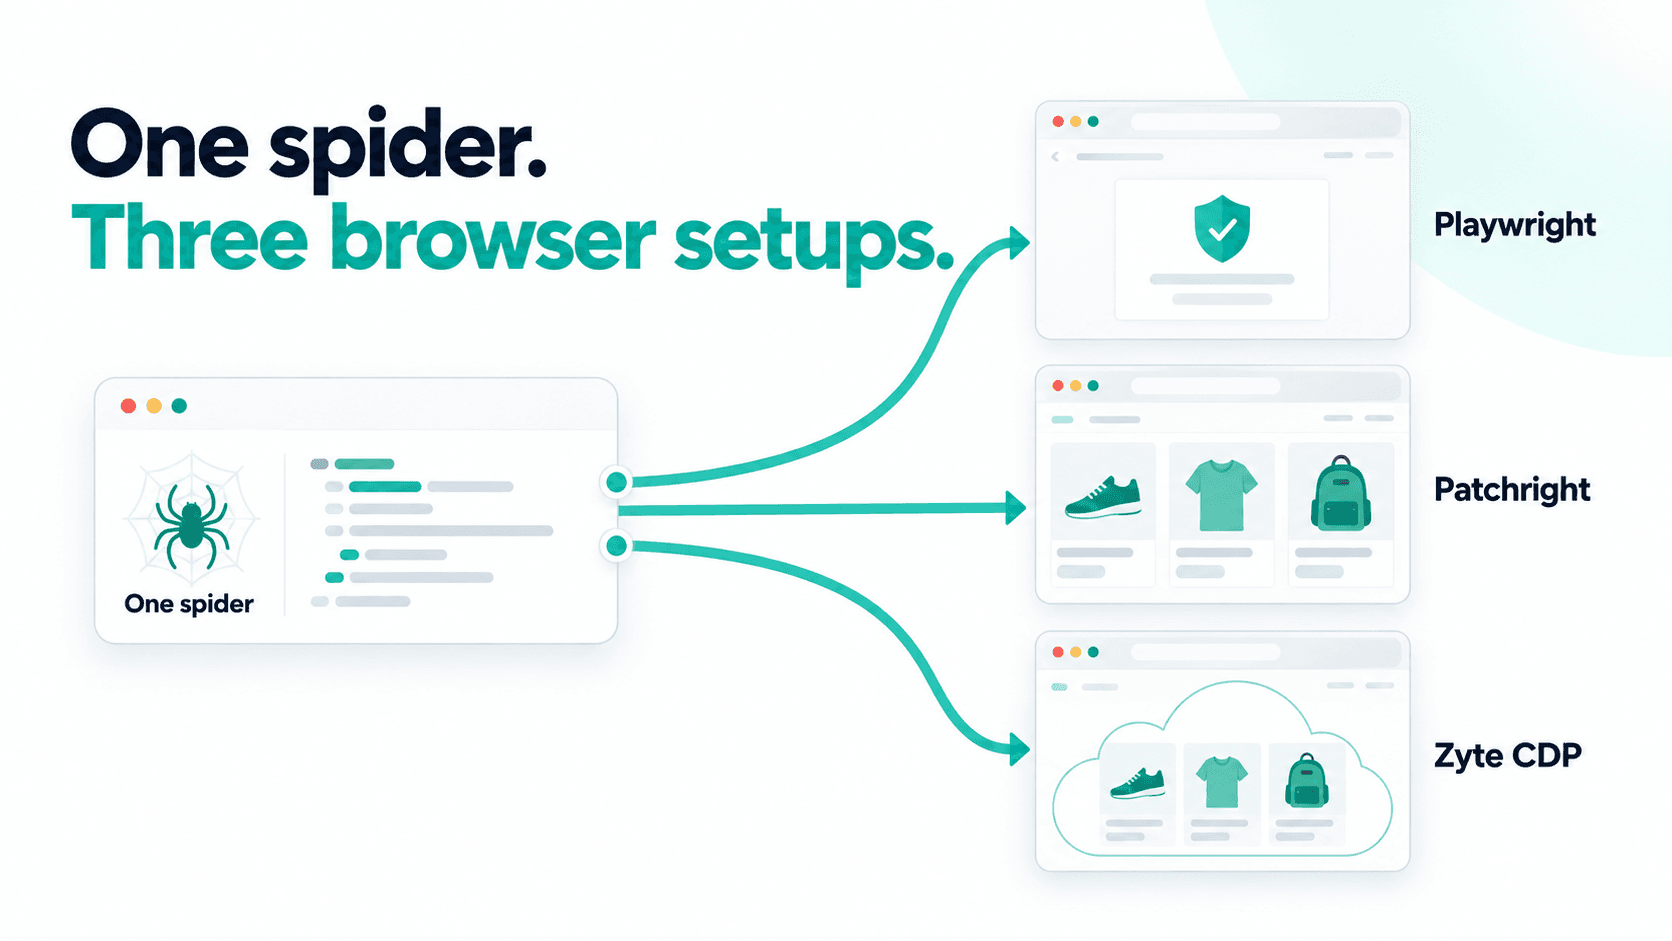
One scrapy-playwright Spider, Three Browser Setups: Playwright, Patchright, and Zyte
One Scrapy spider, three browser setups: stock Playwright, Patchright via the new PLAYWRIGHT_BROWSER_PROVIDER hook, and a remote browser on Zyte over CDP. Same spider and selectors throughout, only the browser changes.
The recipe for a request: Scaling data extraction through investigation
Learn how an investigative mindset helps scale data extraction from single requests to millions daily by building resilient, efficient scraping systems.
Hybrid scraping: The architecture for the modern web
Learn how hybrid scraping combines headless browsers and lightweight HTTP clients to bypass JavaScript challenges efficiently. Reduce RAM usage, improve speed, and scale your web scraping pipelines with session reuse and TLS fingerprinting.
Beyond the block: The front line of data access
A deep dive into the evolving battle for web data access—featuring insights from Castle, Scrapoxy, and Zyte at Extract Summit 2025. Learn how AI, anti-bots, economics, and authentication standards like Web Bot Auth are transforming scraping, security, and the future of the open internet.
How an analytics platform solved a ‘hard-to-scrape’ site using Zyte API
See how Zyte API automatically unblocked a major e-commerce site, cutting costs and boosting success rates from 60% to 98%.

Unblockers vs Zyte API: What’s the Real Cost of Bans?
Not all unblockers are equal. Learn how Zyte API automates unblocking and why predictable success rates save more than cheap bandwidth.
Why your spiders keep getting banned, and how to fix it
Learn why scrapers get blocked and how modern unblocking APIs like Zyte API automate ban handling for faster, more reliable data extraction.

How Session Management Minimizes Bans and Enhances Data Quality in Web Scraping
Learn how managing user sessions in web scraping can help overcome website bans, handle IP rate limits, streamline cookie management, and avoid detection.
How to Bypass IP Bans with Ease
Understanding how to bypass IP bans is essential to anyone who wants to collect web data at any scale.