How To
Articles from the Zyte blog about How To.
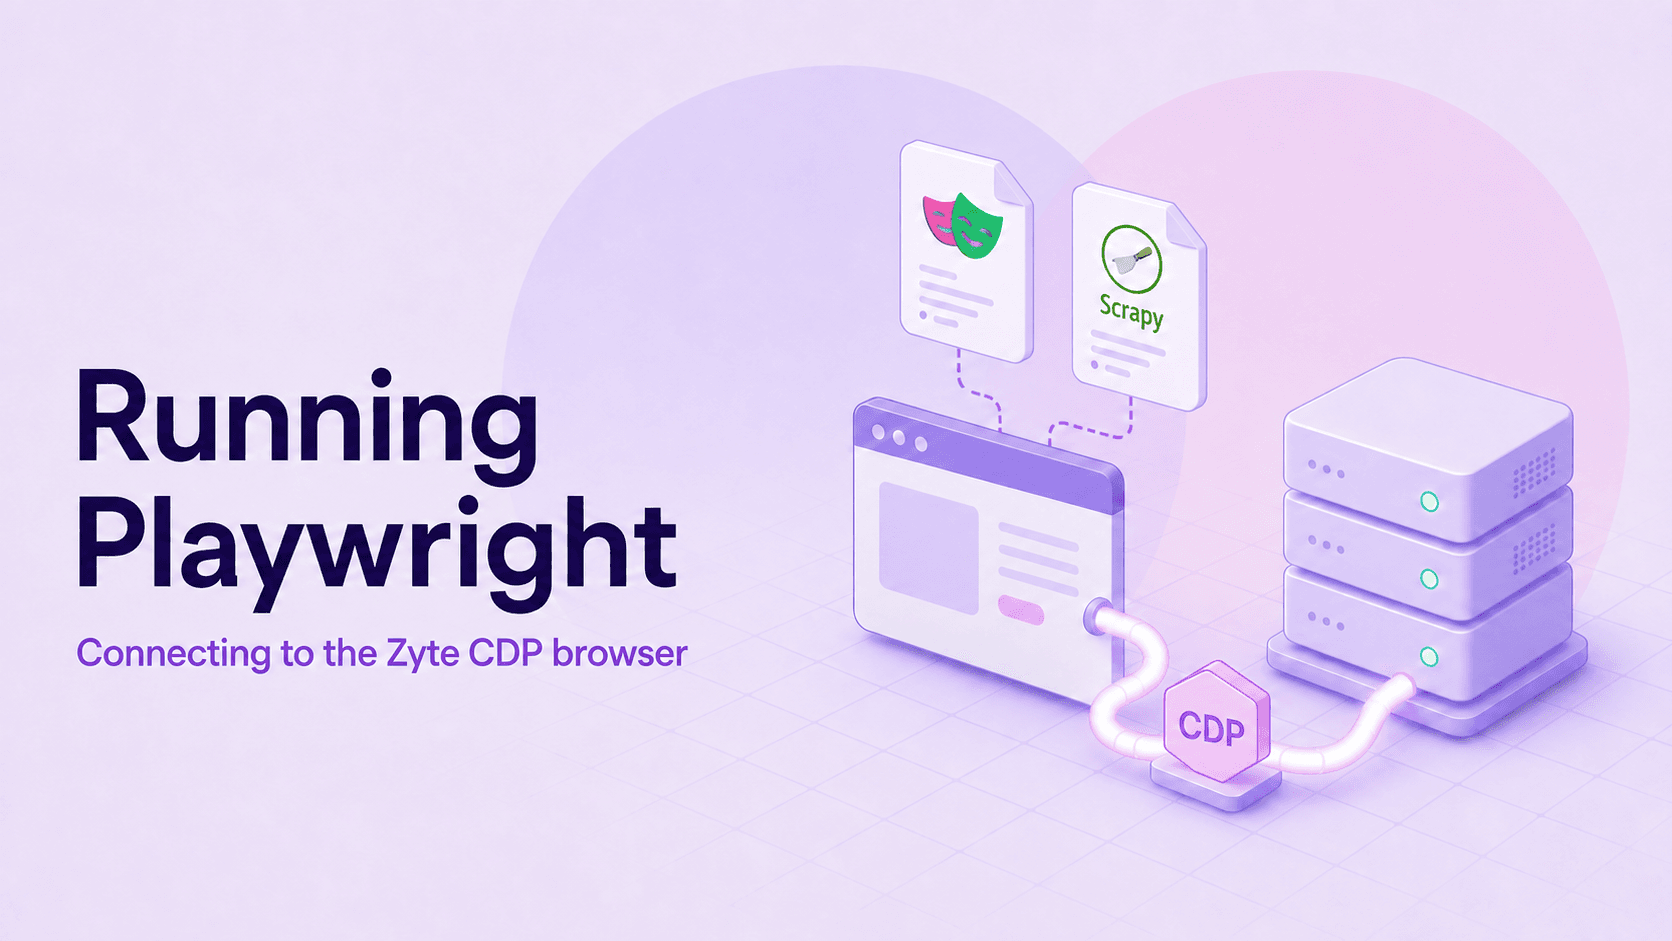
Running Playwright at scale: connecting to the Zyte CDP browser
We've released our CDP Browser, ideal for those with existing Playwright scripts looking for better access, as well as developers who need granular control over a browser, but don't want the hassle of running locally.
Harness Engineering #3- Headless mode: the minimal agent harness
What's the smallest harness that still works? Turns out it's already sitting inside almost every coding agent you have installed — headless mode: same loop, tools, and reasoning as the interactive agent, minus the human in the chair. We point it at a web page and pull clean, structured data out the other end in about ten lines.
AI generated these Scrapy projects - why I won't ship them
What happens if you let AI create a Scrapy project from just a simple prompt? Here's what I got and what I had to fix.
Web scraping for pricing intelligence: how to track competitor prices at scale
Compare the best headless browsers for web scraping in 2026. Learn when to use Playwright, Puppeteer, Selenium, or Zyte API’s managed CDP browser for scalable, anti-ban scraping.
Best headless browsers for web scraping in 2026
Compare the best headless browsers for web scraping in 2026. Learn when to use Playwright, Puppeteer, Selenium, or Zyte API’s managed CDP browser for scalable, anti-ban scraping.
Best proxy providers for web scraping in 2026 | Zyte
Compare the best proxy providers for web scraping in 2026. Learn which residential, ISP, and mobile proxies work best—and when teams move beyond proxies to automation.
Hybrid Scraping: The Architecture for the Modern Web
The Modern Web Scraping Method You NEED to Know
Learn how to scrape data in json format from a websites API
Scrape, Analyze & Visualize Web Data with Streamlit
Join Hyder Khan | Data Engineer, @ Flipdish as he shares how to extract, clean, analyze, and visualize web data using a seamless workflow with Streamlit.
Sustainability in Open Source | Fireside Chat
Learn how successful open-source projects balance community value with sustainable growth. Industry leaders share insights on monetization, maintenance, and building thriving communities.
Inside Zyte's System Design Process: How We Build Scalable, Reliable Solutions
Explore Zyte’s approach to building scalable and reliable systems through PRDs, technical requirements, solution evaluation, and real-world design insights.

Advanced session management with Scrapy
Master advanced session management with Scrapy-Zyte-API. Learn techniques to optimize efficiency, streamline workflows, and gain full control over your web scraping processes.