Zyte Blog
Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
Browse
Hot topics
Latest
What we've been publishing
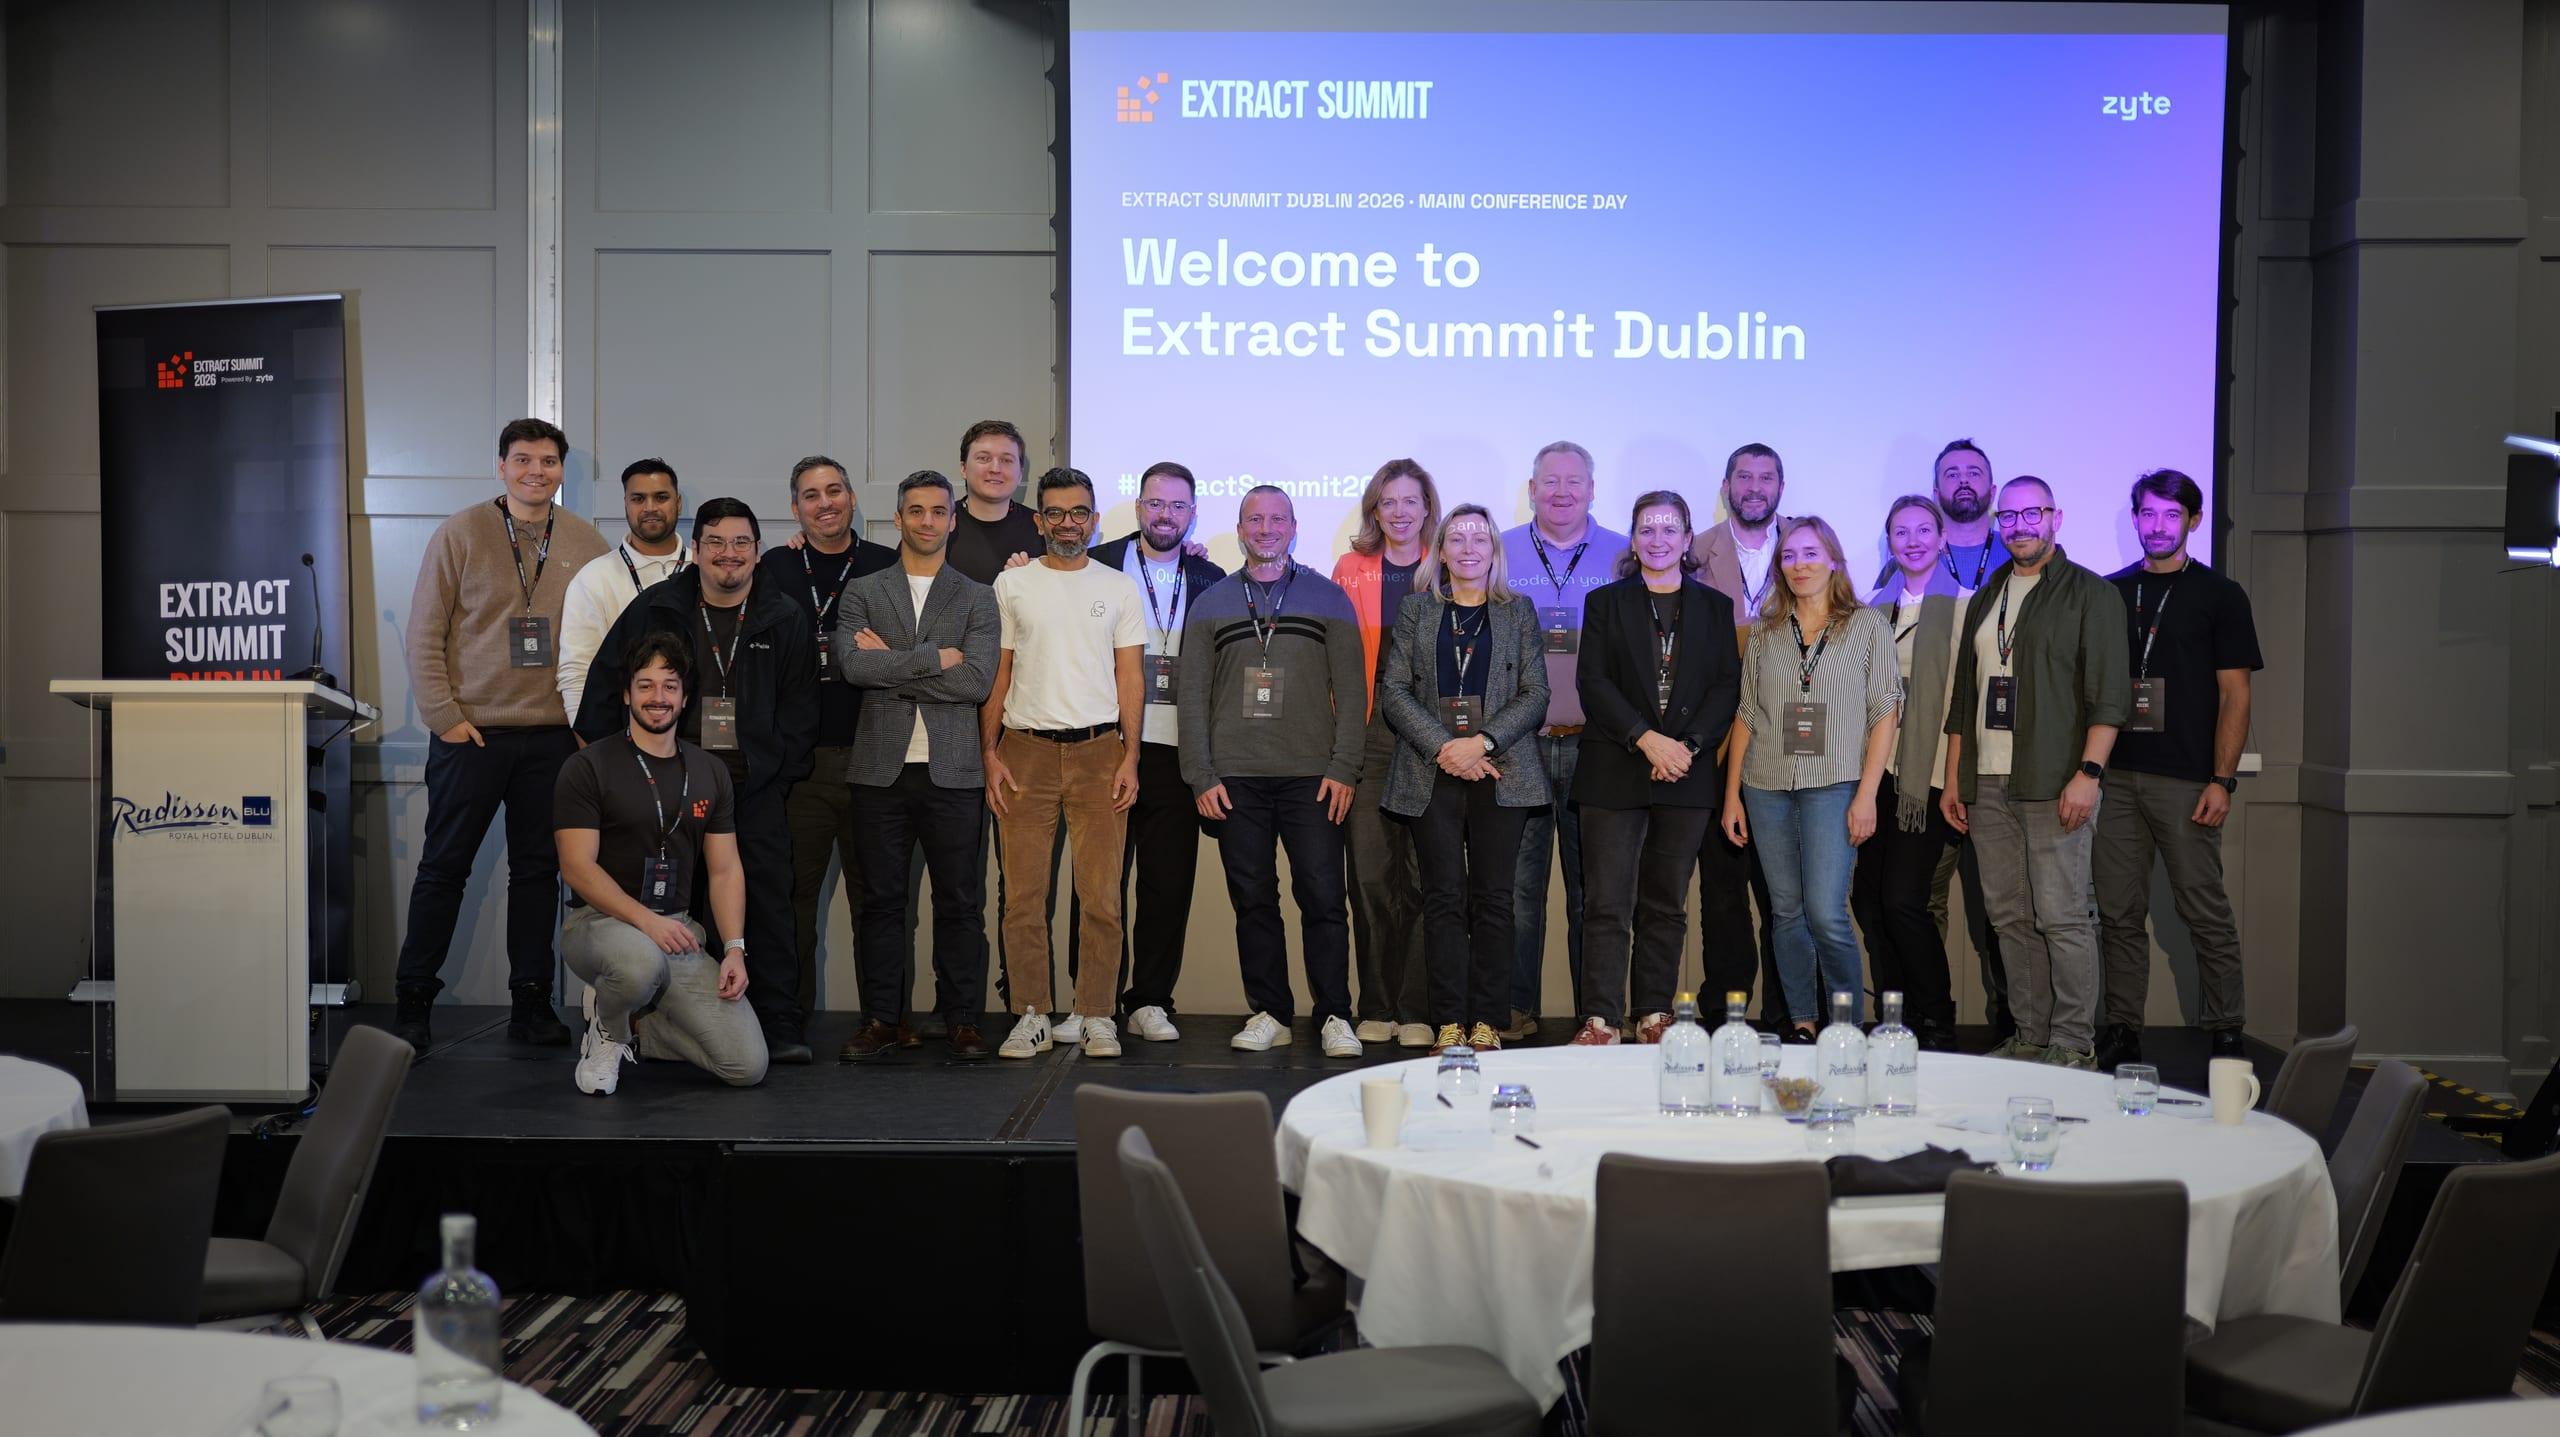
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
How do you manage the context window in Claude Code and other coding agents - like a ninja
Claude Code rarely runs out of context now, but you still pay for what you carry. 18 habits checked against the docs: /compact, /clear, caching, MCP.
Self-healing scrapers: four things to put in place before an AI agent fixes your spiders
What decides whether a self-healing scraper's repair is any good: detection during the crawl, a specific failure report, extraction code the agent can target, and tests that can fail.
Web Scraping for RAG: Build a Reliable Pipeline with Zyte API, Qdrant and LangChain
Build a RAG pipeline that survives bot blocks and JavaScript pages: fetch LLM-ready Markdown with Zyte API, gate bad pages, and test it before deploying.
How to use browser DevTools for web scraping
Before you write a scraper, use Chrome or Firefox DevTools to find where the data lives, test selectors, check whether JavaScript is involved and spot the requests worth copying.
What web access actually costs - the tier picture
The barrier headlines sound extreme, but the cost data is more differentiated: 87.9% of top sites are Simple or Easy to access - and that means cost-effective.
12 things I use Zyte MCP for, ranked, with prompts and rules you can copy
What can you use Zyte MCP for? 12 uses, 11 tested, ranked, each with a copy-paste prompt, a CLAUDE.md rule, and a skill idea.
The trouble with variants: Solving the web's infinite ecommerce explosion
Product variants can turn a straightforward ecommerce scraping project into millions of combinations. Learn how to classify, scope and control them.
Need for speed: How data inertia kills business ambition
Slow web data pipelines can hold back new markets, conversion gains and product launches.
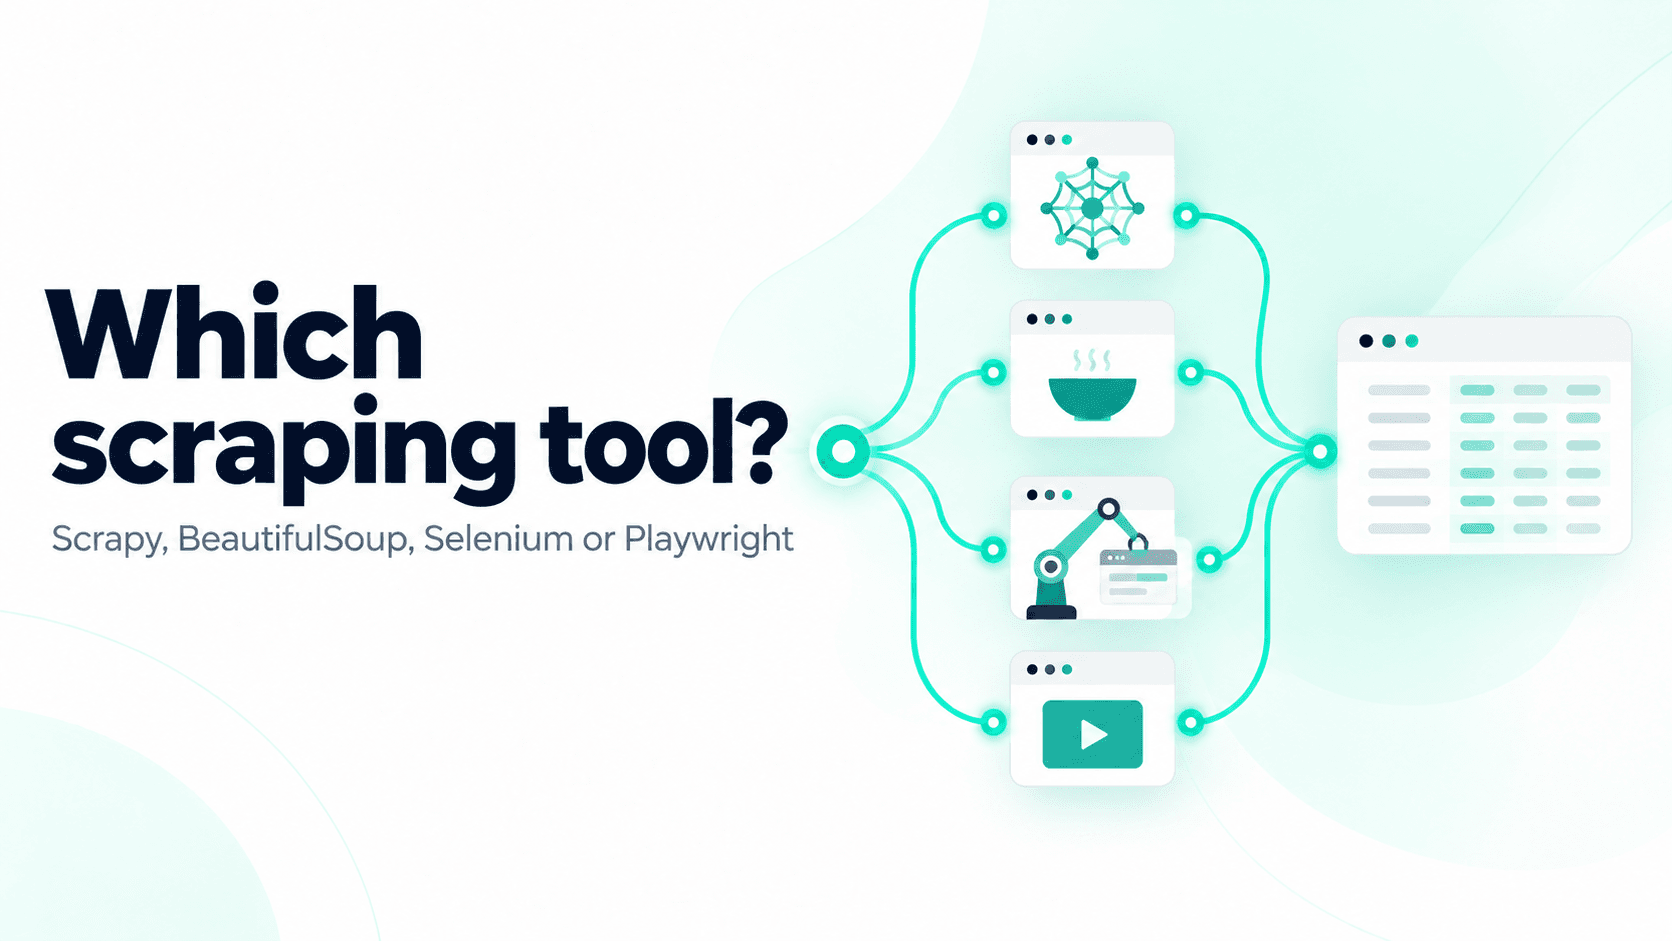
Scrapy vs BeautifulSoup vs Selenium vs Playwright: which should you use?
What each Python scraping tool does, where it fits, and how to choose, with the same scraper written in each and a simple decision guide for beginners.
The web's layered defences - how access barriers combine
Individual barriers may get the headlines, but it's stacked access control mechanisms that pose the biggest block.
How I use Zyte MCP to plan web scrapers
Zyte MCP lets my AI agent investigate a site before I write the scraper, so I can decide where the data should come from, compare an API with the rendered page for missing fields, and end up with a crawl plan I can act on.
 Bluesky
 X
 Mastodon
 LinkedIn
 Facebook
 dev.to
 RSS feed
Zyte YouTube
Watch & learn
Video · Zyte YouTube
AI generated these Scrapy projects - why I won't ship them
July 7, 2026
Video · Zyte YouTube
Screenshot webpages with this Claude Skill and Zyte API
March 6, 2026
Video · Zyte YouTube
0% Hallucination? RAG + Web Scraping (Step-by-Step)
March 5, 2026
Video · Zyte YouTube
Generate HTML Parsing code the right way with Scrapy & Web Scraping Copilot
February 23, 2026
Video · Zyte YouTube
Zyte API Sessions - flexible cookie management maintaining control
February 6, 2026
Events & community