Zyte Blog
Field notes from the world of data extraction.
Articles, interviews and analysis on how data is gathered, used and fought over — written by the people closest to it.
Browse
Hot topics
Latest
What we've been publishing
The world's hardest sites protect their prices
Only a sliver of the web demands the heaviest machinery to read. It is dominated by shops, property listings and booking engines, where every published price is somebody's market intelligence.
Inside the anti-block engine: How we built a 320,000-strategy web access hero
For data gatherers, negotiating anti-bot tech is not for the faint-hearted. That’s why we built a multi-layered system that treads lightly but brings a host of tactics to the table.
The spider that fixes itself: Help your scraper rise from the ashes
Konstantin Lopukhin explores scrapy-phoenix, an open-source prototype that uses coding agents to repair web scrapers mid-crawl, with validation checks and human escalation.
The easiest sites to scrape are the ones that want to be found
Want an easy scrape? Skip the shops and try the military. Defence, government and science sites rank among the most open on the web.
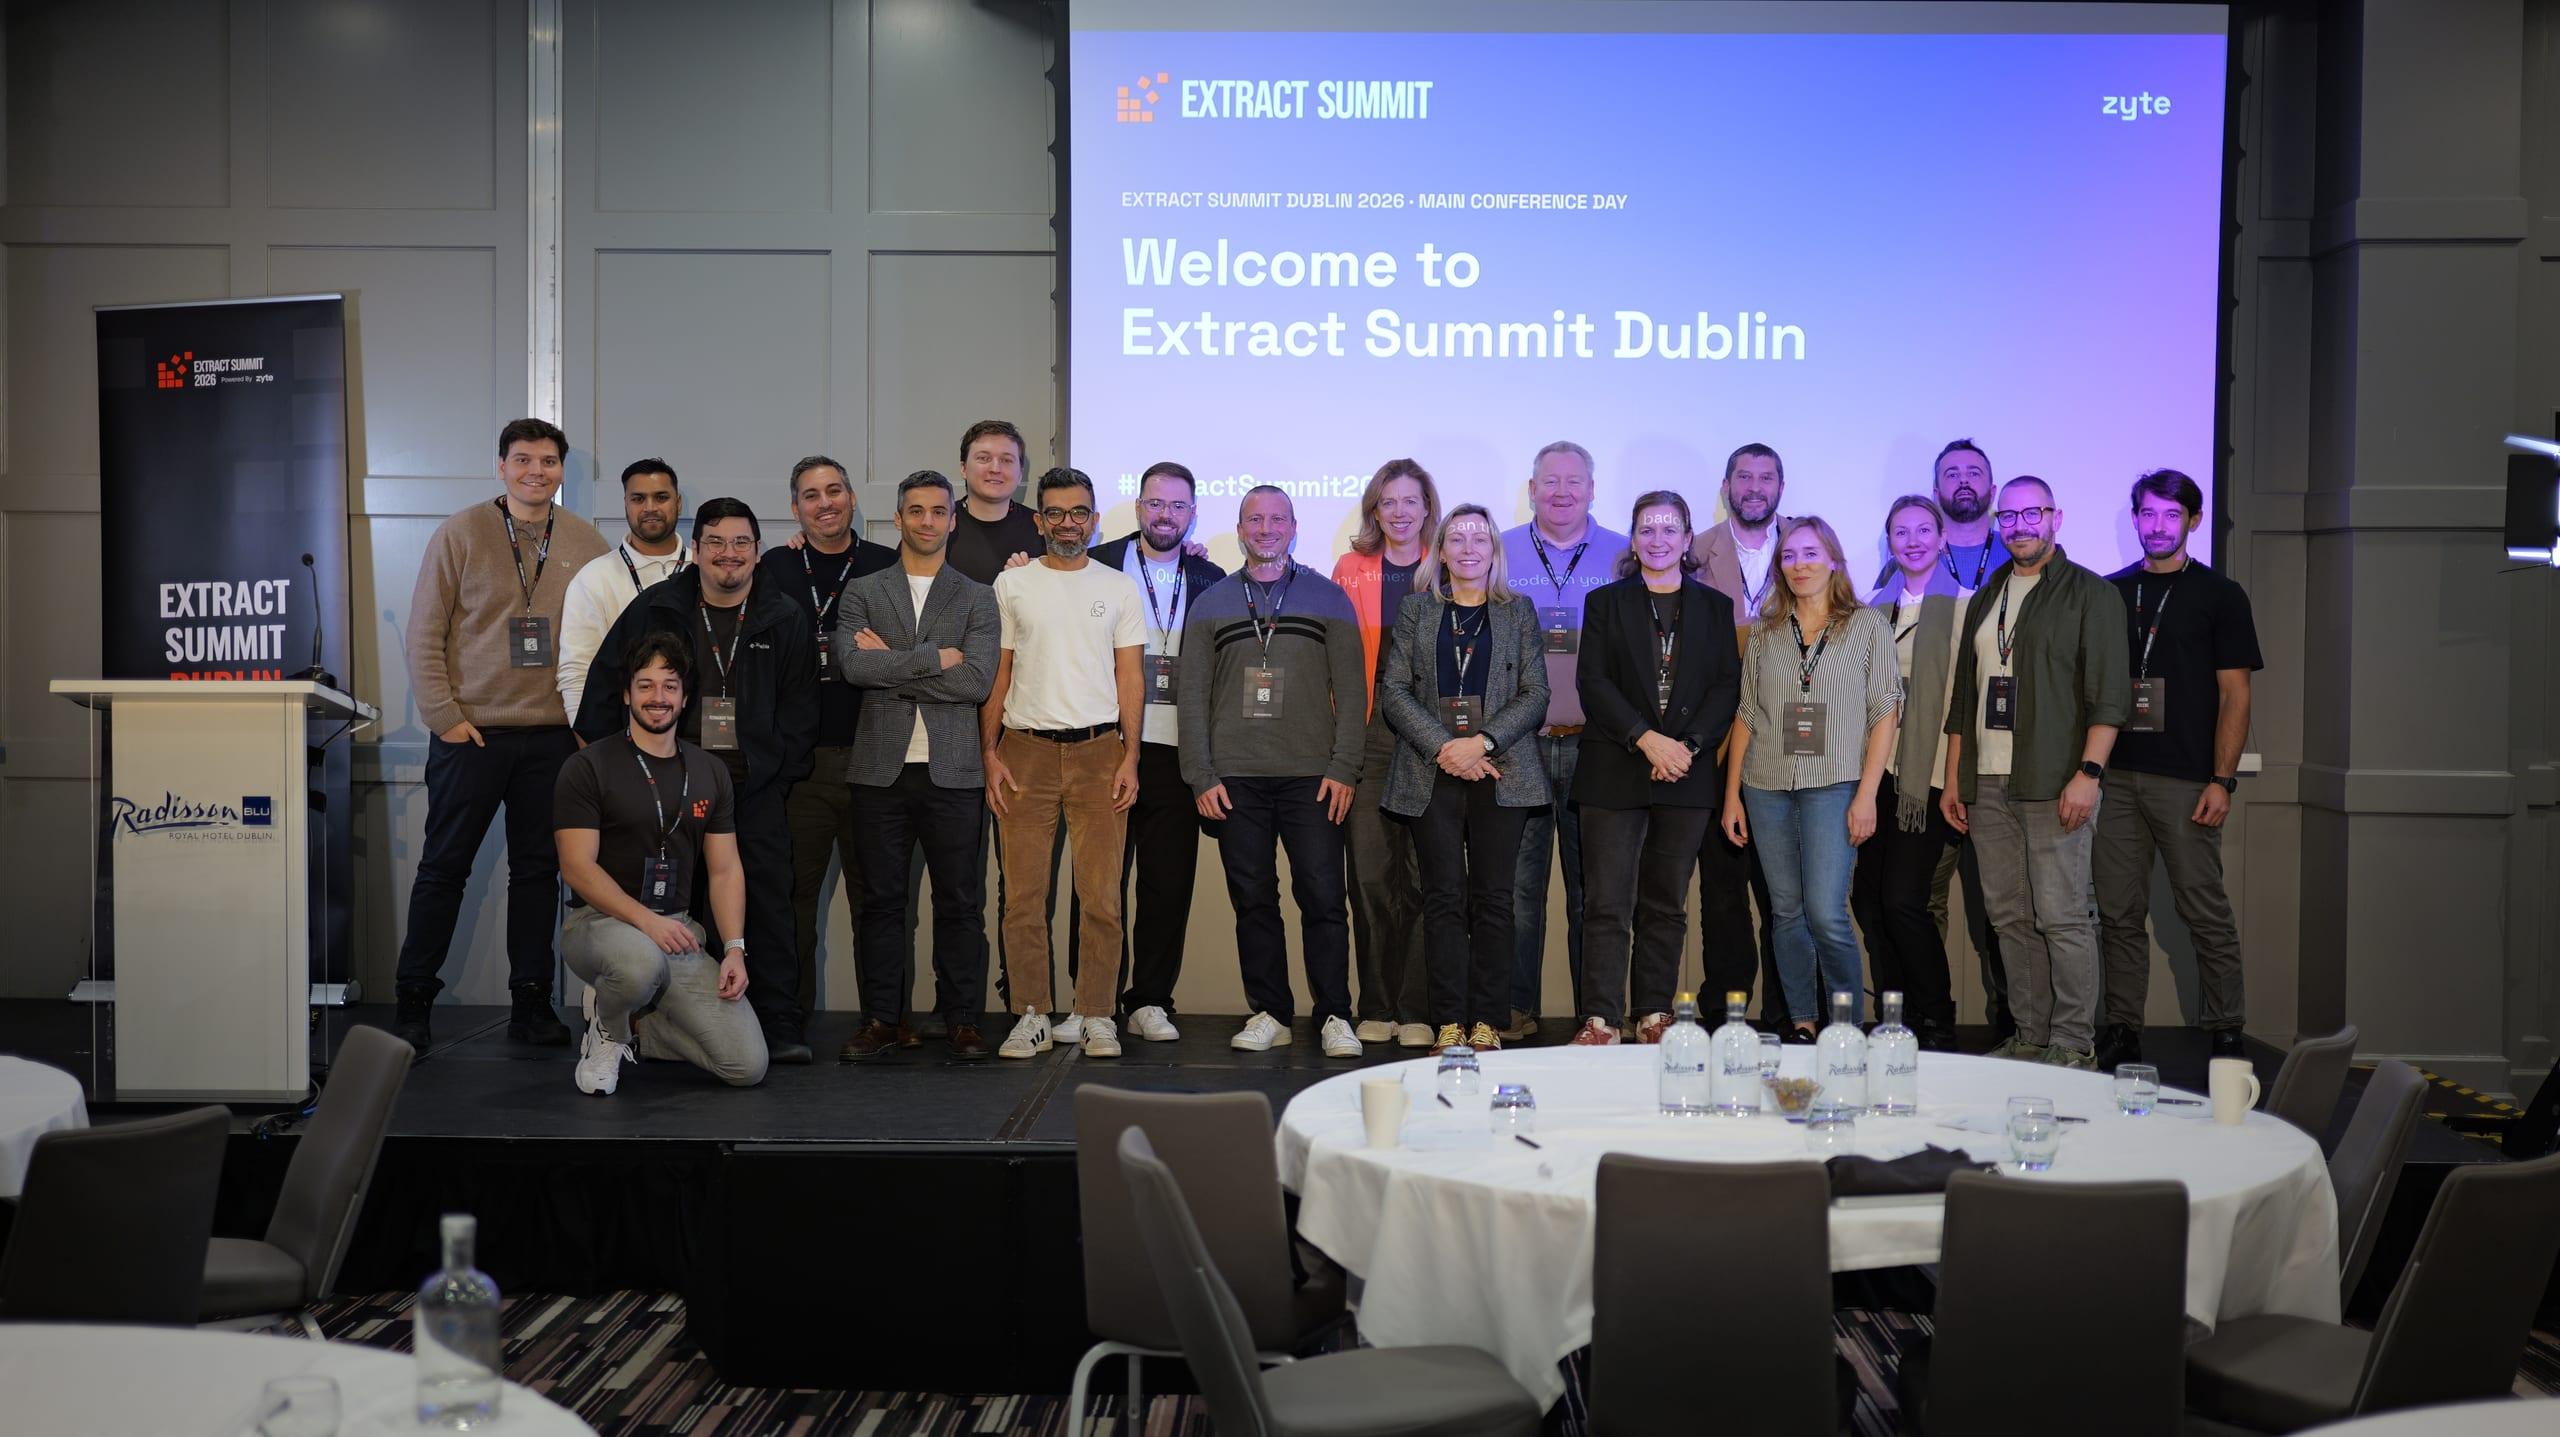
Five takeaways from Extract Summit Dublin
AI is making scraping code cheaper to write. Extract Summit Dublin explored the harder work that remains: access, infrastructure, maintenance and trust.
How do you manage the context window in Claude Code and other coding agents - like a ninja
Claude Code rarely runs out of context now, but you still pay for what you carry. 18 habits checked against the docs: /compact, /clear, caching, MCP.
What is a self-healing web scraper?
A self-healing web scraper detects when a site change breaks extraction, repairs the code within limits you set, proves the fix with tests, and escalates when it can't. What it fixes, what it doesn't, how the loop works and what a repair costs.
Self-healing scrapers: four things to put in place before an AI agent fixes your spiders
What decides whether a self-healing scraper's repair is any good: detection during the crawl, a specific failure report, extraction code the agent can target, and tests that can fail.
Web Scraping for RAG: Build a Reliable Pipeline with Zyte API, Qdrant and LangChain
Build a RAG pipeline that survives bot blocks and JavaScript pages: fetch LLM-ready Markdown with Zyte API, gate bad pages, and test it before deploying.
How to use browser DevTools for web scraping
Before you write a scraper, use Chrome or Firefox DevTools to find where the data lives, test selectors, check whether JavaScript is involved and spot the requests worth copying.
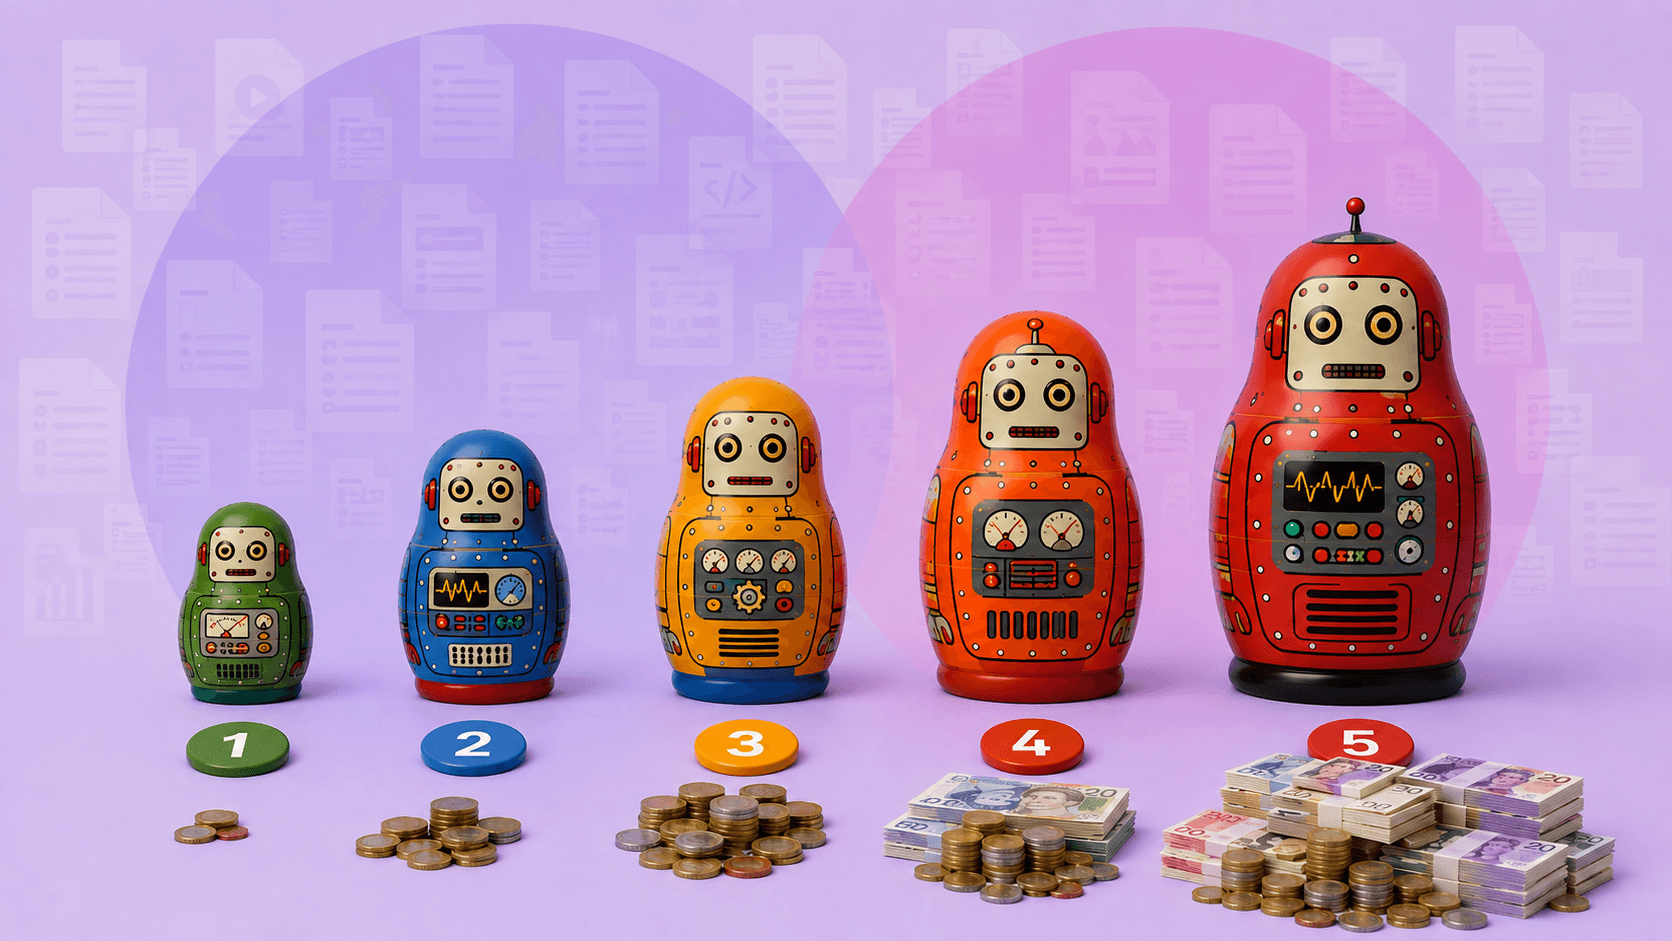
What web access actually costs - the tier picture
The barrier headlines sound extreme, but the cost data is more differentiated: 87.9% of top sites are Simple or Easy to access - and that means cost-effective.
12 things I use Zyte MCP for, ranked, with prompts and rules you can copy
What can you use Zyte MCP for? 12 uses, 11 tested, ranked, each with a copy-paste prompt, a CLAUDE.md rule, and a skill idea.
 Bluesky
 X
 Mastodon
 LinkedIn
 Facebook
 dev.to
 RSS feed
Zyte YouTube
Watch & learn
Video · Zyte YouTube
AI generated these Scrapy projects - why I won't ship them
July 7, 2026
Video · Zyte YouTube
Screenshot webpages with this Claude Skill and Zyte API
March 6, 2026
Video · Zyte YouTube
0% Hallucination? RAG + Web Scraping (Step-by-Step)
March 5, 2026
Video · Zyte YouTube
Generate HTML Parsing code the right way with Scrapy & Web Scraping Copilot
February 23, 2026
Video · Zyte YouTube
Zyte API Sessions - flexible cookie management maintaining control
February 6, 2026
Events & community